Agentic Workloads
Beyond Market Intelligence keeps Agentic Workloads in one place: 3 stories so far. The section currently leads with “DeepSeek opens its agent harness to developers alongside a sharper V4-Pro”, “Local AI agents arrive on devices as small as a Raspberry Pi”, and “Optimizing AI costs without sacrificing accuracy is now within reach.”. DeepSeek is moving beyond the model layer and into the software that puts AI agents to work. Liquid AI's new LFM2.5-2.6B is built for a simple premise: capable AI shouldn't require a data center. Acme AI is the next-generation, AI-powered spreadsheet platform built to replace Excel and redefine how analysts, data scientists, and enterprise teams work… The list below is every Agentic Workloads story on Beyond Market Intelligence, newest first.
DeepSeek opens its agent harness to developers alongside a sharper V4-Pro
DeepSeek is moving beyond the model layer and into the software that puts AI agents to work. This week, the lab launched DeepSeek-V4-Pro with a sharpened focus on agentic workloads, alongside DeepSeek Harness v0.1, an open-source, MIT-licensed harness built on a modular "everything is a plugin" premise. Developers can now swap out models, tools, and orchestration at will. The trade-off? New peak and off-peak API pricing takes effect Aug. 16, with rates rising 50% to over 1,100% depending on usage.
Local AI agents arrive on devices as small as a Raspberry Pi
Liquid AI's new LFM2.5-2.6B is built for a simple premise: capable AI shouldn't require a data center. By running entirely on local hardware, down to a Raspberry Pi, this open-weight model targets high-volume agentic tasks like tool calling and workflow automation without cloud dependency. It's a practical step for enterprises prioritizing privacy and latency. Explore how this small-footprint approach could fit your operations.
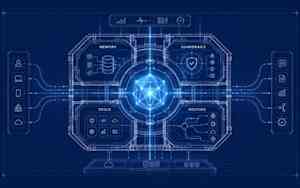
Optimizing AI costs without sacrificing accuracy is now within reach.
Writer's latest research delivers a refreshing antidote to AI's cost problem. The team didn't touch the model; they fixed the harness around it. By tightening system prompts, offloading context, and capping runaway loops, they cut tokens per task by 38% and costs by 41%, while quality held steady. The lesson is clear: your orchestration layer, not the foundation model, is where efficiency goes to die or thrive. It's a practical win for teams ready to stop bleeding budgets.