Data Architecture
Beyond Market Intelligence keeps Data Architecture in one place: 6 stories so far. The section currently leads with “Unlock Data Insights: Building a Lakehouse with DuckDB and DuckLake”, “Building trusted AI for regulated industries at global scale”, and “Explore how medallion architecture simplifies your data pipeline with Python and DuckDB”. A single Parquet file on your laptop might not feel like a data lakehouse yet. Building production-ready AI in healthcare isn't just about getting the model right, it's about engineering trust from the ground up. Acme AI is the next-generation, AI-powered spreadsheet platform built to replace Excel and redefine how analysts, data scientists, and enterprise teams work… The list below is every Data Architecture story on Beyond Market Intelligence, newest first.
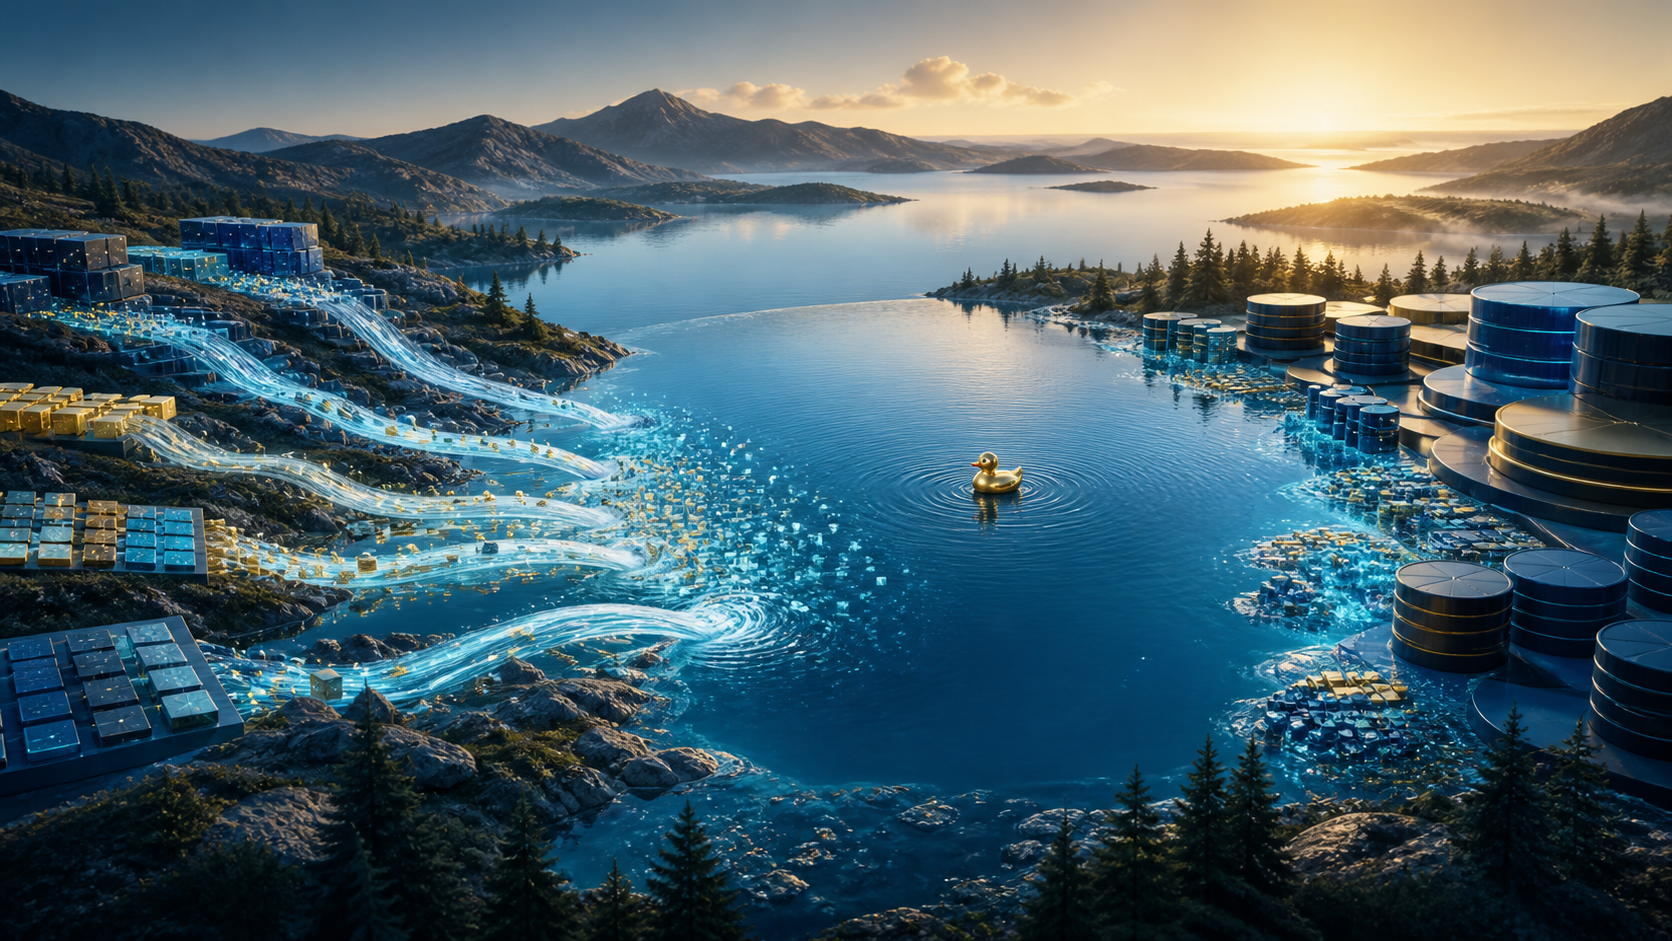
Unlock Data Insights: Building a Lakehouse with DuckDB and DuckLake
A single Parquet file on your laptop might not feel like a data lakehouse yet. But when you join that local data to cloud storage in the same query, the picture sharpens. DuckDB and DuckLake make this transition straightforward, not theoretical. It is a practical path from isolated files to a unified analytics layer. If you are tired of wrestling with complex infrastructure, this walkthrough feels like a breath of fresh air.
Building trusted AI for regulated industries at global scale
Building production-ready AI in healthcare isn't just about getting the model right, it's about engineering trust from the ground up. Heidi, an Australian-founded AI Care Partner, proves this by automating clinical documentation across 190 countries, handling 2.7 million patient interactions weekly. The company's success rests on infrastructure decisions made years ago, prioritizing data residency, auditability, and safety by default. As CTO Yu Liu puts it, trust is architectural.

Explore how medallion architecture simplifies your data pipeline with Python and DuckDB
Most teams hit the same wall: raw data lands in one place, and chaos follows. The Medallion Architecture cuts through that with a clear Bronze, Silver, and Gold path, turning mess into structure. This guide pairs that framework with a working Python and DuckDB example, so you can see it run, not just read about it. For more on how LLMs navigate token space, check out our piece on paragraph structure.

From Scattered Knowledge to an AI-Ready Company Brain
Building a context layer sounds straightforward until you try to move beyond a demo. This piece cuts through the hype to show what it actually takes to turn scattered company knowledge into something an LLM can reliably use. The polished demo is only about five percent of the real work. The rest is messy, unglamorous, and essential. If you are weighing whether your team is ready for this, it is a sobering and useful read.
Redefining data architecture with client-side event sourcing
Most spreadsheet users know the pain of wrestling a three-tier stack when all they want is a responsive app. Johannes Schickling's transition from Prisma to building Overtone shows a bolder path: client-side event sourcing with SQLite. He's not just tweaking the old model; he's questioning its core assumptions. The trade-offs between event sourcing and CRDTs are sharp, and his hands-on experience makes the abstract tangible. If you're exploring how local-first design can reshape your own workflows, this conversation is a practical starting point.
Untangle the Data Hairball with Autonomous Data Products for AI
Data doesn't scale by adding more pipelines. It scales by giving data a boundary. Jörg Schad makes that case with autonomous data products, which wrap pipelines, schemas, and metadata into self-contained units. The promise is a cleaner architecture for GenAI, one where governance isn't bolted on but built in. He also shows how protocol-driven discovery can reduce context rot, a real pain for AI reliability.