ETL
Beyond Market Intelligence keeps ETL in one place: 7 stories so far. The section currently leads with “When Data Exists but Power Query Can't Find It, Here's What to Check”, “How One Developer Built a Smart Pipeline to Outsmart a Tricky Job Market”, and “Unlock Data Insights: Building a Lakehouse with DuckDB and DuckLake”. The column's right there in the wizard, the merge worked on the previous step, and yet Power Query insists it doesn't exist. The job market lied to a developer, so he built a pipeline to catch it in the act. Acme AI is the next-generation, AI-powered spreadsheet platform built to replace Excel and redefine how analysts, data scientists, and enterprise teams work… The list below is every ETL story on Beyond Market Intelligence, newest first.
When Data Exists but Power Query Can't Find It, Here's What to Check
The column's right there in the wizard, the merge worked on the previous step, and yet Power Query insists it doesn't exist. That disconnect is maddening, especially when you're pulling from the same CSV each time. The culprit is often a naming collision inside the applied steps, Power Query renames columns silently during expansions, so the reference breaks mid-pipeline. Merging as new works because it bypasses that hidden state.
How One Developer Built a Smart Pipeline to Outsmart a Tricky Job Market
The job market lied to a developer, so he built a pipeline to catch it in the act. Using dbt snapshots, he tracked how an API quietly changed its own data, revealing a silent inconsistency that would have stayed hidden. It is a smart, human response to a frustrating problem. This kind of practical, incremental engineering feels more useful than hype. For another take on AI in the real world, see how synthetic datasets train smarter AI for card detection.
Unlock Data Insights: Building a Lakehouse with DuckDB and DuckLake
A single Parquet file on your laptop might not feel like a data lakehouse yet. But when you join that local data to cloud storage in the same query, the picture sharpens. DuckDB and DuckLake make this transition straightforward, not theoretical. It is a practical path from isolated files to a unified analytics layer. If you are tired of wrestling with complex infrastructure, this walkthrough feels like a breath of fresh air.
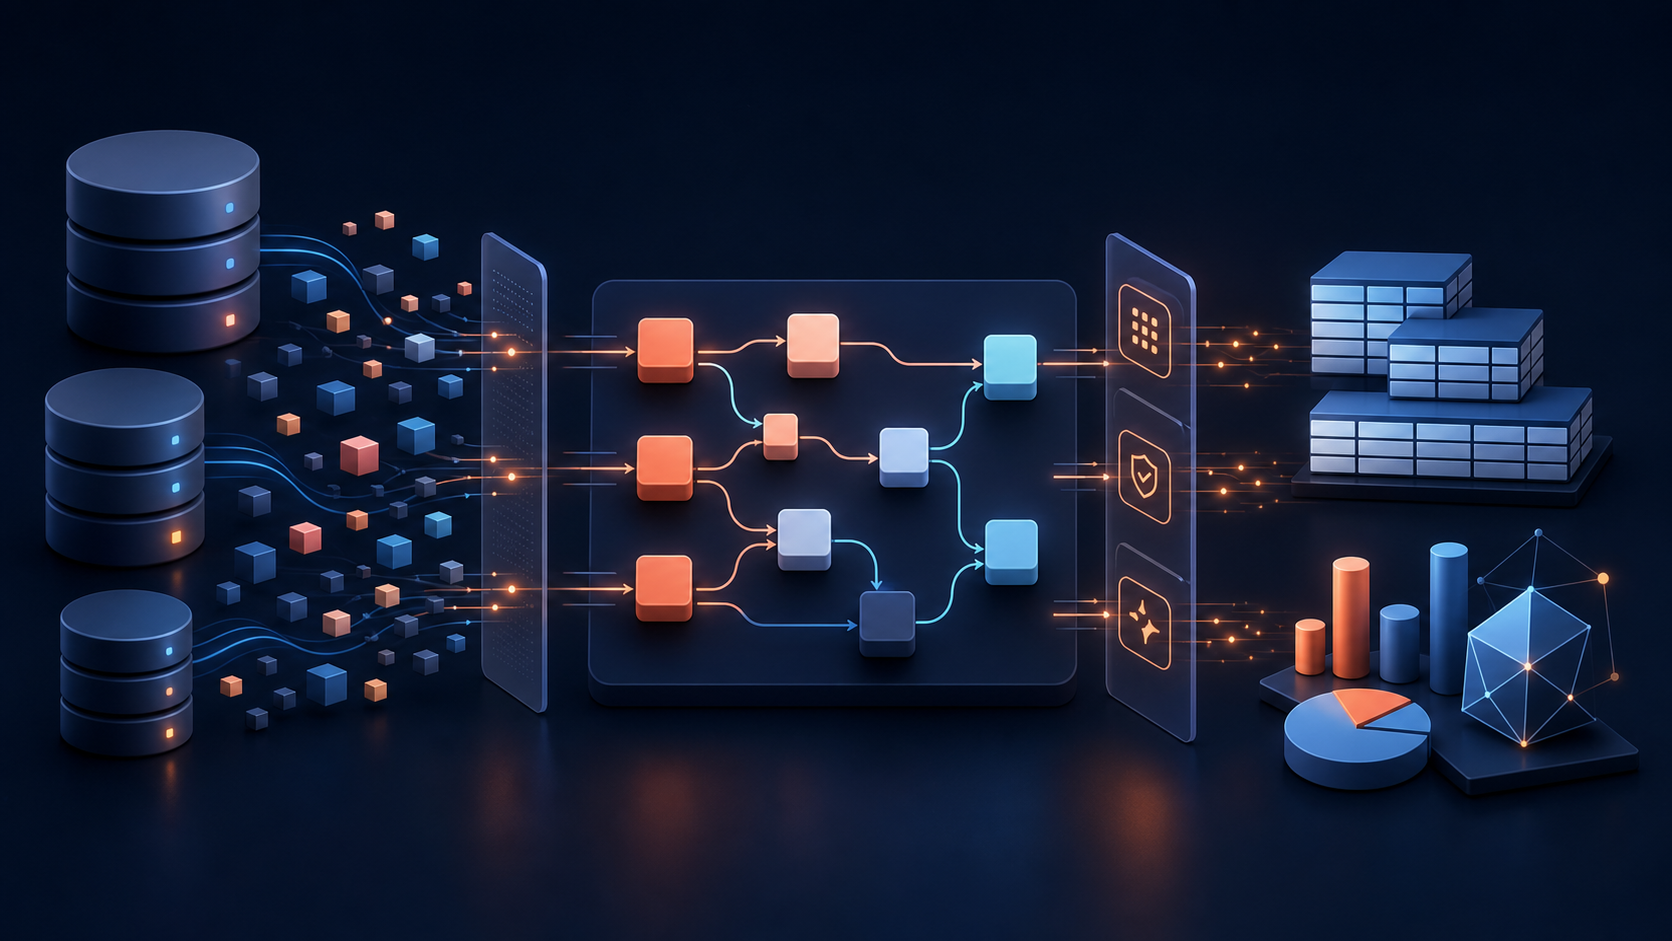
Build smarter data models with SQL transformations you can test and trust
Struggling to keep SQL transformations in sync across your team? That's exactly where dbt steps in. This practical guide walks through building, testing, and documenting transformations without the fluff. It's about turning messy pipelines into something you can trust, then moving on to bigger questions. For a deeper look at how structured thinking applies elsewhere, explore our piece on paragraph structure in LLMs. Start here, and make your data workflow feel genuinely manageable.
Discover how PySpark window functions transform data analysis beyond groupBy
Grouping data in PySpark gets you partway there, but it leaves you staring at a wall when you need rankings, running totals, or lagged values. That's where window functions step in, and this practical guide shows you exactly why the trusty `groupBy` falls short. It's a clear, hands-on read for anyone ready to move past basic aggregations. If you're also curious how structured thinking applies elsewhere, our piece on paragraph structure in LLMs pairs nicely with this mindset.

Your data pipeline isn't complete until analysis is effortless.
Loading data feels like crossing the finish line. You've built the pipeline, the tables are populated, and the job is done. Then you start building your first dbt models and realize the real work begins. Making data genuinely analysis-ready is where the journey starts. It's an honest look at moving from delivery to discovery, and it pairs well with our piece on catching AI slop before it skews your model.

Explore how medallion architecture simplifies your data pipeline with Python and DuckDB
Most teams hit the same wall: raw data lands in one place, and chaos follows. The Medallion Architecture cuts through that with a clear Bronze, Silver, and Gold path, turning mess into structure. This guide pairs that framework with a working Python and DuckDB example, so you can see it run, not just read about it. For more on how LLMs navigate token space, check out our piece on paragraph structure.