explainability
explainability at Beyond Market Intelligence is a file of 5 stories. The newest of them: “See Why AI Agents Pick the Tools They Do with Kiji Inspector”, “Understanding technical roots to prevent AI safety failures”, and “Why Agentic AI Fraud Defies Traditional Explainability Tools”. Hannes Hapke shows how Dataiku's open-source Kiji Inspector applies Sparse Autoencoders directly to decision tokens, exposing *why* an AI agent picks one tool over another. Safety failures in AI often look like human error, but the real culprit is usually hiding in the technical architecture. Acme AI is the next-generation, AI-powered spreadsheet platform built to replace Excel and redefine how analysts, data scientists, and enterprise teams work… The list below is every explainability story on Beyond Market Intelligence, newest first.
See Why AI Agents Pick the Tools They Do with Kiji Inspector
Hannes Hapke shows how Dataiku's open-source Kiji Inspector applies Sparse Autoencoders directly to decision tokens, exposing *why* an AI agent picks one tool over another. This moves past superficial chain-of-thought narratives into causal ablation and layer activation extraction. For architects and engineering leaders building production monitoring workflows, it's the kind of transparency that turns agent behavior from guesswork into something you can actually inspect.
Understanding technical roots to prevent AI safety failures
Safety failures in AI often look like human error, but the real culprit is usually hiding in the technical architecture. The choices engineers make about data pipelines, model dependencies, and system boundaries create the conditions for harm long before any user interacts with the output. Understanding these technical roots isn't just academic, it's the difference between reactive fixes and genuine prevention. Our related piece on designing distributed systems for decisions, not just functions, explores how architecture choices shape outcomes in practice.
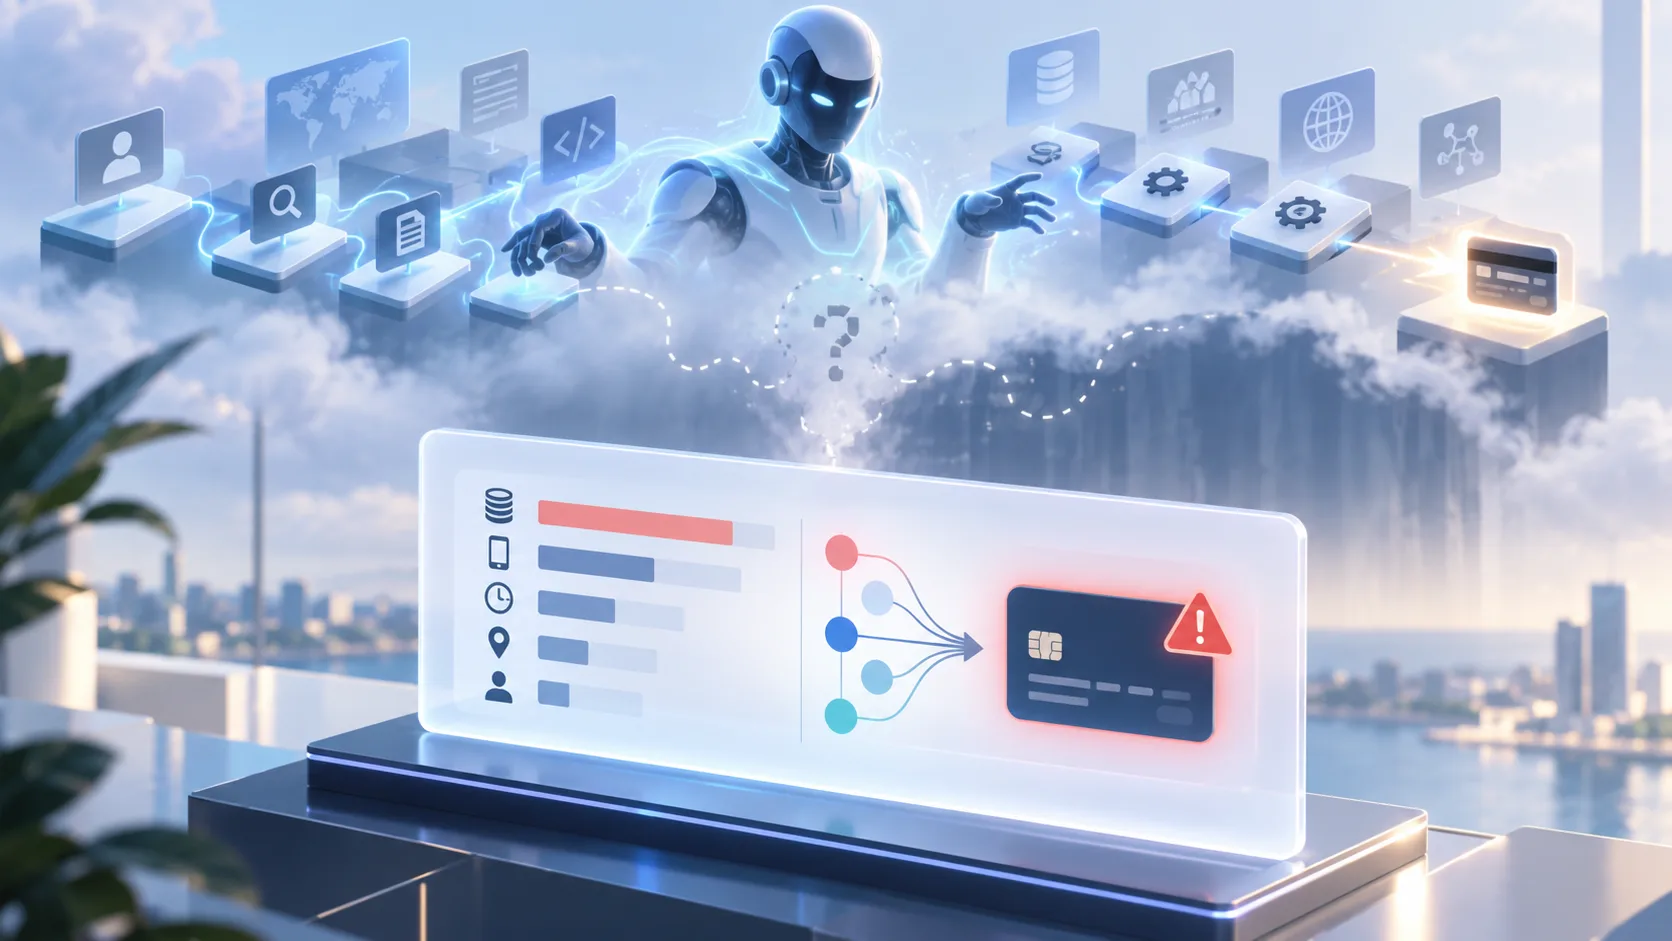
Why Agentic AI Fraud Defies Traditional Explainability Tools
SHAP has long been the go-to tool for explaining fraud predictions, but autonomous agents break that framework. When an AI agent makes a series of decisions across multiple systems, a single feature-importance score can't capture the cascading logic. This gap matters because fraud detection is becoming more dynamic, not less. It's a problem worth confronting directly, and one that challenges how we define accountability in AI-driven security. If you're tracing how these systems learn, our guide to distributed training offers useful context.
Exploring what end-to-end machine learning looks like in Rust
Millwright is asking a question most ML tooling avoids: can Rust serve as a common execution layer across the entire classical lifecycle, from training to monitoring? The project doesn't aim to replace Python's ecosystem. Instead, it builds a unified abstraction over existing crates, owning a small data boundary to make diverse backends work together. That's a pragmatic, honest approach. The focus on integration over reinvention is the right instinct.
Understand Prompt Injection by Mastering How Roles Shape AI Behavior
Prompt injection is often treated like a parlor trick, but it's a window into how LLMs actually think. This breakdown from katxwoods digs into the mechanics, showing why roles aren't just instructions, they're the keys to the system's logic. If you've ever wondered why a simple "ignore previous" works, this is your answer. It's a sharp, practical read that rewards your curiosity. For a broader look at how these systems are built, our guide to distributed algorithms pairs well here.