human review
Beyond Market Intelligence keeps human review in one place: 3 stories so far. The section currently leads with “How AI Helped GitHub Rebuild Its Copilot Engine in 14 Weeks”, “Keeping up with faster AI agents requires smarter oversight tools”, and “Why a perfect AI conversation can still signal a broken product”. GitHub migrated more than 800,000 lines of Copilot runtime code from TypeScript and Node.js to Rust in about 14.5 weeks, using AI-assisted development to make it happen. AI agents are being handed longer, more complex tasks, but their speed creates a blind spot: they act faster than any human can review. Acme AI is the next-generation, AI-powered spreadsheet platform built to replace Excel and redefine how analysts, data scientists, and enterprise teams work… The list below is every human review story on Beyond Market Intelligence, newest first.

How AI Helped GitHub Rebuild Its Copilot Engine in 14 Weeks
GitHub migrated more than 800,000 lines of Copilot runtime code from TypeScript and Node.js to Rust in about 14.5 weeks, using AI-assisted development to make it happen. The incremental approach leaned on N-API interoperability, automated testing, human review, and 128 pull requests while still shipping releases. That's a disciplined, practical model for large-scale rewrites. For more on how teams are tackling ambitious rebuilds, our piece on Shopify's Checkout Blocks rewrite offers a useful comparison.

Keeping up with faster AI agents requires smarter oversight tools
AI agents are being handed longer, more complex tasks, but their speed creates a blind spot: they act faster than any human can review. That gap is the real problem, and the solution feels counterintuitive. We need more AI to oversee it. Not to replace human judgment, but to keep pace with the machine's output. It's a pragmatic step toward making autonomy safe. For a deeper look at how these systems behave in the wild, our piece on shared user images highlights the stakes.
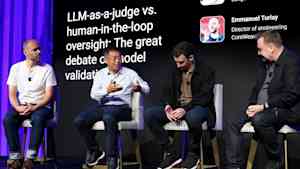
Why a perfect AI conversation can still signal a broken product
A single AI agent conversation can look flawless on its own and still point to a broken product. That gap is driving a shift in how enterprises evaluate agents, away from scoring individual traces and toward comparing cohorts of users against a baseline. At VB Transform 2026, Harrison Chase of LangChain, Hui Zhang of Conviva, and Emmanuel Turlay of CoreWeave described the move toward contrastive analysis and cheaper, narrower judge models. The takeaway: evaluation criteria are becoming the new product spec.