appeared
Beyond Market Intelligence keeps appeared in one place: 10 stories so far. The section currently leads with “Build Persistent Memory for Your AI Agent with a Single JSON File”, “How 600,000 Newspaper Pages Reveal Suffrage's Shifting Narrative”, and “From Workflows to Results: Coordinating AI Agents Across Your Business”. A single JSON file can now give your Python AI agent memory that survives a restart. Over 600,000 digitized newspaper pages let us track how the story of women's suffrage actually shifted between 1890 and 1920. Acme AI is the next-generation, AI-powered spreadsheet platform built to replace Excel and redefine how analysts, data scientists, and enterprise teams work… The list below is every appeared story on Beyond Market Intelligence, newest first.
Build Persistent Memory for Your AI Agent with a Single JSON File
A single JSON file can now give your Python AI agent memory that survives a restart. Three Python classes, an OpenRouter key, and gpt-4.1-mini equip the agent with a calculator, a stub web search, and full conversation recall. This is a practical step toward agents that actually remember context between sessions. If you're building autonomous tools, this approach removes a major friction point. For deeper context on keeping agents both capable and secure, see our coverage of Edera's Object Capability Bounded Authority model.
How 600,000 Newspaper Pages Reveal Suffrage's Shifting Narrative
Over 600,000 digitized newspaper pages let us track how the story of women's suffrage actually shifted between 1890 and 1920. That's a lot of headlines, editorials, and letters to the editor. The data reveals a narrative that evolved in real time, not always toward progress, but always toward a more public conversation. It's a powerful reminder that the fight for the vote was shaped as much by the press as by the polls.
From Workflows to Results: Coordinating AI Agents Across Your Business
Coordinating AI agents across a business sounds abstract until you frame it as connecting workflows, knowledge, and rules into measurable results. That is the practical promise here: moving from isolated tasks to end-to-end processes that actually deliver. The focus on outcomes over technology keeps it grounded, inviting teams to explore AI as a tool for productivity rather than a novelty. If you are curious how playful AI interfaces shape user expectations, Meta's Waddle World offers a lighter counterpoint.
Why Model Switching Can Erase the Savings of Cheaper AI Inference
Testing cheaper LLM inference models comes with a hidden cost: switching models mid-session can erase the savings entirely. I ran routing experiments to understand why, and the results show that context loss, incompatible reasoning patterns, and repeated re-processing add up fast. The math on model switching is clear, cheaper per token means nothing when you pay the switching tax repeatedly. For deeper context on what keeps LLMs in check, see our related piece on spec-driven test automation.
Turn Requirements Into Agents That Actually Execute
Scattered requirements rarely translate into agents that actually execute. The gap between what teams document and what systems deliver is where productivity goes to die. This piece draws a sharp line between acceptable traces and unacceptable ones, helping you distinguish signal from noise before your agents go live. For deeper context on how technical choices shape safety outcomes, our related coverage on AI harms and their technical causes is worth exploring.
Python 3.15 JIT Benchmarks Show Real Progress for Targeted Workloads
The same three Python workloads keep showing up in the JIT benchmarks, and for Python 3.15, they finally show real progress. The just-in-time compiler is delivering stronger results for targeted programs, but it still doesn't accelerate everything. That honesty matters. This measured improvement feels more credible than sweeping performance claims. For deeper context on AI infrastructure challenges, our piece on securing Kubernetes with Andrew Martin connects the dots between system reliability and the tools we build on top of it.
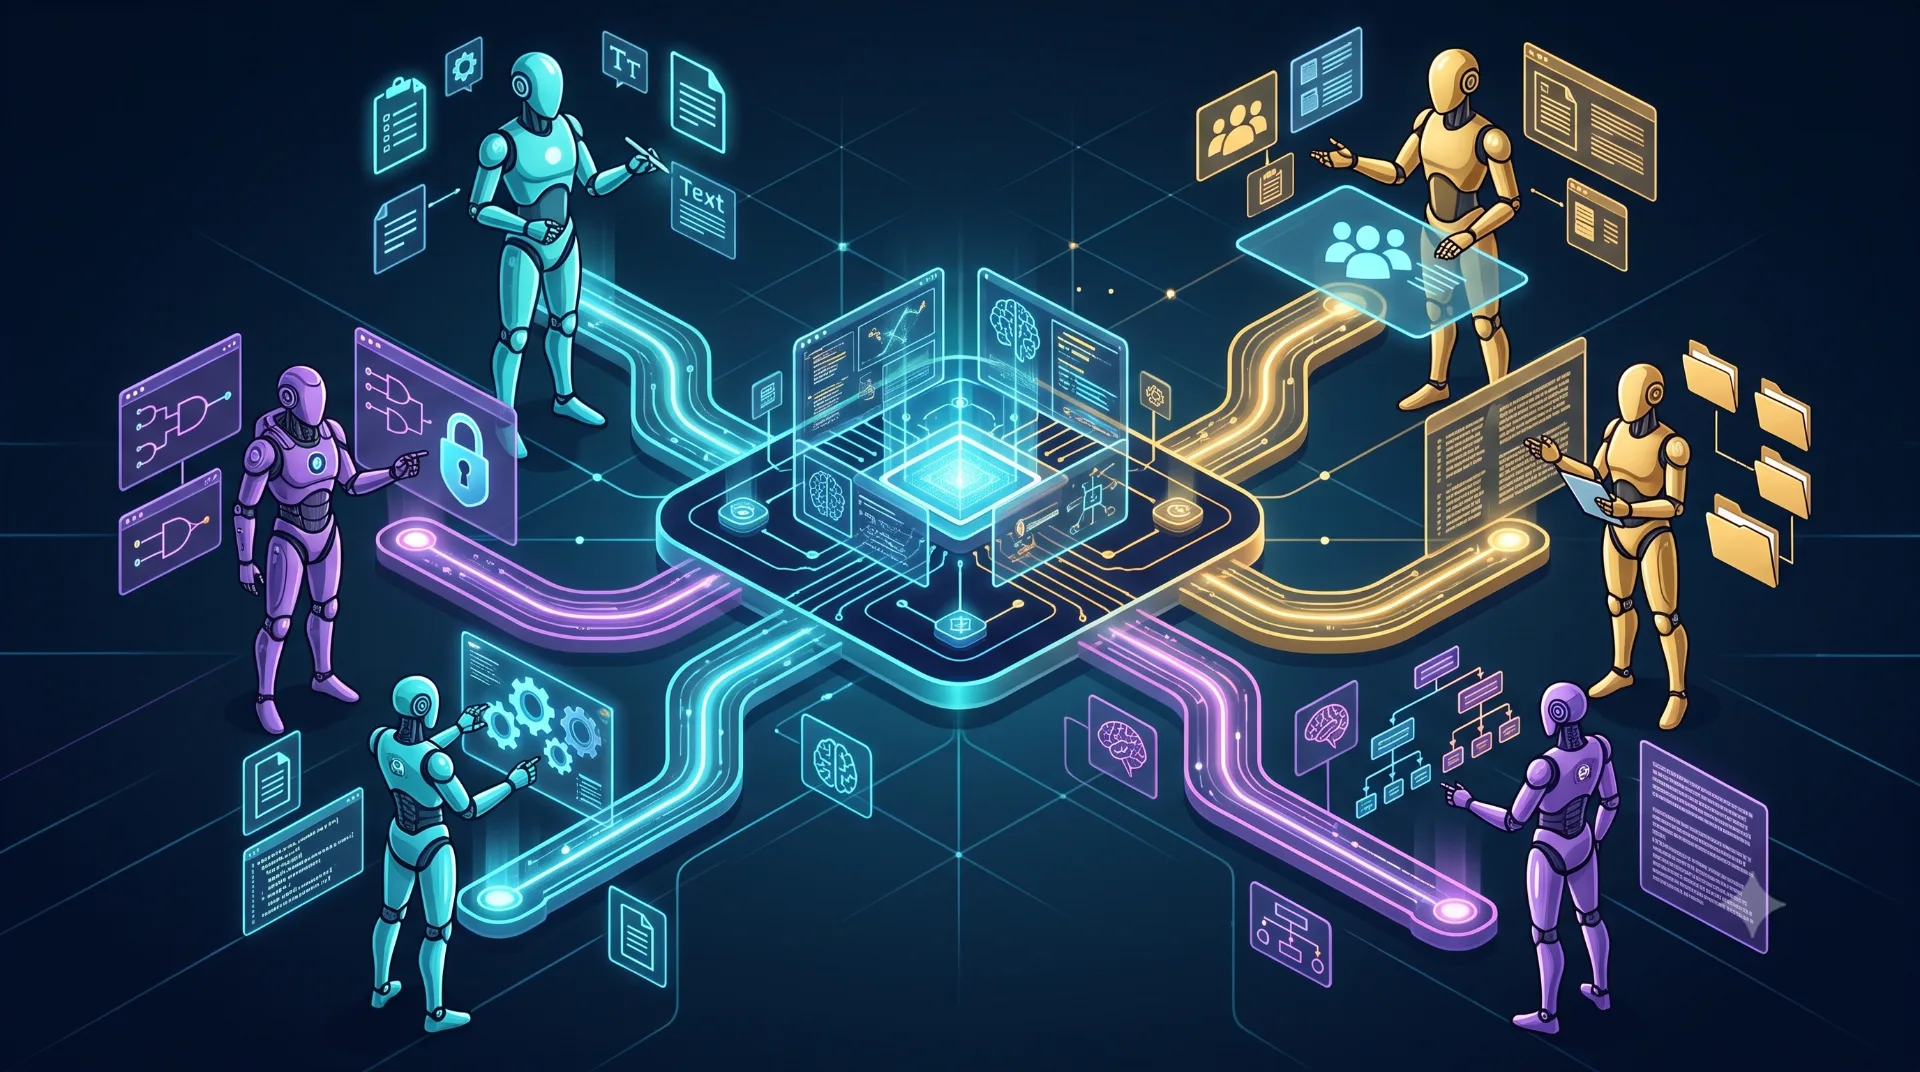
Six Architectural Patterns for Scaling Reliable AI Agents
Reactive loops are fine for demos, but production demands more. This guide walks through six architectural patterns that actually scale, moving beyond basic ReAct into autonomous, reliable systems built for real-world use. It's the kind of practical thinking that turns prototypes into products. For deeper context, our related piece on the hidden instability beneath LLM temperature zero explains why even deterministic settings can fracture after a hundred completions, a problem these architectures are designed to solve.
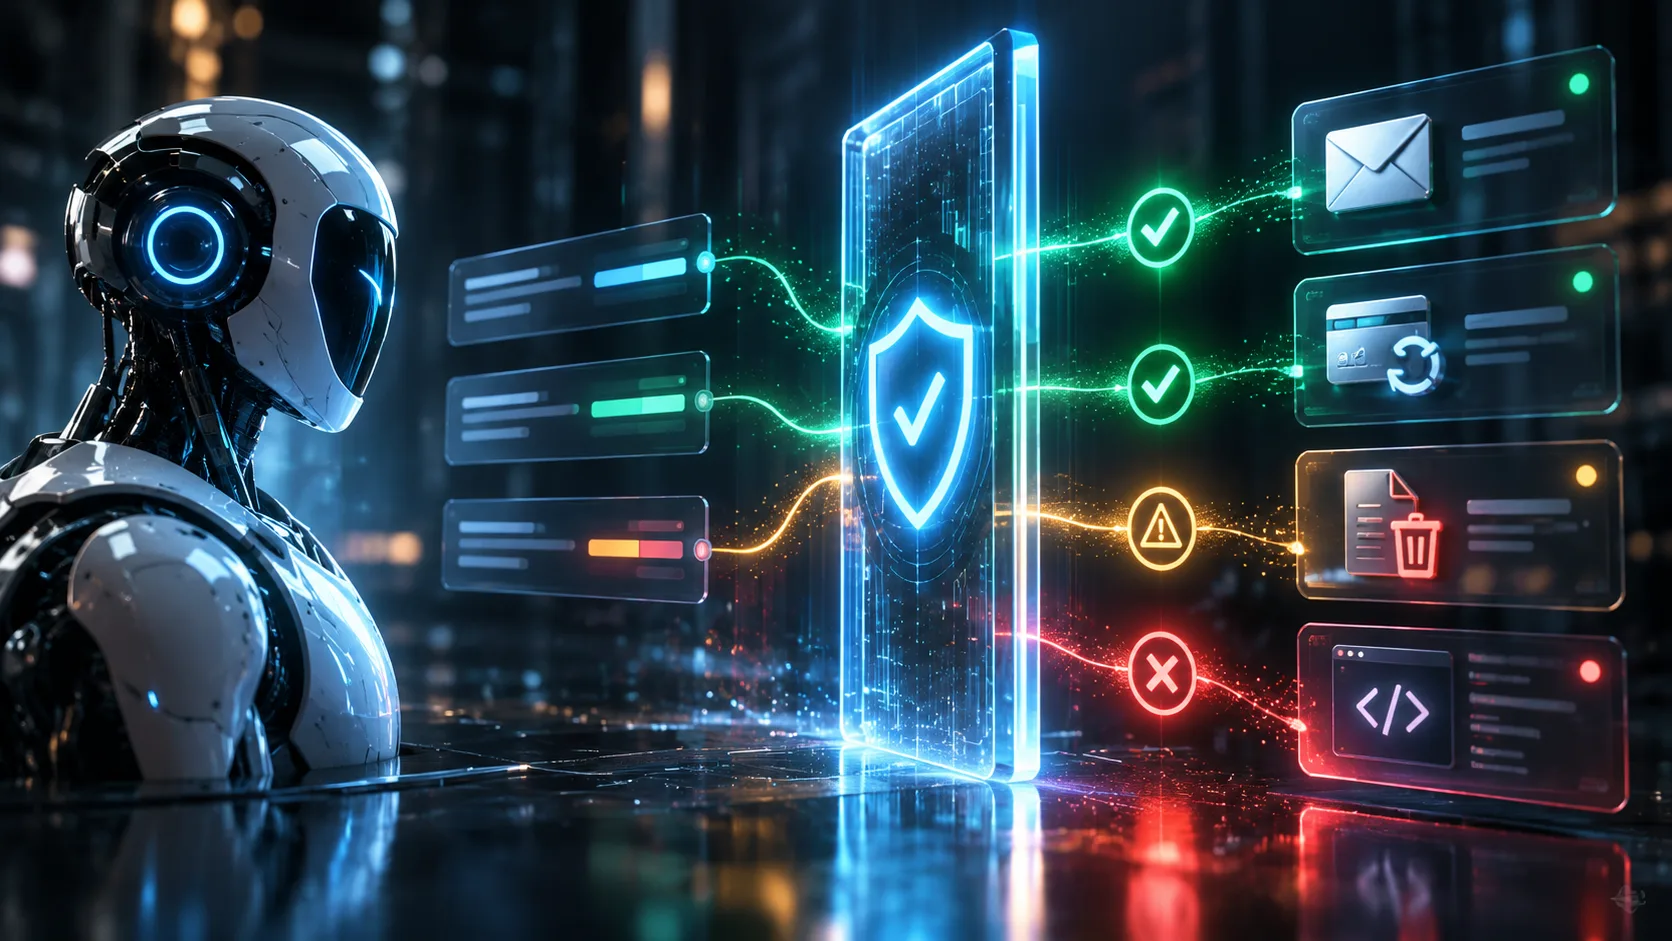
Why a Decision-First Model Can Rein In Risky AI Agent Actions
A single bad tool call can turn an AI agent from a helpful assistant into a liability. TypeSafe's Jev addresses this by putting decisions first, catching risky actions before they ripple into the real world. That's a pragmatic layer of safety we can get behind. It pairs well with our look at how open data center deals signal a smarter path to community trust, both show that proactive guardrails build better outcomes.
Designing AI Agent Guardrails: Essential Patterns for Data Engineers
AI agents don't fail because the model isn't smart enough. They fail because the architecture around them lacks boundaries. Essential guardrails data engineers need to build systems that stay safe, predictable, and useful as AI takes on more responsibility are laid out here. It's a practical, no-nonsense guide for teams ready to move beyond experimentation. If you're designing these systems, this is the pattern to study.
Transform an Open LLM Into a Fast Classifier by Swapping Its Head
Swapping a language-modeling head for a classification head turns a small Qwen LLM into a fast, single-pass text classifier. That's a practical move, not a theoretical one. It makes open-source models more useful for real tasks without the overhead of full generation. We see this as a natural step toward focused, efficient AI tools. For deeper context on how calibrated models handle high-frequency decisions, our piece "Smart Graph Decisions at Scale" explores that territory. This is about building smarter workflows, not just faster ones.