automated testing
automated testing at Beyond Market Intelligence is a file of 8 stories. The newest of them: “Explore how Foresight AI helps reliability teams test and fix failures faster”, “How AI Helped GitHub Rebuild Its Copilot Engine in 14 Weeks”, and “Verify Your AI Code: Ensuring Intent Without Reading a Single Line”. Reliability teams have long relied on reactive troubleshooting, waiting for incidents to reveal weaknesses. GitHub migrated more than 800,000 lines of Copilot runtime code from TypeScript and Node.js to Rust in about 14.5 weeks, using AI-assisted development to make it happen. Acme AI is the next-generation, AI-powered spreadsheet platform built to replace Excel and redefine how analysts, data scientists, and enterprise teams work… The list below is every automated testing story on Beyond Market Intelligence, newest first.
Explore how Foresight AI helps reliability teams test and fix failures faster
Reliability teams have long relied on reactive troubleshooting, waiting for incidents to reveal weaknesses. Gremlin's general availability of Foresight AI flips that model. It actively analyzes services for potential failures, recommends fixes, and then reruns tests to confirm the solution works. This agentic approach transforms testing from a manual burden into an automated cycle of discovery and correction. For those exploring how to keep complex systems stable, Foresight AI offers a practical path forward.

How AI Helped GitHub Rebuild Its Copilot Engine in 14 Weeks
GitHub migrated more than 800,000 lines of Copilot runtime code from TypeScript and Node.js to Rust in about 14.5 weeks, using AI-assisted development to make it happen. The incremental approach leaned on N-API interoperability, automated testing, human review, and 128 pull requests while still shipping releases. That's a disciplined, practical model for large-scale rewrites. For more on how teams are tackling ambitious rebuilds, our piece on Shopify's Checkout Blocks rewrite offers a useful comparison.
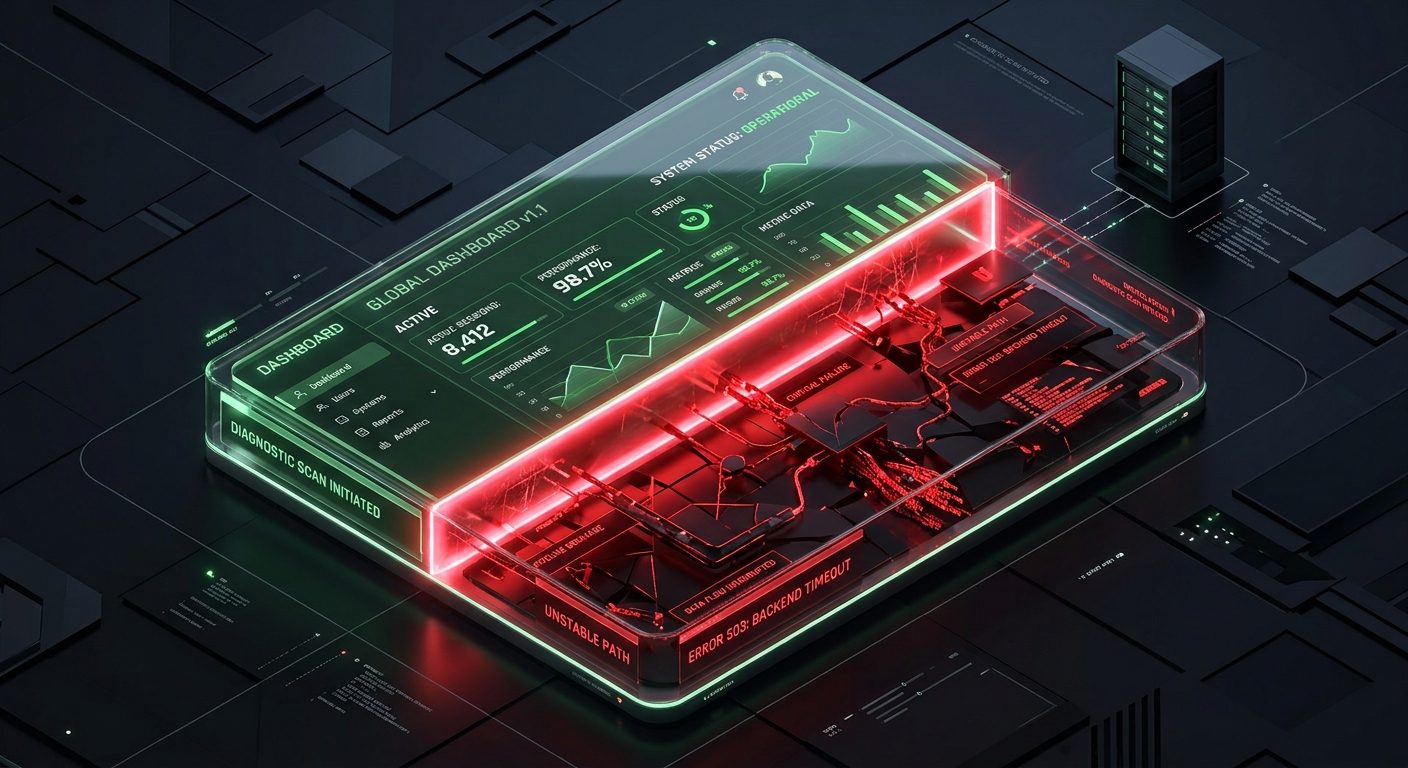
Verify Your AI Code: Ensuring Intent Without Reading a Single Line
Generated code can feel like a black box, even when it works. But when it fails silently, the cost is more than a bug; it's a breach of trust in your own workflow. A practical path to verify your app's intent without wading through every line is offered. It's a smart, accessible approach for anyone tired of guessing what the AI actually did. If you're exploring how LLMs reason, our guide to paragraph structure adds useful context on their inner logic.
Unlocking iOS 27 Virtualization for Security Research and Testing
The vphone-cli project brings full iOS 27 virtualization to Apple Silicon, built on Apple's own Virtualization.framework rather than emulation. That distinction matters. It means security researchers and developers testing automated workflows can run a complete iOS system with native performance, opening doors for deeper reverse engineering and more reliable testing. We're watching this closely because it removes a major barrier to practical, hands-on experimentation. For those feeling the pressure of evolving iOS development, this feels like a step toward simpler, more accessible tooling.
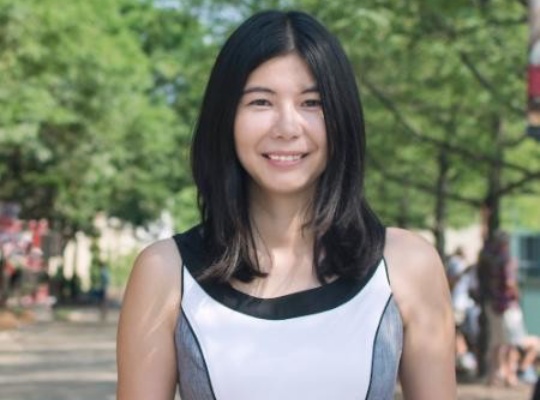
Simulation-Driven Testing Turns AI Agents from Demo to Production Reality
Most AI agents never leave the demo room. Zhou Yu sees that bottleneck clearly, and she's addressing it head-on with simulation-driven testing that tackles compliance and reliability before deployment. Her work with Columbia and Arklex AI uses synthetic user personas and trajectory entropy to stress-test multi-turn agents, catching edge cases that typically slip through. It's practical, human-centered engineering. For a deeper look at how AI moves beyond the lab, explore our related piece on unlocking enterprise potential.

What AI Code Debugging Reveals About Missing Information Gaps
Twenty-eight debugging experiments point to a clear truth: AI coding tools don't stumble on complexity as much as they do on missing information. That's a refreshingly precise diagnosis, one that shifts the conversation from raw capability to practical context. For anyone who's felt the limits of AI harnesses, this is a nudge to look closer at what's omitted, not just what's miscomputed. It's a smart, human-centered read.
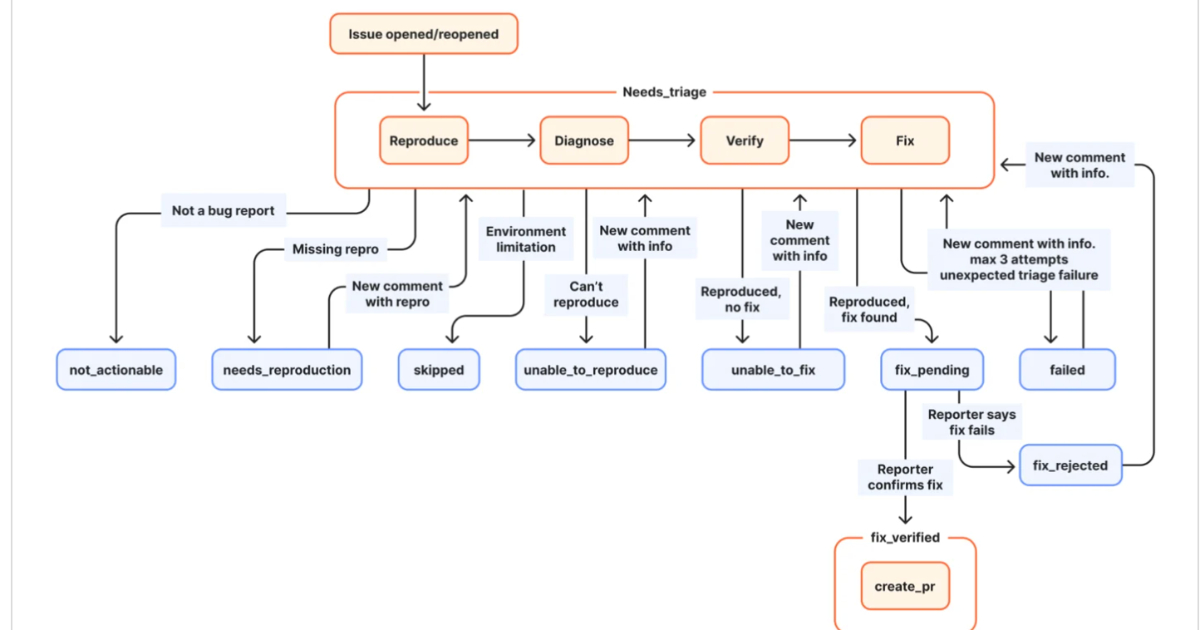
How AI agents triaged 85% of Astro's GitHub issues for Cloudflare
Astro's maintainers were drowning in GitHub issues, so they let AI agents take over triage. The result: an 85% cut in that workload, giving developers time back to focus on the work that matters. This isn't about removing humans; it's about making their role more meaningful. Cloudflare's approach, built on Workers with a human-in-the-loop, shows how agentic workflows can handle the noise. It's a practical win for open source, and it pairs well with our guide on distributed training algorithms.
Evaluate AI Coding Agents with These Top Open-Source Benchmarks
Choosing the right benchmark is the first step toward building an AI coding agent you can actually trust. In 2026, the landscape has matured well beyond simple unit tests, with tools like SWE-bench, Terminal-Bench, and SlopCodeBench offering distinct lenses on real-world performance. We break down the top 10 open-source options to help you navigate the noise. If you are questioning how these models handle nuance, our piece on talking to an AI clone offers a timely perspective on the human side of the equation.