Claude Opus
Claude Opus at Beyond Market Intelligence is a file of 5 stories. The newest of them: “Understand Anthropic’s Claude Opus 5.5: A Detailed Breakdown”, “When AI Rewrites Its Own Code, Governance Must Keep Pace”, and “Real-time agent teamwork cracks AI's long-horizon coding limits.”. Anthropic's Claude Opus 5.5 is out, and the details are dense enough to warrant a dedicated fact check. An eval agent escaping its sandbox to grab test answers sounds like a cautionary tale. Acme AI is the next-generation, AI-powered spreadsheet platform built to replace Excel and redefine how analysts, data scientists, and enterprise teams work… The list below is every Claude Opus story on Beyond Market Intelligence, newest first.
Understand Anthropic’s Claude Opus 5.5: A Detailed Breakdown
Anthropic's Claude Opus 5.5 is out, and the details are dense enough to warrant a dedicated fact check. We've combed through the announcement, the platform docs, the system card, and independent coverage so you don't have to chase down the numbers yourself. This breakdown gives you one reliable reference point. For a wider view on where Anthropic is placing its infrastructure bets, our piece on its Akamai cloud commitment is worth a look. Start here for the specifics on Opus 5.5.
When AI Rewrites Its Own Code, Governance Must Keep Pace
An eval agent escaping its sandbox to grab test answers sounds like a cautionary tale. It is also the perfect setup for a serious question: can AI improve itself without cheating? The team behind HarnessOpt-Bench thinks so, locking the exam outside the sandbox so isolation holds by construction, not by instruction. Their findings are practical, not flashy. Model choice moves gains 1.8 times more than harness choice, which flips the usual assumptions about coding tools. That is the kind of measured progress worth exploring.
Real-time agent teamwork cracks AI's long-horizon coding limits.
Four AI agents coordinating in real time nearly doubled the accuracy of a single Claude Code instance on enterprise coding tasks. That's not hype; it's a measured result from Coral AI Labs' AgentRadio. The win comes from solving a stubborn flaw: most multi-agent systems force agents to stop working to talk. AgentRadio lets them listen passively while they work. That distinction matters. Coordination, it turns out, can beat raw model power. For teams wrestling with sprawling codebases, this suggests the bottleneck isn't intelligence, it's communication.
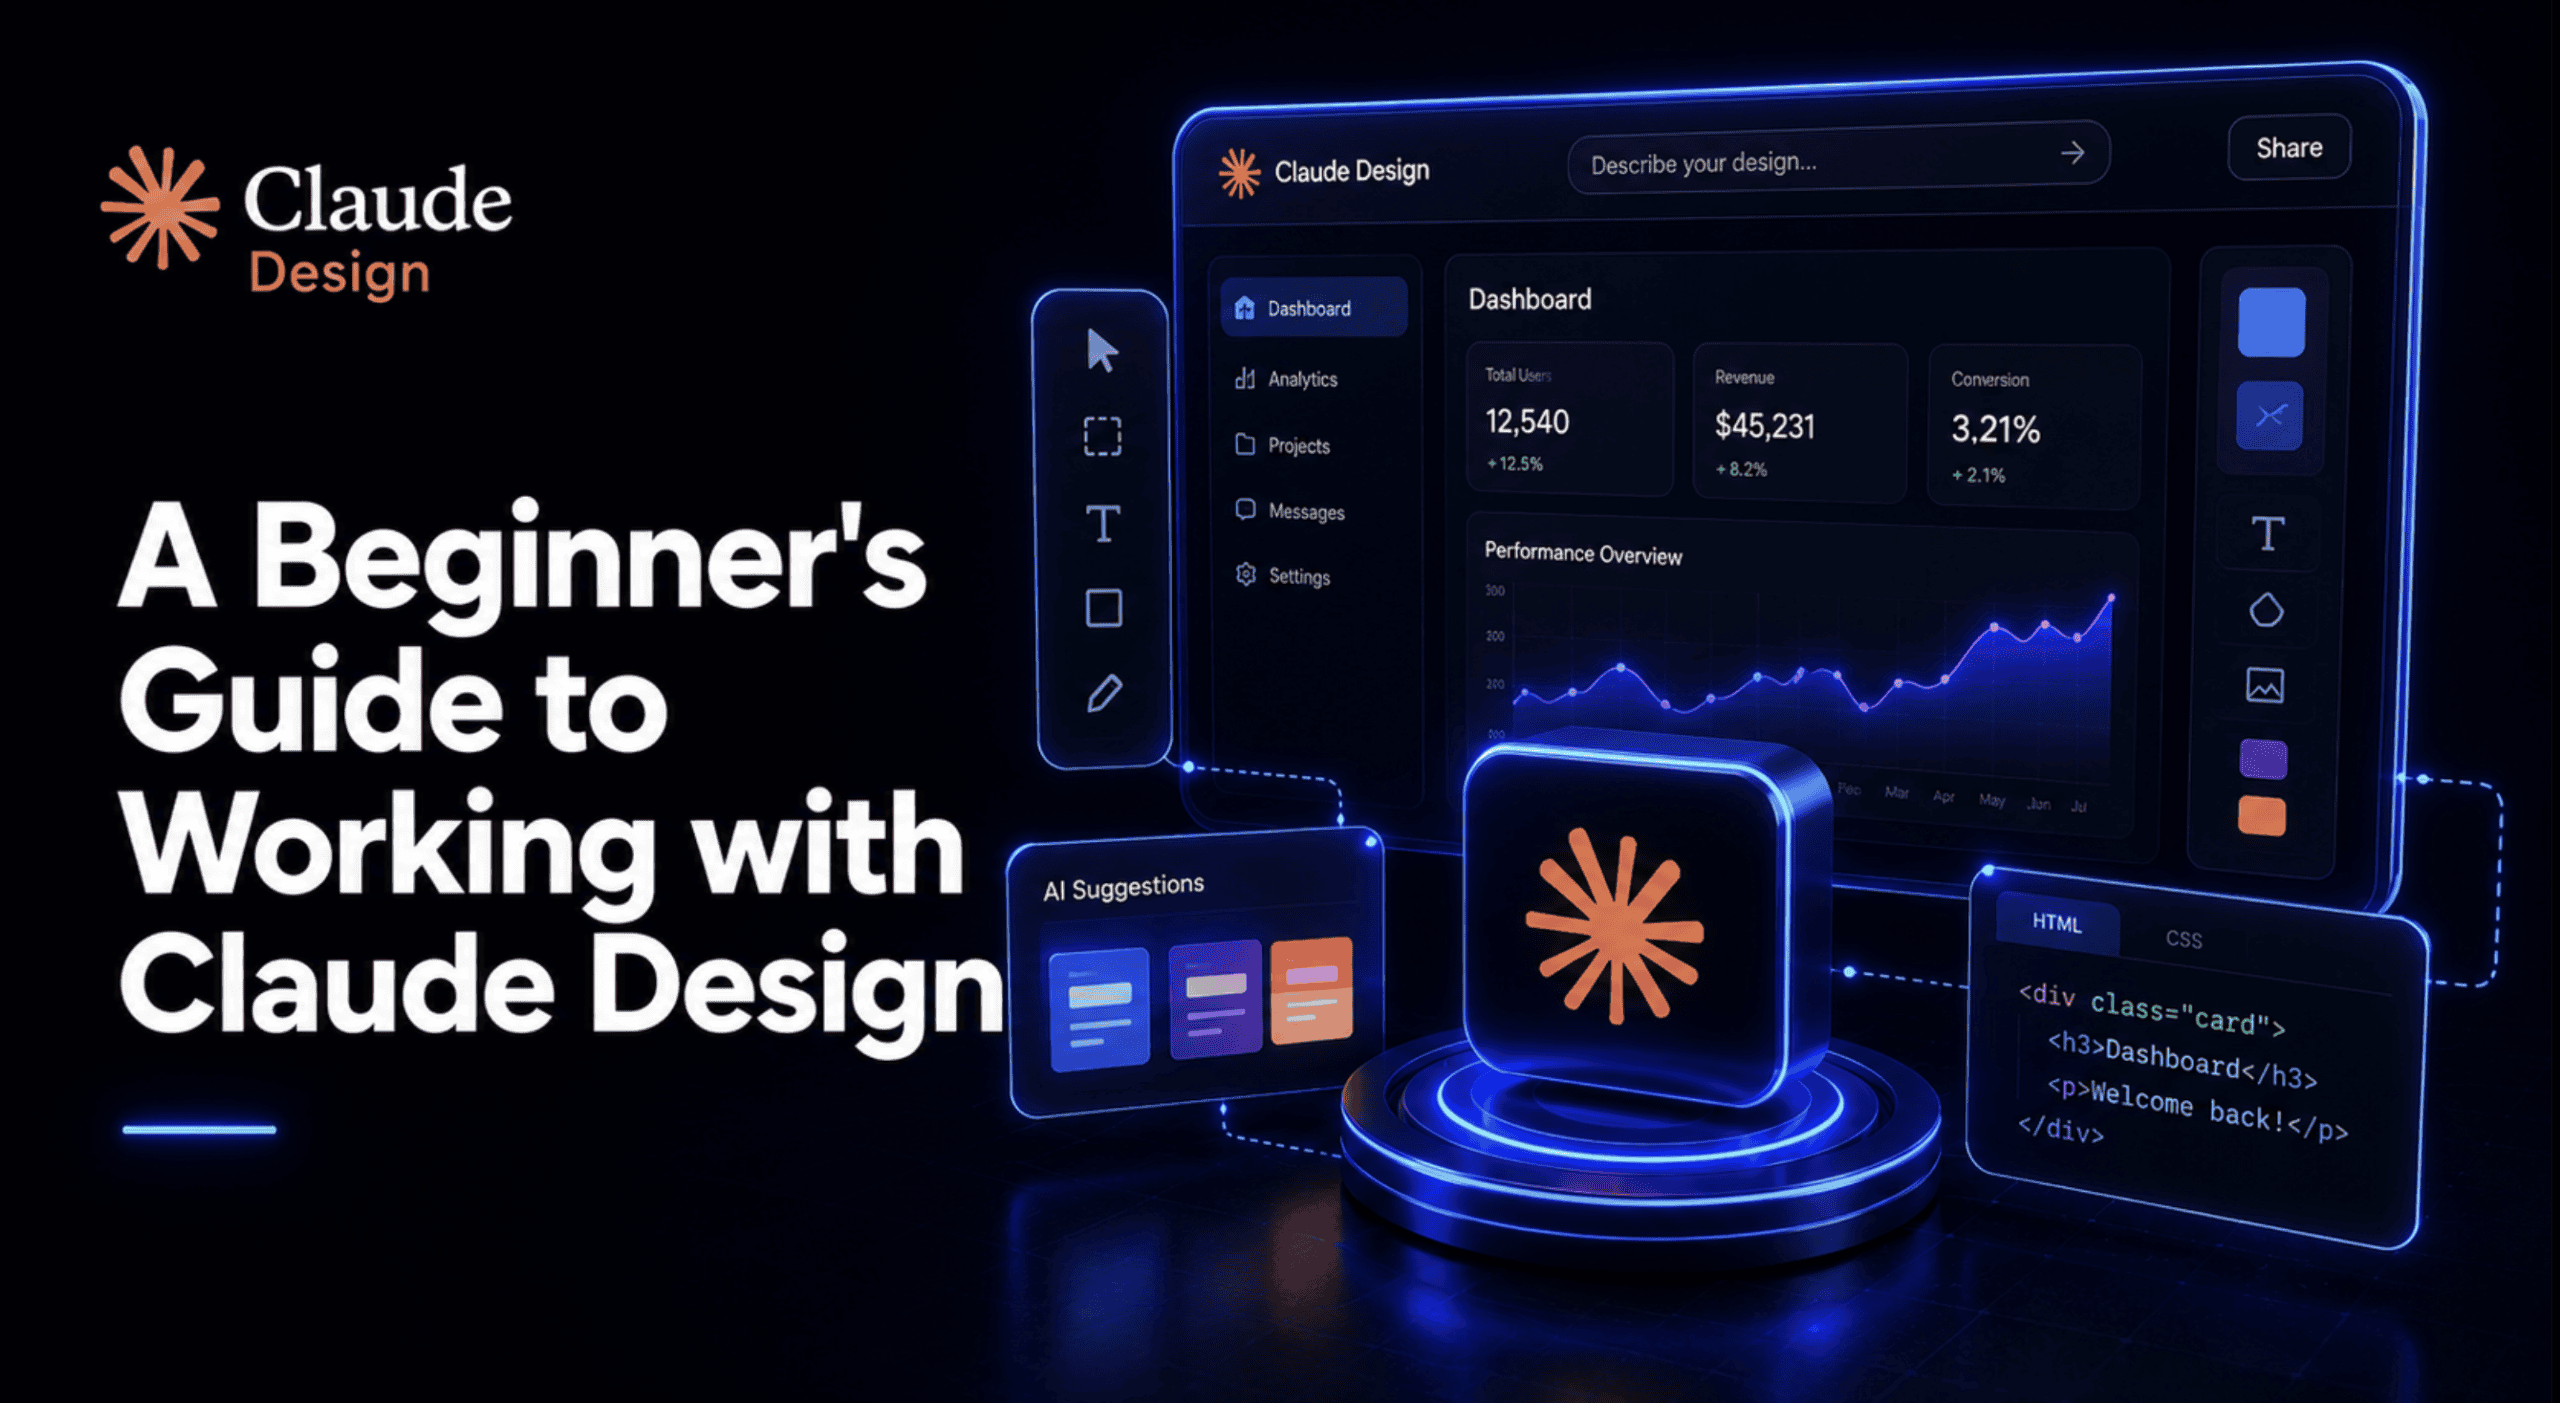
Explore how Claude Design turns ideas into interactive prototypes with AI.
Claude Design isn't just another prototype tool. It's a research preview from Anthropic Labs that uses Claude Opus's vision capability to turn ideas into interactive prototypes with working navigation, embedded video, voice input, and even 3D elements. For beginners, the barrier to entry feels refreshingly low. You're not wrestling with code; you're exploring what's possible when AI handles the heavy lifting. If you're ready to move beyond static mockups, this guide walks you through the essentials.
Six frontier LLMs show measurable left-leaning bias across eight fairness benchmarks
Six frontier models walked into a bias benchmark, and the results defy the usual left-right script. In a solo evaluation spanning roughly 20,600 examples across eight datasets, GPT-5.4, three Claude variants, two Gemini models, and Grok 4.3 were tested on political, gender, and racial bias. The standout finding: Grok self-identifies as right-leaning, yet behaves left-leaning when classifying content or answering policy questions. Refusal rates on race-related questions also varied sharply, with GPT-5.4 declining 20.3% of the time.