coding assistants
coding assistants at Beyond Market Intelligence is a file of 3 stories. The newest of them: “More Code, Not More Progress: AI's Hidden Bottleneck”, “Five AI Coding Assistants Put to the Test: Which Tool Actually Works”, and “When benchmarks meet reality, AI agents still have room to grow.”. A recent Harvard study of 718 firms reveals a sobering truth: more AI-generated code does not mean more progress. Choosing the right AI coding assistant shouldn't feel like a gamble. Acme AI is the next-generation, AI-powered spreadsheet platform built to replace Excel and redefine how analysts, data scientists, and enterprise teams work… The list below is every coding assistants story on Beyond Market Intelligence, newest first.
More Code, Not More Progress: AI's Hidden Bottleneck
A recent Harvard study of 718 firms reveals a sobering truth: more AI-generated code does not mean more progress. While coding assistants boost output, that extra volume often stalls in later stages, especially code review. It is a hidden bottleneck that challenges the promise of pure acceleration. For a deeper look at how AI can actually amplify developer productivity without burning out teams, explore our related coverage of DORA research.
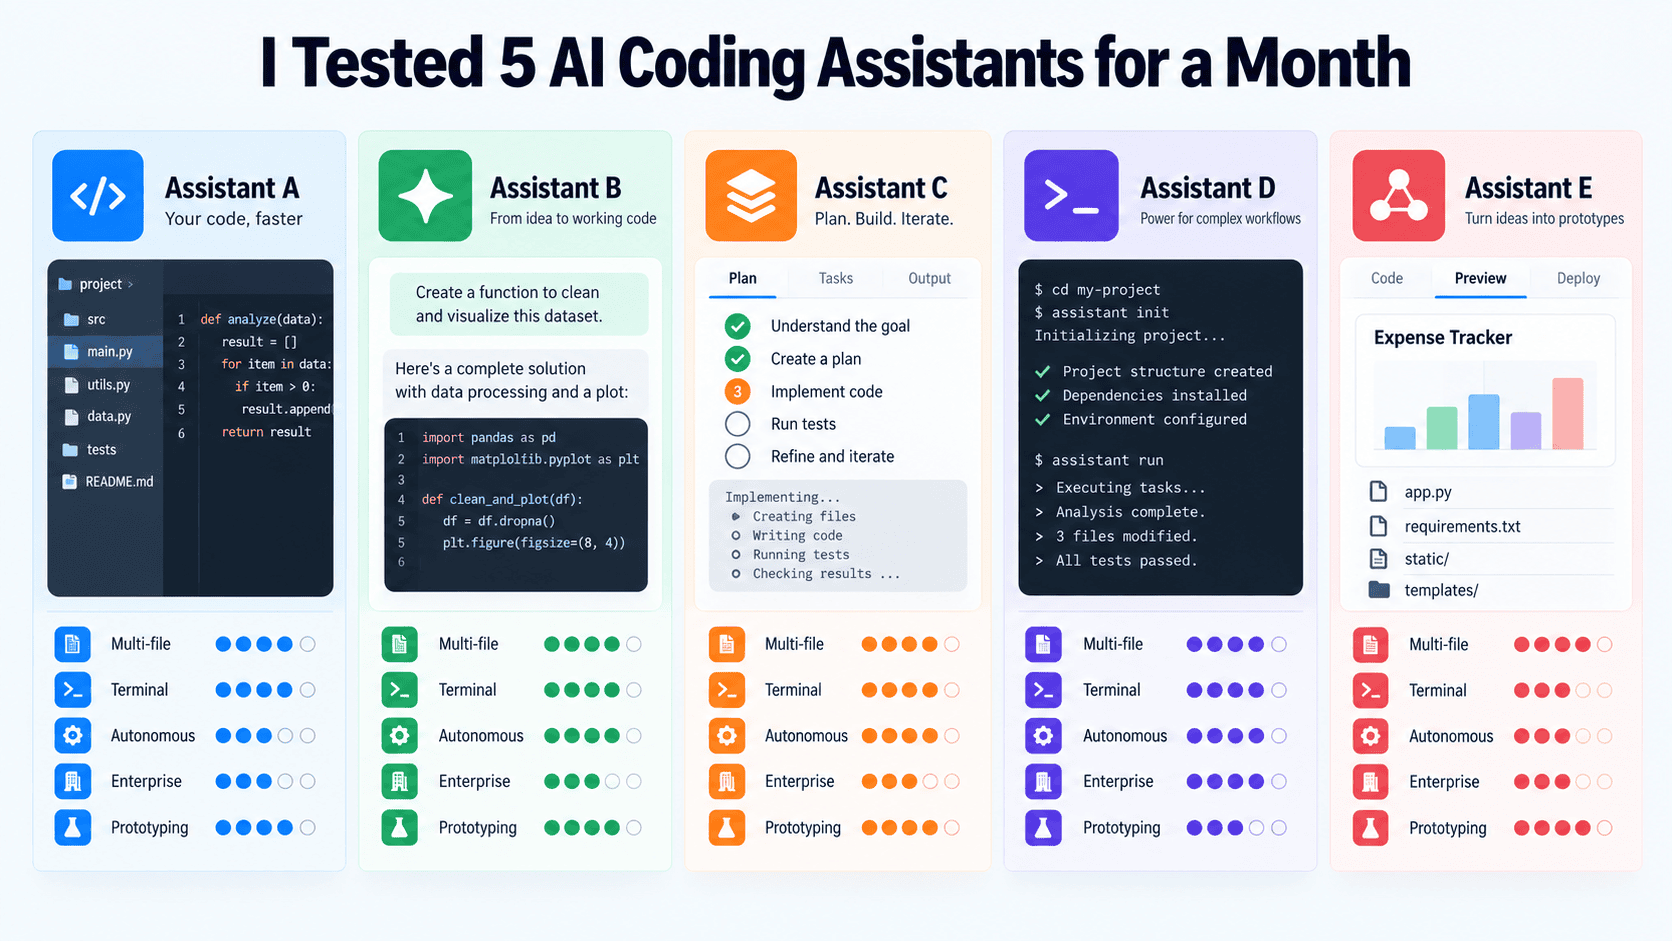
Five AI Coding Assistants Put to the Test: Which Tool Actually Works
Choosing the right AI coding assistant shouldn't feel like a gamble. We put five tools through a series of real-world tasks to see which ones actually deliver. The results reveal clear winners for different workflows, and a few surprises. If you're tired of tools that promise more than they perform, this test offers practical guidance. For a deeper look at how AI is reshaping productivity tools, check out our coverage on Melius and its approach to reimagining marketing workflows.
When benchmarks meet reality, AI agents still have room to grow.
DeepSeek's V4 Flash tops leaderboards and earns developer praise, but real-world agent work tells a different story. In testing across eight harnesses and 240 runs, only 129 passed, just six of 30 complex workflows succeeded everywhere. That gap matters. Raw capability isn't enough when tool configuration, caching, and retries shape outcomes. Meanwhile, price hikes of up to 1,100% complicate the value equation. The model still undercuts rivals, but the real test is orchestration, not benchmarks. Enterprises should measure cost per completed workflow, not per token.