context layer
context layer at Beyond Market Intelligence is a file of 9 stories. The newest of them: “Why Voice AI Still Misses the Context That Matters Most”, “How LinkedIn built context-aware AI agents for massive codebases”, and “See how forward-deployed engineering turns enterprise AI into lasting value.”. Voice AI often misses the context that matters most, and the entire pipeline breaks. Ajay Prakash isn't just tinkering with AI agents; he's giving them a corporate memory. Acme AI is the next-generation, AI-powered spreadsheet platform built to replace Excel and redefine how analysts, data scientists, and enterprise teams work… The list below is every context layer story on Beyond Market Intelligence, newest first.

Why Voice AI Still Misses the Context That Matters Most
Voice AI often misses the context that matters most, and the entire pipeline breaks. That's not a small bug, it's a fundamental gap in how these systems understand intent. When the context layer fails, everything downstream becomes noise. Fixing this requires rethinking how we capture meaning, not just adding more data. For a deeper look at building resilient data pipelines, our piece on mastering message ordering at scale with Kafka and Go offers a practical counterpoint to these context challenges.
How LinkedIn built context-aware AI agents for massive codebases
Ajay Prakash isn't just tinkering with AI agents; he's giving them a corporate memory. At LinkedIn, he tackles a familiar pain point: large codebases that leave agents lost. His answer is Contextual Agent Playbooks and Tools, built on MCP, which feed agents procedural know-how and runbooks directly. The 20% productivity gain with zero reliability loss is a compelling argument for context done right. For more on enterprise AI adoption, check out our related piece on navigating ethical considerations.
See how forward-deployed engineering turns enterprise AI into lasting value.
Forward-deployed engineering is where enterprise AI actually learns. The pitch is familiar: an engineer on-site, a workflow encoded in weeks, a demo that works on real data. The real test comes later. Does the next deployment start with more product and fewer unknowns, or just another services team? We see FDE as a disciplined learning loop. Every engagement should leave behind reusable capability, not just a satisfied customer. That compounding is what separates a product that understands from a company that simply delivers.
Governing Context Layers Doubles the Catch of Bad AI Answers
Enterprises that govern their AI data are catching twice as many bad answers as those that don't, not because they have worse context, but because they can see it failing. Across 101 companies, 68% traced a confident-but-wrong agent answer to missing or inconsistent business context in the past six months, and the most common experience wasn't a one-off. It was recurrence. The governed semantic layer built to fix this is revealing the problem before it solves it. That's not a setback.

From Scattered Knowledge to an AI-Ready Company Brain
Building a context layer sounds straightforward until you try to move beyond a demo. This piece cuts through the hype to show what it actually takes to turn scattered company knowledge into something an LLM can reliably use. The polished demo is only about five percent of the real work. The rest is messy, unglamorous, and essential. If you are weighing whether your team is ready for this, it is a sobering and useful read.
Enterprise AI Trust Falls Faster Than Context Infrastructure Is Built
Enterprise agents are answering with confidence their context can't yet support. New Pulse Research across 101 enterprises shows 57% have traced a confident-but-wrong answer to missing or inconsistent data, yet retrieval is already the default context source for 38% of organizations. The fix, a governed semantic layer, is under construction: 58% are building or running one, but most haven't shipped it. Provider-native tools lead today, even as enterprises insist they want independence. The context gap isn't a retrieval problem.
Your data pipeline is the real reason your AI is confidently wrong
The failure that doesn't look like a failure is the one that quietly undoes your AI system. You ship it, stakeholders sign off, and months later, the answers drift wrong, not because the model changed, but because the data behind it didn't move with the world. That's not a retrieval problem; it's a data engineering one. Correctness, freshness, consistency, lineage, these are the checks that matter, and most pipelines still monitor for completion, not truth. If you're chasing model swaps, you're solving the wrong puzzle.
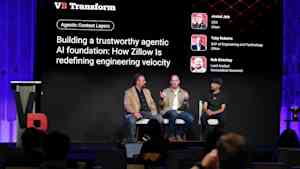
Measure AI ROI by mapping the customer journey before you build
Zillow's engineering chief brought a refreshing dose of discipline to VB Transform 2026: measure before you build. Toby Roberts and Glean's Arvind Jain showed that context, not data, is the real bottleneck in AI. Zillow's persistent context layer carries customers through a journey that spans months and multiple professionals. That's a hard problem, and they're solving it with practical architecture. For those digging into the technical weeds, our guide to distributed algorithms pairs well with this systems-first thinking.
Your AI agents have the data. Now they need your trust.
Confident and wrong. That's the failure mode now stalking enterprise AI, 57% of organizations have traced a confident but incorrect agent answer back to missing or inconsistent context. The infrastructure feeding these agents is being built faster than it can be trusted. Provider-native retrieval already leads the stack, yet most enterprises are still constructing the governed semantic layer that would close the gap. The direction is clear: the context layer is the next contested tier, and agents are running ahead of it.