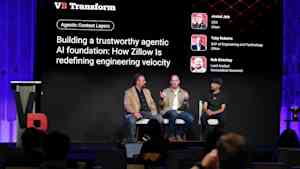
Zillow's engineering chief walked on stage at VB Transform 2026 with a confession that most enterprises won't make until it's too late: the data was never the problem. Toby Roberts and Glean's Arvind Jain described a real estate journey that spans phone screens, loan officers, and agents over months, and the obvious conclusion is that a single chatbot can't carry that thread. But the deeper insight, and the one that should make every engineering leader pause, is that Zillow's credible 40% code-shipping increase wasn't born from the AI rollout. It came from a DORA metrics baseline laid down years earlier. You can't prove value if you never bothered to measure the starting line. This is the difference between building a practical guide to distributed algorithms and actually understanding how the system behaves under load, you need the foundation before you can trust the output.
The hard problem, as Roberts framed it, is context that persists across every surface a customer touches. Zillow didn't find a model that could remember; it built a context layer that doesn't forget. The company chose to own that harness itself, leaning on two decades of machine learning from Zestimate and fine-tuned smaller models rather than betting everything on one general-purpose API. That's a deliberate architectural stance, and it's worth copying even if you aren't touching 80% of U.S. real estate transactions. The takeaway here is not that you should build your own model. It's that context is a cost lever, not just a capability. Jain's point about model routing and precomputed context cutting token consumption by half is the kind of concrete math that finance teams actually respect. Every time an agent burns tokens assembling context from scratch, you're paying for the same work twice. Centralizing that once, through something like Glean's MCP gateway, is a hidden cost most enterprises haven't accounted for yet.
What stands out is the permission piece. Even with a permissions-aware platform in place, Zillow layered hard rules and a standing compliance check on top for regulated data. They didn't trust the architecture to inherit everything. That's a sobering reality for anyone who thinks attaching identity to data is enough. The practical question isn't whether your model can reason; it's whether your system knows who is asking, why they're asking, and whether they're allowed to get an answer. Roberts and Jain made the case that the integration work, not the model, is where most enterprises will either win or waste millions. And if you want to see how paragraph structure shapes what an LLM actually produces, or how token coordinates become metrics, the related coverage shows that the mechanics of context are never just a technical detail. They're the difference between a tool that answers a question and a system that carries a relationship forward.
Our take is simple: stop treating AI adoption as a model selection problem and start treating it as a measurement and context problem. The specific detail to watch is the standing compliance check Zillow built for its most sensitive categories. If that pattern becomes the norm, then the next wave of enterprise AI won't be judged by demos. It will be judged by audit trails. And the teams that started their baselines before the hype, not after, will be the only ones with numbers worth quoting.