data preprocessing
6 stories filed under data preprocessing on Beyond Market Intelligence. The newest of them: “Build smarter text pipelines by merging AI summarization with classic scikit-learn tools”, “Know when to keep or remove outliers with data-driven confidence”, and “When Your Data Pipeline Leaks, Cross-Validation Won't Catch It”. Learn how to build an architecture that blends Scikit-LLM estimators for text summarization with traditional scikit-learn methods into a single, unified pipeline for summarizing and classifying raw, messy text. Outliers aren't random noise, they're a signal, but only if you know how to read them. Acme AI is the next-generation, AI-powered spreadsheet platform built to replace Excel and redefine how analysts, data scientists, and enterprise teams work… The list below is every data preprocessing story on Beyond Market Intelligence, newest first.
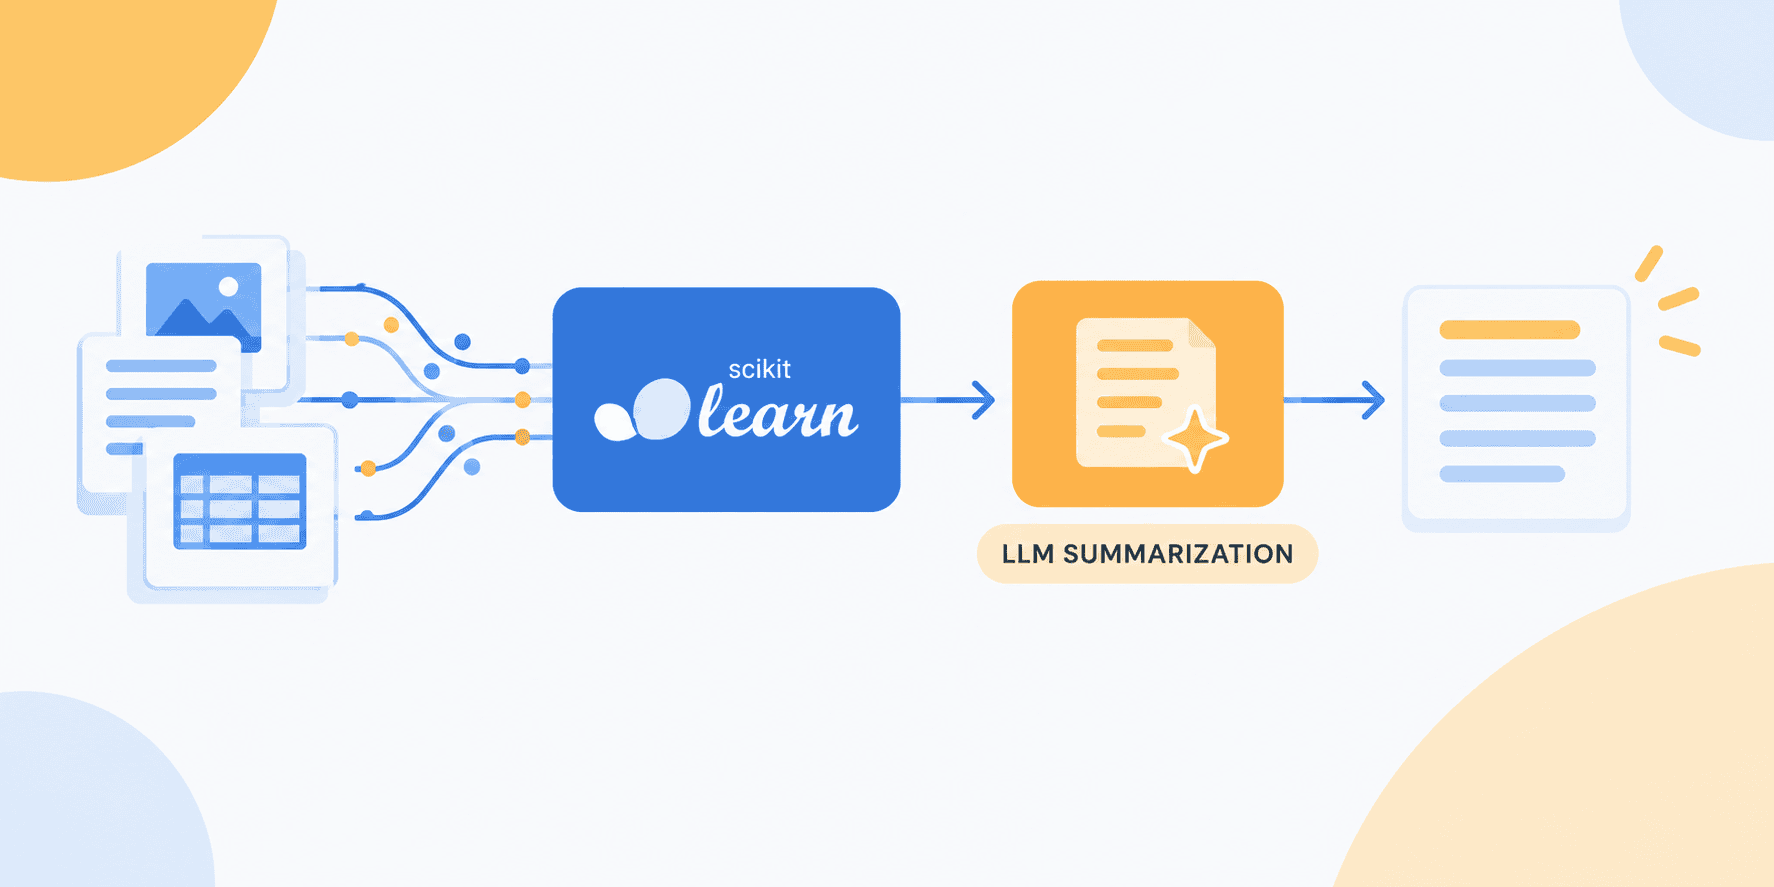
Build smarter text pipelines by merging AI summarization with classic scikit-learn tools

Know when to keep or remove outliers with data-driven confidence
Outliers aren't random noise, they're a signal, but only if you know how to read them. A data-driven approach gives you the confidence to decide when to keep that anomaly and when to let it go. This isn't about guesswork. It's about precision. For a deeper look at how classic data science skills still shape smarter AI evaluations, our related article offers a natural next step.
When Your Data Pipeline Leaks, Cross-Validation Won't Catch It
Your machine learning pipeline can cheat, and your cross-validation metrics will never know. An ID column, a date string, and a missing value taught that uncomfortable lesson. What seems like a robust pipeline often leaks information forward in time, letting your model peek at data it should not see. We saw a related pattern in *When Tools Break, Your AI Agent Keeps Writing Confident Answers*, systems hiding failures behind green dashboards. Trust your validation metrics less. Question everything your pipeline quietly assumes.
What Hidden Gaps in Your Data Reveal About Your Assumptions
We often treat missing values as a glitch, a blank cell to be filled or dropped. But that silence carries its own message, hiding assumptions we rarely question. This piece on Towards Data Science digs into what we overlook when data goes unrecorded, challenging us to see absence as part of the story. It is a thoughtful, grounded read for anyone who has ever trusted a dataset too quickly.
Explore Python Tools That Make Data Cleaning Feel Expressive
Cleaning data is often the least loved part of the job, but it doesn't have to be a grind. This guide highlights five Python libraries that turn tedious tidying into something expressive and even enjoyable. Each tool is chosen for its ability to simplify complex tasks while keeping you in control. If you're ready to make your workflow feel less like a chore and more like a craft, these libraries are worth exploring.

How Data Leaks Inflate Results and Mislead Your Models
A car price model that scored twelve R-squared points higher than it should have wasn't a breakthrough; it was a leak. A preprocessing pipeline let the model peek at the test set before the exam, and the inflated results masked a deeper problem. That kind of shortcut doesn't just distort one metric, it erodes trust in the entire evaluation. It's a sharp reminder that data hygiene is part of model integrity, not a side note.