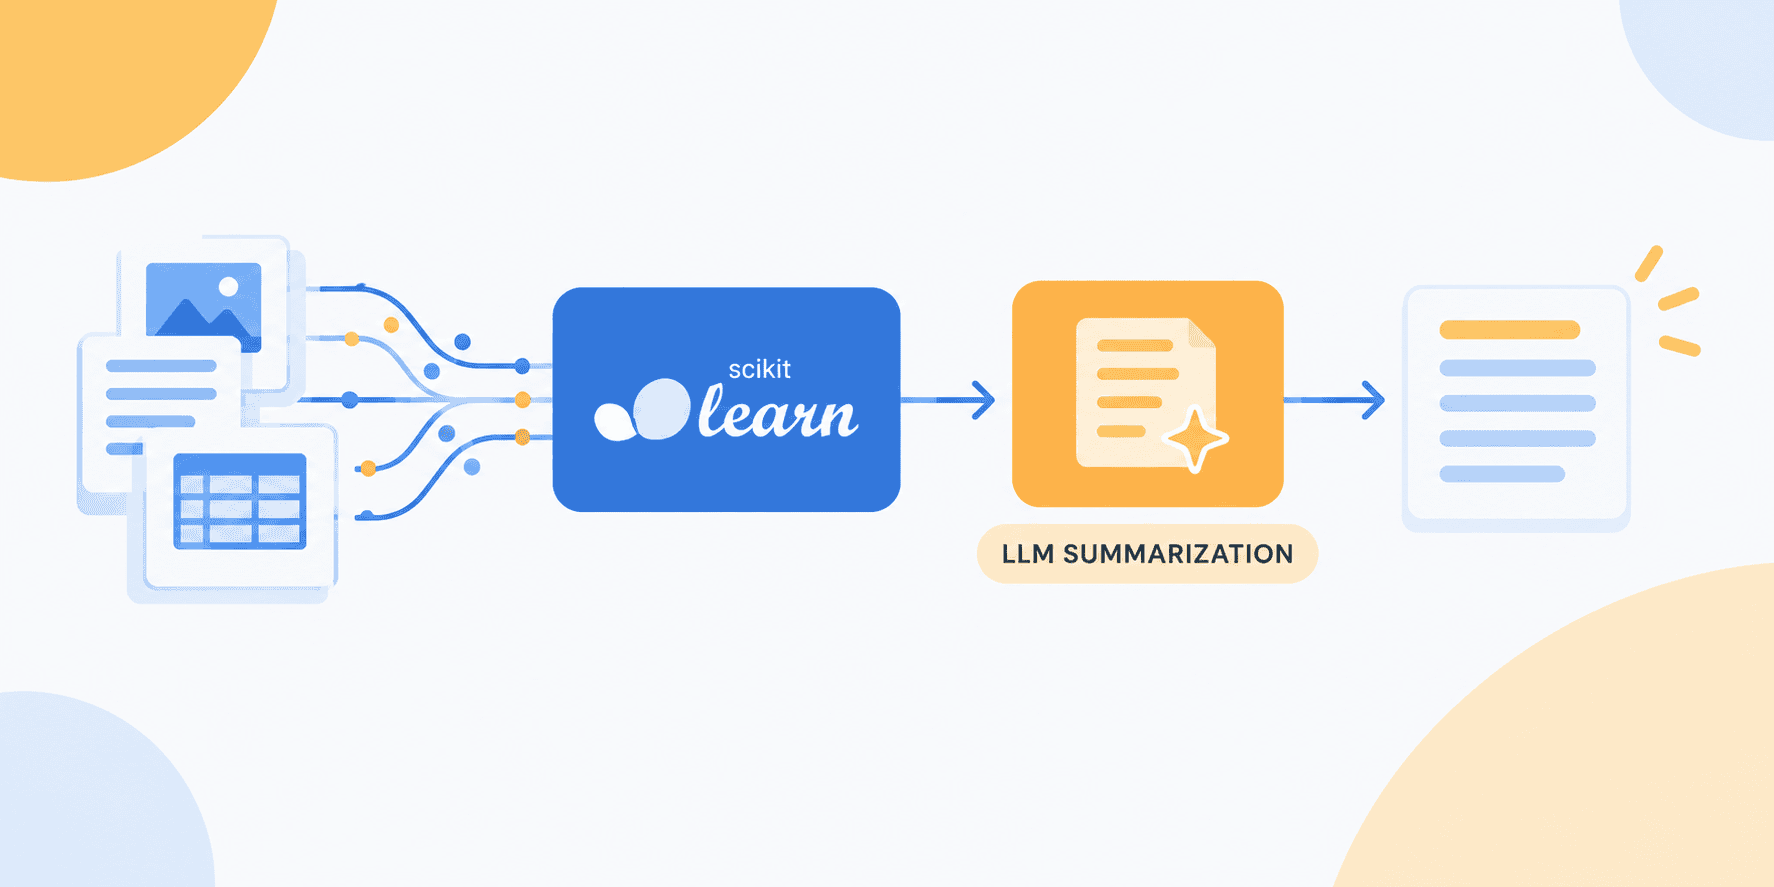
The architecture described here, Scikit-LLM estimators for summarization joined with traditional scikit-learn methods in one unified pipeline, treats raw, messy text as something you can summarize and classify without rebuilding your stack from scratch. That matters because it lowers the barrier to entry. You do not need to abandon the tools you already trust to benefit from what modern language models can do.
The timing is right for this kind of thinking. Anyone who has tried to keep pace with the field knows the naming problem alone can stall a project, as we explored in Why neural network optimizer names make searching so difficult. The same friction shows up in data preparation, where small decisions about augmentation carry real consequences, a theme we touched on in Navigating Aggressive Crops and Moderate Zooms in Augmented Datasets. A unified pipeline cuts through that noise by giving teams one place to summarize, classify, and evaluate instead of stitching together separate experiments that never quite line up.
The deeper value is architectural. Scikit-learn earned its place because its pipelines are composable, testable, and predictable. Wrapping LLM-based summarization inside that structure means you keep the discipline of fit, transform, and evaluate while gaining the flexibility of AI-generated summaries. Messy text stops being a blocker and becomes an input you can handle. For readers building their first text systems, this is a concrete way to ship something useful without a research team. Start with a small labeled set, run it through a pipeline that summarizes before it classifies, and compare results against a baseline that skips summarization. That single experiment will tell you more than months of reading.
There is a genuine vision question underneath the engineering. As we noted in Understanding AI's Drive: What Sutskever Meant by "The Models Want to Learn", the models are increasingly capable of absorbing complexity on their own. The temptation is to hand everything to the model and walk away. The smarter move is to keep classic tooling in the loop where it adds reliability, and let summarization do the work it is actually good at. Watch how the pipeline handles a batch of genuinely messy text before you commit to it in production. That first run will expose whether summarization is helping your classifier or quietly erasing the signal it needs.