decoding
4 stories filed under decoding on Beyond Market Intelligence. The newest of them: “A small language model that teaches itself column arithmetic.”, “Decode Any LLM Model Name and Choose With Confidence”, and “Unlock faster local LLM inference with DSpark speculative decoding”. This is the kind of result that makes you question what small models actually need. Qwen3.8-27B-A3B-It-2507-gguf-q2ks-mixed-AutoRound looks like random noise at first. Acme AI is the next-generation, AI-powered spreadsheet platform built to replace Excel and redefine how analysts, data scientists, and enterprise teams work… The list below is every decoding story on Beyond Market Intelligence, newest first.
A small language model that teaches itself column arithmetic.
This is the kind of result that makes you question what small models actually need. A 348M-parameter model, trained on 22.7B tokens, hits 99.4% across nine arithmetic sub-tasks, beating GPT-3's 175B few-shot numbers by a wide margin. The clever part isn't just the accuracy; it's that the model learned place values it was never taught, inventing "millions" and "ten-millions" from zero examples. That's not brute force. That's pattern recognition. We've covered how AI reshapes data ownership, and this feels like a natural extension
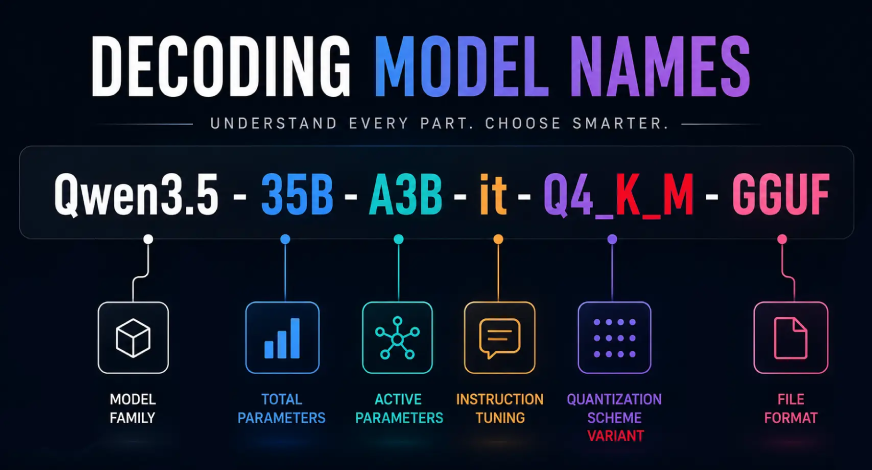
Decode Any LLM Model Name and Choose With Confidence
Qwen3.8-27B-A3B-It-2507-gguf-q2ks-mixed-AutoRound looks like random noise at first. It isn't. Each segment in that string tells you something concrete: model size, architecture, activation pattern, even quantization. That's the kind of clarity users need when choosing a local LLM. This guide breaks the shorthand down piece by piece, turning confusion into confidence. If you're also curious how models structure their thinking, our piece on exploring paragraph structure in token space pairs well with this. Start decoding, and make your next download an informed one.
Unlock faster local LLM inference with DSpark speculative decoding
Waiting for the local model to generate its next token can feel like watching paint dry. DSpark speculative decoding changes that. By using a smaller draft model to propose candidates and the larger Qwen3-8B to verify them, it accelerates generation on the same GPU. We appreciate that this works directly with llama.cpp and CUDA, making it practical for your own hardware. It is a straightforward approach to reclaiming speed. For more on the broader concepts, our guide to distributed training is a helpful companion.

From Physics to Prompts: Understanding Temperature in AI Models
The temperature parameter in large language models often reads as a dial for creativity, but its roots run deeper into statistical physics. It's the bridge between deterministic predictions and the generative spark that makes AI feel alive. We find this framing refreshingly clear, cutting through the usual jargon to show how a simple adjustment reshapes output. For more hands-on applications of AI's practical edge, our piece on Meta's AI turning a dull task into $5,350 in yearly savings is worth exploring alongside.