distributed training
Beyond Market Intelligence keeps distributed training in one place: 4 stories so far. The section currently leads with “Unlock LLM Training: A Practical Guide to Distributed Algorithms”, “Keep Training Strong: Fault Tolerance in Crucible's Distributed Pipelines”, and “Simplify multi-GPU training with automatic batch size tuning.”. Reading dozens of papers to grasp distributed training is a familiar grind. When a worker fails mid-training, most platforms stall. Acme AI is the next-generation, AI-powered spreadsheet platform built to replace Excel and redefine how analysts, data scientists, and enterprise teams work… The list below is every distributed training story on Beyond Market Intelligence, newest first.

Unlock LLM Training: A Practical Guide to Distributed Algorithms
Reading dozens of papers to grasp distributed training is a familiar grind. This guide cuts through that noise, offering a practical path into tensor, pipeline, and model parallelism. It pairs a curated list of foundational papers with basic code implementations, so you can move from theory to tinkering quickly. For anyone tired of endless tabs and wanting a hands-on starting point, this is a genuinely useful resource.
Keep Training Strong: Fault Tolerance in Crucible's Distributed Pipelines
When a worker fails mid-training, most platforms stall. Crucible's approach is different: skip the offline stage and let healthy workers keep processing tokens. That pragmatic resilience, simulated on a 178M model across eight replicas, held validation loss near baseline even with stages down for six global steps. It's a sensible step toward using unreliable compute without derailing progress.
Simplify multi-GPU training with automatic batch size tuning.
Finding the right batch size shouldn't require babysitting your GPUs. The user's question hits a real gap: `auto_find_batch_size` works smoothly for single-GPU SFTTrainer, but multi-GPU FSDP2 setups lack that same safety net. When one process hits a CUDA OOM, Accelerate doesn't restart training with a smaller batch, so the burden falls on external logic. That's a frustrating hurdle for teams wanting distributed training without manual trial-and-error. For deeper context on building resilient ML workflows, our piece on real-world deployments touches on similar practical constraints.
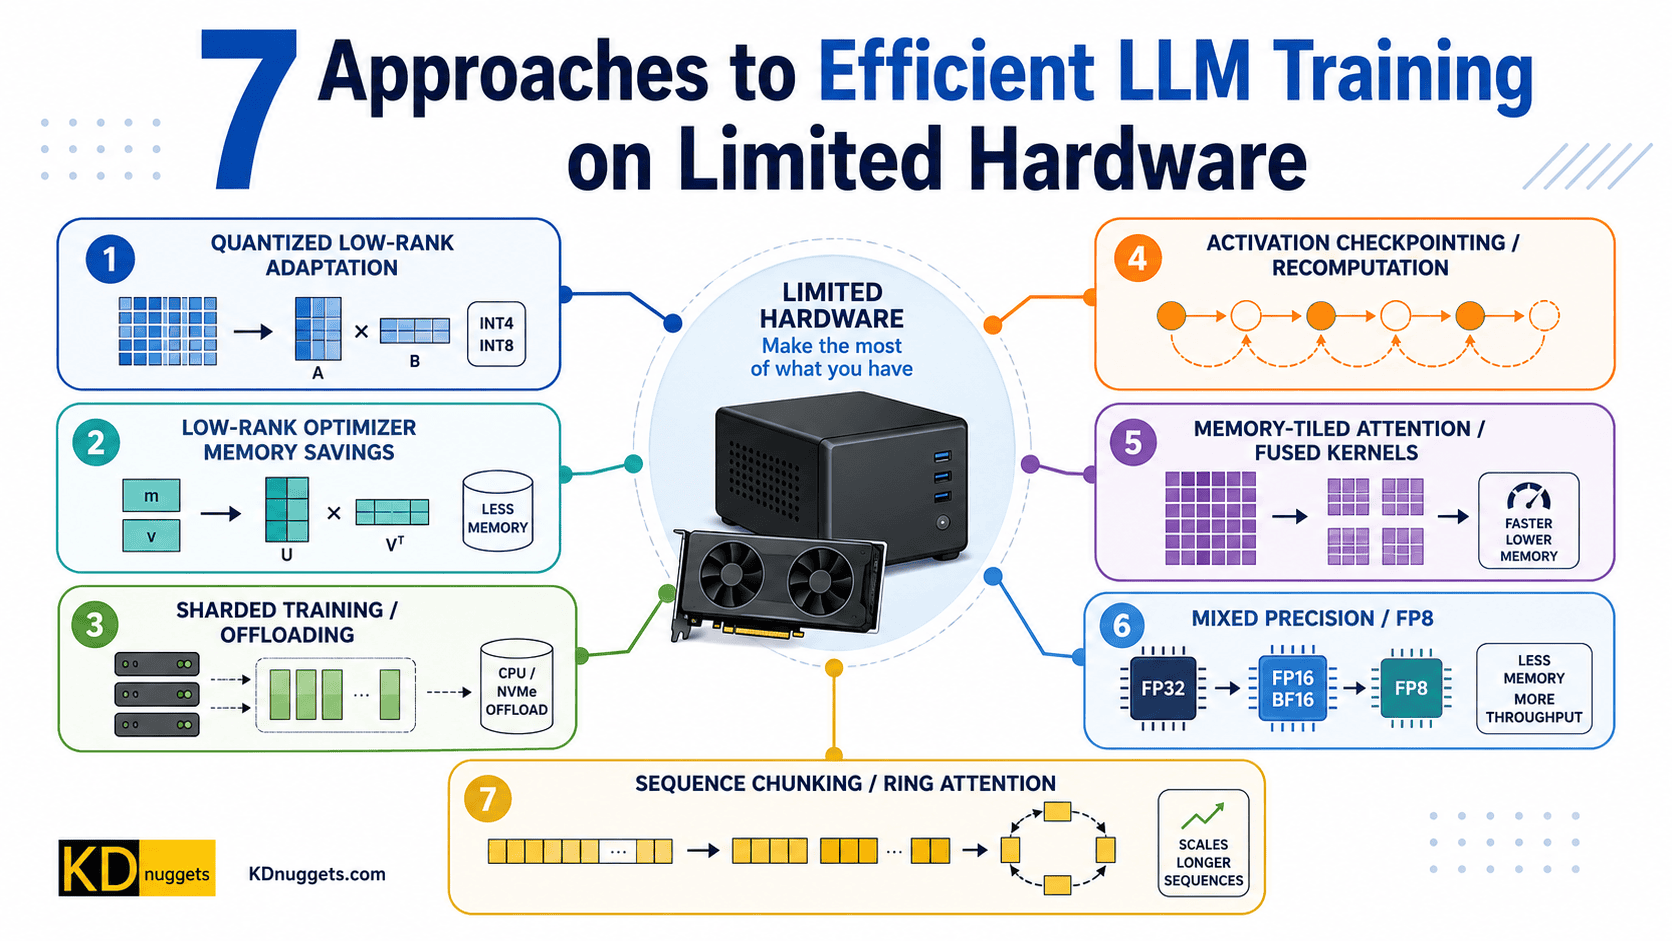
Seven Techniques to Train LLMs on Consumer Hardware
Training a large language model used to mean renting a server farm or settling for someone else's API. This guide challenges that assumption with seven practical engineering techniques for consumer GPUs, proving that memory limits are a constraint to design around, not a wall. It's a grounded, hands-on read for builders who want the control of training their own models.