DuckDB
13 stories filed under DuckDB on Beyond Market Intelligence. The newest of them: “Discover DuckLake: Build a Lakehouse on DuckDB in Under an Hour”, “Cloudflare opens Basin serverless analytics to all with zero egress fees”, and “Validate LLM Output in DuckDB and dbt With Python and Gemini Guardrails”. Building a lakehouse on DuckDB in under an hour sounds ambitious, but DuckLake makes it plausible. Cloudflare has opened Basin, its serverless analytics platform, to everyone with a compelling offer: zero egress fees. Acme AI is the next-generation, AI-powered spreadsheet platform built to replace Excel and redefine how analysts, data scientists, and enterprise teams work… The list below is every DuckDB story on Beyond Market Intelligence, newest first.
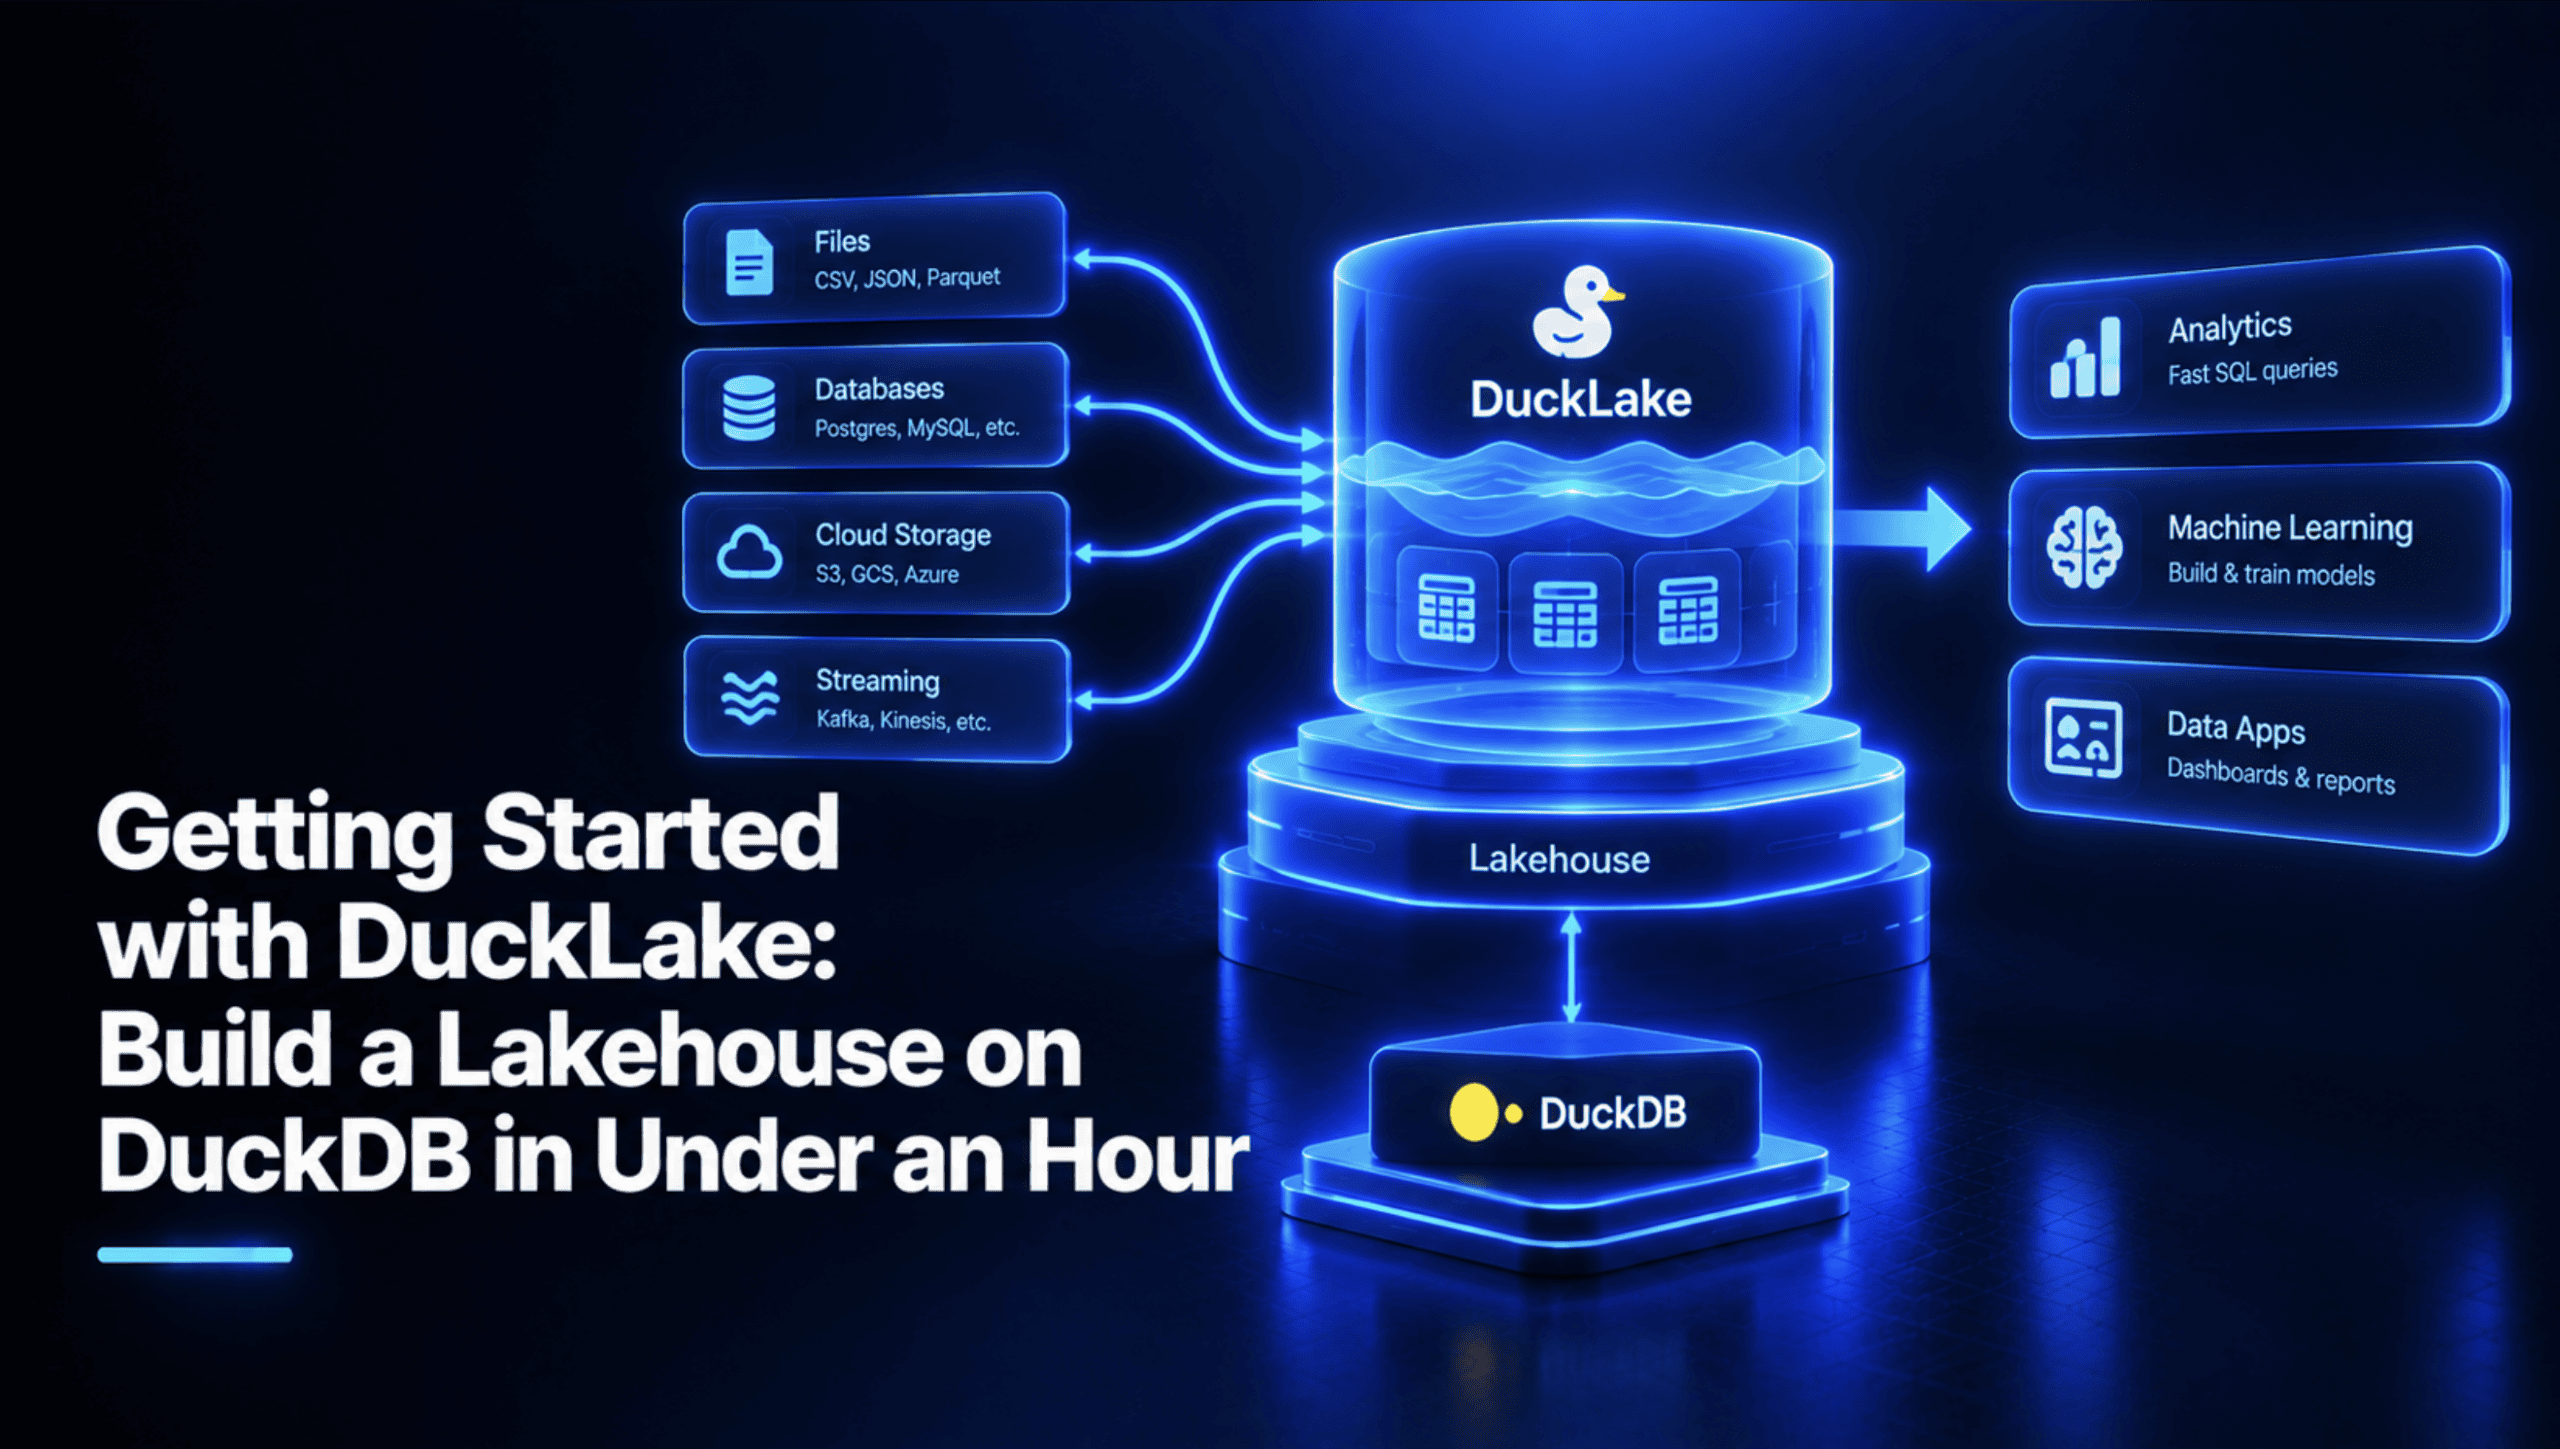
Discover DuckLake: Build a Lakehouse on DuckDB in Under an Hour
Building a lakehouse on DuckDB in under an hour sounds ambitious, but DuckLake makes it plausible. This open table format from the DuckDB team stores metadata in a SQL database while keeping actual data in Parquet files. The 1.0 release in April 2026 brings a stable specification with guaranteed backward compatibility, a rare commitment that inspires confidence. For teams feeling constrained by legacy data architectures, DuckLake offers a pragmatic path forward.
Cloudflare opens Basin serverless analytics to all with zero egress fees
Cloudflare has opened Basin, its serverless analytics platform, to everyone with a compelling offer: zero egress fees. Built on Apache Iceberg and R2 Object Storage, it supports open formats and works with tools like DuckDB, Snowflake, and Apache Spark. This removes a major cost barrier for data teams wanting to explore without vendor lock-in. For more on working with open-source data tools, see our piece on validating LLM output in DuckDB and dbt with Python and Gemini Guardrails.
Validate LLM Output in DuckDB and dbt With Python and Gemini Guardrails
Eighteen RemoteOK postings had their skills, seniority, and Nigeria eligibility pulled by a Gemini Flash-Lite step, but the real guardrails came from Python checks and dbt tests validating every answer. This is a practical pipeline for trusting LLM output inside DuckDB and dbt. If you want to see how a simple session start lifted Claude Code skill accuracy from 15% to 62%, that related article offers a revealing comparison. Here, the focus stays on building checks that catch what the model might miss.
Four Signals to Know When Your Data Engine Has Outgrown Spreadsheets
When a data engine starts producing facts you can't fully trace back to their source, you've hit a signal worth heeding. Peihao Yuan walks through a disaster-recovery analytics workflow where an AI agent generates constrained SQL or Python, DuckDB computes reproducible facts from Parquet, and the agent interprets the results. The determinism split makes every analysis replayable. Four signals help you decide whether an embedded engine still suffices or a managed lakehouse is justified.
Aurora PostgreSQL Gains DuckDB's Analytical Power in New AWS Acquisition
Amazon's acquisition of DuckLabs signals a serious bet on analytical horsepower for its database ecosystem. By bringing DuckDB's co-founders Hannes Mühleisen and Mark Raasveldt under AWS, the company is investing in open-source innovation without compromising DuckDB's independent spirit. Aurora PostgreSQL now gains its first DuckDB-powered feature, blending transactional reliability with analytical speed. For anyone exploring how AI agents unlock hidden insights in compiled binaries, this move reinforces the value of purpose-built tools for modern data challenges.

Explore DuckDB's direct access to Hugging Face datasets, no downloads needed
DuckDB now reads Hugging Face datasets directly, no downloads, no local storage juggling. That's a meaningful step toward removing friction from data workflows. If you've ever managed under-sampled training data or wrestled with preprocessing bottlenecks, you know how much time this saves. Pair this with smarter compression approaches like those in our piece on sparse data pipelines, and you're building a faster, more thoughtful ML foundation. Explore it, and see how direct access changes your process.
Unlock Data Insights: Building a Lakehouse with DuckDB and DuckLake
A single Parquet file on your laptop might not feel like a data lakehouse yet. But when you join that local data to cloud storage in the same query, the picture sharpens. DuckDB and DuckLake make this transition straightforward, not theoretical. It is a practical path from isolated files to a unified analytics layer. If you are tired of wrestling with complex infrastructure, this walkthrough feels like a breath of fresh air.
Bring AI Workloads Home with Browser-Native Performance and Privacy
The cloud isn't the only place for serious AI workloads. In this presentation, James Hall makes a compelling case for moving real work directly into the browser. He walks through practical strategies using WebGPU, Transformers.js, and DuckDB to achieve near-native performance without leaving JavaScript behind. What stands out is his focus on minimizing data privacy risks and building solid evaluation suites. For anyone feeling stuck in centralized workflows, this is a practical look at reclaiming control.

DuckDB v2.0 Opens a Network Gateway for Distributed Data
DuckDB v2.0, codenamed "Cyanoptera," is making a bold architectural move. After over 10,000 commits, the preview introduces a client/server mode that opens the door to real network connections. That's not just a feature; it's a fundamental shift in how we think about embedded analytics. We also see progress in extension portability and asynchronous I/O, which should make data work feel more fluid. This is a forward-looking step.
Run Your Data Analysis Where Your Data Lives
Most dataframe work pulls data out of the database, then pushes it back after Python finishes its part. memFrame flips that script. It compiles your Python/DataFrame API calls directly into SQL, letting DuckDB, PostgreSQL, or ClickHouse do the heavy lifting where the data lives. That is a smarter default. The incremental release strategy is also a good discipline: get inspection, cleaning, and arithmetic solid before tackling groupby and window functions. For deeper Python performance thinking, our guide on advanced techniques pairs well here.

Explore remote SQL execution with three concurrent DuckDB servers.
DuckDB is known for being fast, but what happens when you push it beyond a single machine? In this experiment, the team behind Quack ran SQL concurrently across three remote servers to see if the database could handle the pressure. The result is a practical look at distributed execution that feels both ambitious and grounded. It is not about hype; it is about what actually works. If you are exploring how AI-native tools handle real-world data challenges, this is a worthwhile stop.

From geospatial data to graph networks, City2Graph simplifies urban analysis.
Geospatial data is messy, and City2Graph's new paper makes a clean argument for why heterogeneous graphs beat flat tables. The library turns buildings and street segments into analysis-ready nodes and edges, then pushes them straight into PyTorch Geometric. That is a practical bridge between urban morphology and graph neural networks. It is not about hype; it is about making the workflow simpler. For anyone tired of wrestling with geometry and attributes across conversions, this feels like a step toward a more accessible, future-focused toolkit.

Explore how medallion architecture simplifies your data pipeline with Python and DuckDB
Most teams hit the same wall: raw data lands in one place, and chaos follows. The Medallion Architecture cuts through that with a clear Bronze, Silver, and Gold path, turning mess into structure. This guide pairs that framework with a working Python and DuckDB example, so you can see it run, not just read about it. For more on how LLMs navigate token space, check out our piece on paragraph structure.