gguf
Beyond Market Intelligence keeps gguf in one place: 4 stories so far. The section currently leads with “Accelerate Local LLM Learning: A New Prototype for Faster Fact Correction”, “Decode Any LLM Model Name and Choose With Confidence”, and “Finding the sweet spot between model scale and quantization precision”. Watching a toddler learn taught Kavanutz something about AI. Qwen3.8-27B-A3B-It-2507-gguf-q2ks-mixed-AutoRound looks like random noise at first. Acme AI is the next-generation, AI-powered spreadsheet platform built to replace Excel and redefine how analysts, data scientists, and enterprise teams work… The list below is every gguf story on Beyond Market Intelligence, newest first.
Accelerate Local LLM Learning: A New Prototype for Faster Fact Correction
Watching a toddler learn taught Kavanutz something about AI. Jayce, his new prototype, skips the heavy lifting of RAG pipelines and fine-tuning entirely. Instead, it shifts raw context vectors across a fixed pool of 4,048 prototype slots, correcting mistakes in real time. The benchmarks are telling: faster updates, better sample efficiency on sequential tests, and a strict memory ceiling. It's a lean, framework-free proof of concept built on NumPy and Java.
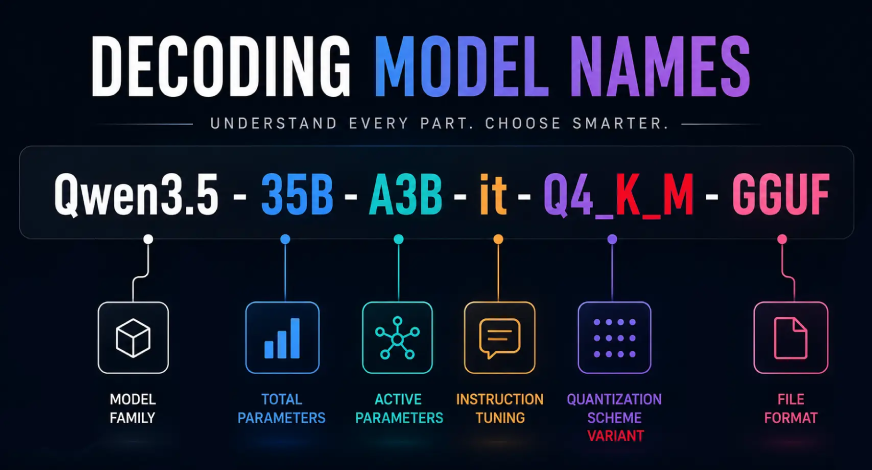
Decode Any LLM Model Name and Choose With Confidence
Qwen3.8-27B-A3B-It-2507-gguf-q2ks-mixed-AutoRound looks like random noise at first. It isn't. Each segment in that string tells you something concrete: model size, architecture, activation pattern, even quantization. That's the kind of clarity users need when choosing a local LLM. This guide breaks the shorthand down piece by piece, turning confusion into confidence. If you're also curious how models structure their thinking, our piece on exploring paragraph structure in token space pairs well with this. Start decoding, and make your next download an informed one.
Finding the sweet spot between model scale and quantization precision
The sweet spot for quantizing LLMs keeps shifting, and the old 4-bit consensus is fading fast. New research points to a more aggressive target, where a 2-bit 70B model can genuinely outpace a 4-bit 35B one, given a fixed memory budget. This is about maximizing capability, not preserving a single model's fidelity. The degradation from quantization is real, but it's often outweighed by the sheer benefit of more parameters. It's a trade-off worth exploring, especially for those running models locally.
When AI Models Become the Target, Ransomware Takes a Darker Turn
When the same attacker breaks into the same server twice, the second visit should never bring a weapon built specifically for what you keep there. That's exactly what happened here. In July, Sysdig documented a crew it tracks as JADEPUFFER exploiting a Langflow flaw twice, but the second payload was ENCFORGE, a compiled ransomware locker with no interest in money. It carries no payment portal. It exists to destroy the AI models you cannot restore. That distinction matters.