GPU utilization
5 stories filed under GPU utilization on Beyond Market Intelligence. The newest of them: “VentureBeat expands enterprise AI analysis with new lead analyst hire”, “Enterprises race to buy AI compute without tracking what it costs”, and “Stop feeding your GPUs the same data twice”. VentureBeat is doubling down on enterprise AI research with the appointment of Rob Strechay as its first Lead Analyst. The compute gap isn't about buying more, it's about seeing what you already own. Acme AI is the next-generation, AI-powered spreadsheet platform built to replace Excel and redefine how analysts, data scientists, and enterprise teams work… The list below is every GPU utilization story on Beyond Market Intelligence, newest first.
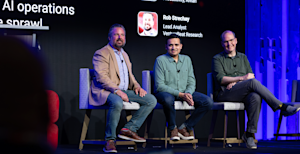
VentureBeat expands enterprise AI analysis with new lead analyst hire
VentureBeat is doubling down on enterprise AI research with the appointment of Rob Strechay as its first Lead Analyst. Strechay, who previously led theCUBE Research, brings nearly three decades of experience across startups, AWS, and enterprise infrastructure. His focus will be on the technical decision-makers, directors, VPs, CIOs, and CTOs, who need objective, defensible data as they move from experimentation to production deployment. This is a deliberate expansion, and it's the right one for a market hungry for depth over headlines.
Enterprises race to buy AI compute without tracking what it costs
The compute gap isn't about buying more, it's about seeing what you already own. Across 107 enterprises, GPU utilization sits at 50% or less for 83%, yet 64% plan to switch or add providers within the year. That tension defines the moment: spending is accelerating ahead of measurement, with fewer than half tracking costs rigorously. The next wave of infrastructure decisions will be shaped by visibility, not capacity. Those who close this gap first will steer their AI economics with confidence.
Stop feeding your GPUs the same data twice
GPU memory is the most expensive resource in production AI, and it's running out fastest. Weka's NeuralMesh 6 takes a different path: instead of adding more GPUs, it caches 100% of a model's pre-calculated tokens on cheap flash storage. That cuts the costly recomputation behind long contexts and multi-turn chats. It's a practical fix for GPU scarcity, and one worth exploring, especially if you're chasing better utilization from the hardware you already have.
Why Your AI Model Slows 170x on a T4 vs A100
A 170x slowdown between a T4 and an A100 is not a generational gap; it's a signal that something structural is off. For a point-tracking model with dense 4D correlation volumes and transformer layers in pure FP32, you're likely hitting the T4's lack of Tensor Core support for your exact ops, forcing a fallback to inefficient kernels. But that alone shouldn't explain the magnitude. Profile kernel-level timing first. Look for operations like `grid_sample` or `einsum` that might be serializing on the T4's memory bandwidth.
Enterprises race to buy AI compute while costs stay out of focus
TheAI infrastructure is being bought faster than it can be understood. Across 107 enterprises, GPU utilization sits at 50% or less, and fewer than half can track what their compute actually costs. Yet 64% plan to switch providers within the year, and 45% are evaluating specialized clouds they don't even use today. That gap, between aggressive investment and limited visibility, is where decisions are stalling. Explore how enterprises can close it.