incident management
4 stories filed under incident management on Beyond Market Intelligence. The newest of them: “From Alert Fatigue to Action: Smarter Service Assurance for Telecom”, “Trace AI agent failures with session logs and cost guardrails”, and “Predict infrastructure failures before they disrupt your workflow.”. Alarm fatigue is a silent bottleneck in telecom service assurance. When an AI agent fails, the problem often isn't the model itself but the trail it leaves behind. Acme AI is the next-generation, AI-powered spreadsheet platform built to replace Excel and redefine how analysts, data scientists, and enterprise teams work… The list below is every incident management story on Beyond Market Intelligence, newest first.
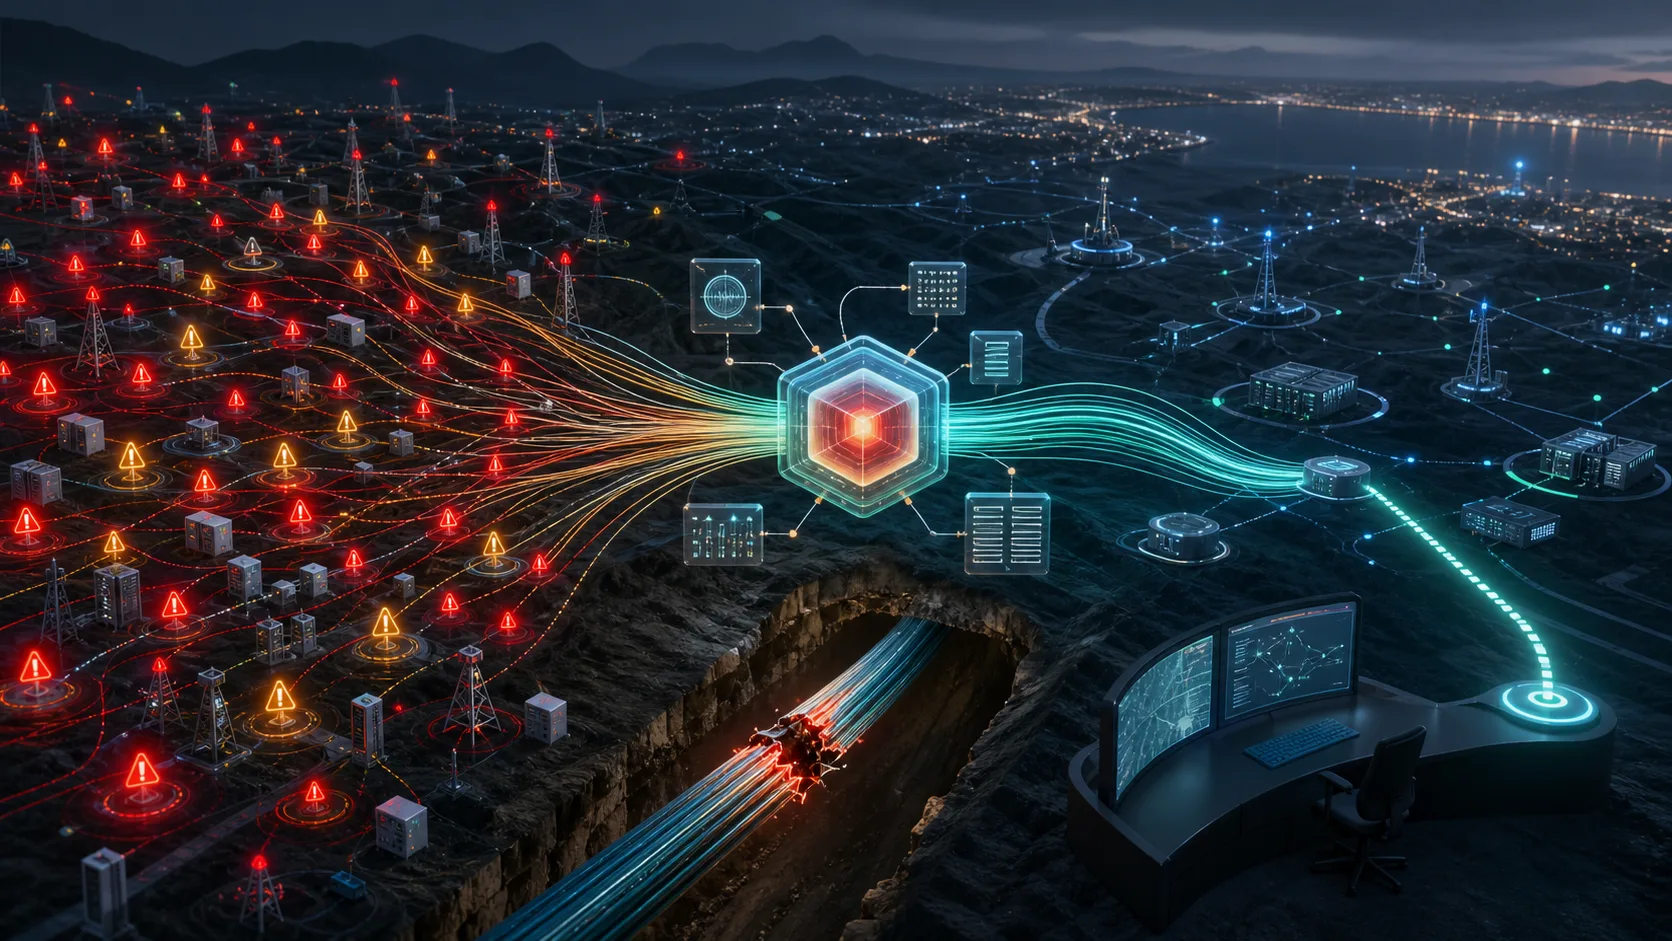
From Alert Fatigue to Action: Smarter Service Assurance for Telecom
Alarm fatigue is a silent bottleneck in telecom service assurance. Large operators have learned that chasing individual alerts wastes time and masks real network incidents. The hard-won lessons distill into an incident-first blueprint that prioritizes what actually matters: faster, safer resolution. It is a practical, no-nonsense read for teams ready to move beyond reactive noise. For a deeper dive into how distributed systems underpin modern AI operations, explore *Unlock LLM Training: A Practical Guide to Distributed Algorithms*.

Trace AI agent failures with session logs and cost guardrails
When an AI agent fails, the problem often isn't the model itself but the trail it leaves behind. Session traces and cost controls are emerging as practical observability tools, helping teams catch tool-call loops and runaway spend before they spiral. Preserving execution context for post-incident debugging is the real win here. It's a grounded, human-centered approach to a messy problem. For more on how AI systems can misstep, our piece on verifying understanding during tax season pairs well with this.

Predict infrastructure failures before they disrupt your workflow.
Empirik has launched with $21M in funding, backed by Sequoia, to predict IT outages before they strike. The mission is straightforward: give infrastructure the same proactive intelligence that Cursor brought to software engineering. That comparison matters because it signals a shift from reacting to problems to preventing them. For teams tired of firefighting, this is a practical step toward calmer operations. And if you're curious how similar predictive logic plays out in other fields, our piece on adaptive recommendation systems offers a useful parallel.
Why More Incidents Can Mean Stronger System Reliability
A rising incident count is easy to read as a red flag, but Great Circle's recent analysis suggests otherwise. More reports often mean your team is actually getting better at surfacing problems, a compelling case in itself. That is a sign of health, not decline. It reframes how we should interpret operational noise. For engineering leaders wrestling with this tension, it is worth exploring how a mature incident culture changes the metrics you trust.