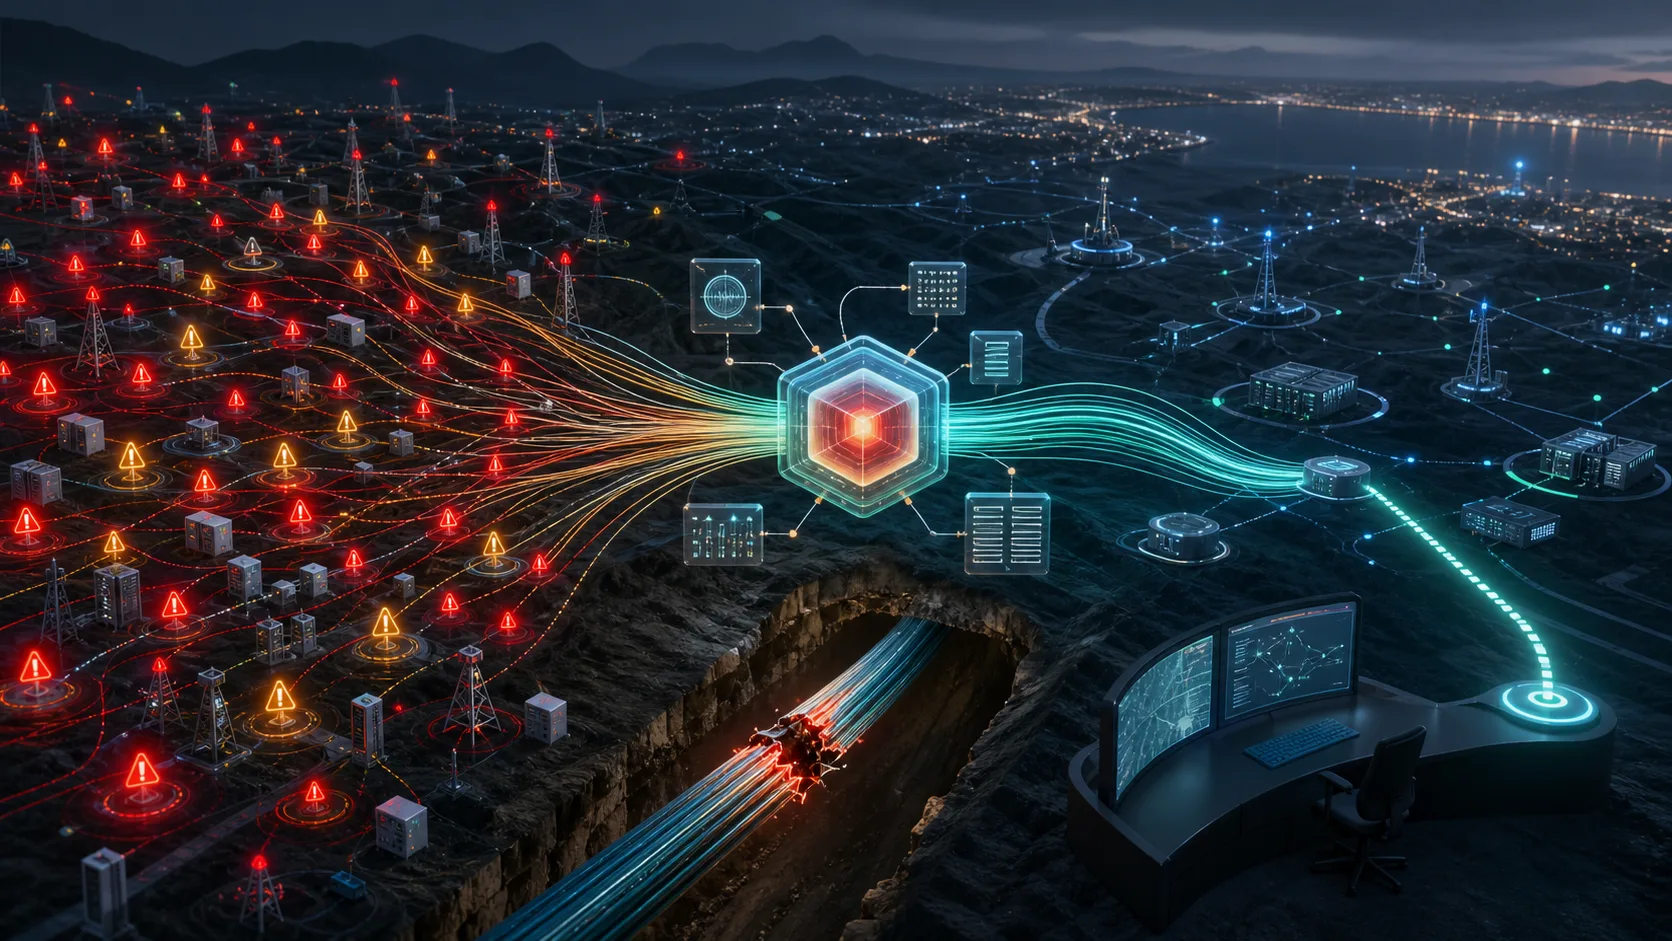
Alarm fatigue has quietly become the default state of operations teams in telecom. The argument that we should stop managing alarms and start resolving incidents is not a tweak to existing workflows. It is a fundamental reframing of what service assurance means. Large operators have learned that a dashboard full of red is not intelligence; it is noise that buries the one alert that actually matters. The insight here is that incident-first thinking is not about building better filters, but about changing the question from "what is broken" to "who is affected and how do we fix it fastest."
This approach resonates with a broader pattern we have been tracking across the AI and data infrastructure space. For instance, Exploring Paragraph Structure: How LLMs Navigate Token Space shows how a similar conceptual shift, moving from treating tokens as isolated units to understanding their structural relationships, can unlock new capabilities. Likewise, Unlock LLM Training: A Practical Guide to Distributed Algorithms demonstrates that scaling models is less about raw compute and more about orchestrating distributed processes efficiently. Both of those stories share a common thread with the telecom piece: the real bottleneck is not missing information, but the inability to see the signal within the noise. In telecom, that means moving from a reactive posture, where engineers are constantly paging each other, to a proactive state where the system surfaces a coherent incident narrative.
Our honest take is that most teams are not ready for this shift, not because they lack the tools, but because they lack the discipline to trust the incident, not the alarm. The blueprint is practical, but it demands a cultural change. It asks operators to stop treating every alert as a crisis and instead to focus on the service impact. This is a hard sell in an industry where uptime is paramount and false positives have trained everyone to ignore the system. Yet, the payoff is real: faster mean time to resolution, fewer false escalations, and a team that actually sleeps at night. If you are an operator, the first step is not to buy new software, but to audit your current alert rules and ask which ones have not fired a legitimate incident in the last month. Those are the alarms you should silence first.
The specific consequence to watch is how this philosophy intersects with AI-driven automation. If you shift to incident-first, you are essentially asking your AIOps platform to do more than correlate logs. You are asking it to understand context, to know that a router failure in one region is not an incident if traffic is rerouted automatically, but it is an incident if customer SLAs are breached. That is a high bar, and the suggestion to start with the largest operators who have the data to train such systems is wise. For everyone else, the takeaway is simpler: stop managing alarms, start managing outcomes. A quote worth carrying forward is that "the goal is not to reduce the number of alerts, but to reduce the number of decisions a human has to make." That is the metric that matters.