inference speed
3 stories filed under inference speed on Beyond Market Intelligence. The newest of them: “Explore how LLM inference architecture evolves through open discussion”, “What Happens in That Split Second Before AI Responds”, and “Open video creation meets open weights in a faster, more accessible AI model”. The most productive research conversations happen around a table, not in a lecture hall. That brief pause before an AI starts typing isn't dead time, it's the first of two distinct jobs your GPU is handling. Acme AI is the next-generation, AI-powered spreadsheet platform built to replace Excel and redefine how analysts, data scientists, and enterprise teams work… The list below is every inference speed story on Beyond Market Intelligence, newest first.
Explore how LLM inference architecture evolves through open discussion
The most productive research conversations happen around a table, not in a lecture hall. Inspired by Bell Labs' legendary lunch discussions, one developer wants to recreate that collaborative energy for LLM inference architecture. After two months of hands-on work, they're asking the community to share the latest papers and debate approaches openly. If you're curious how AI-native tools like Siri Recaps balance utility with privacy concerns, that ongoing discussion touches similar themes of practical innovation.
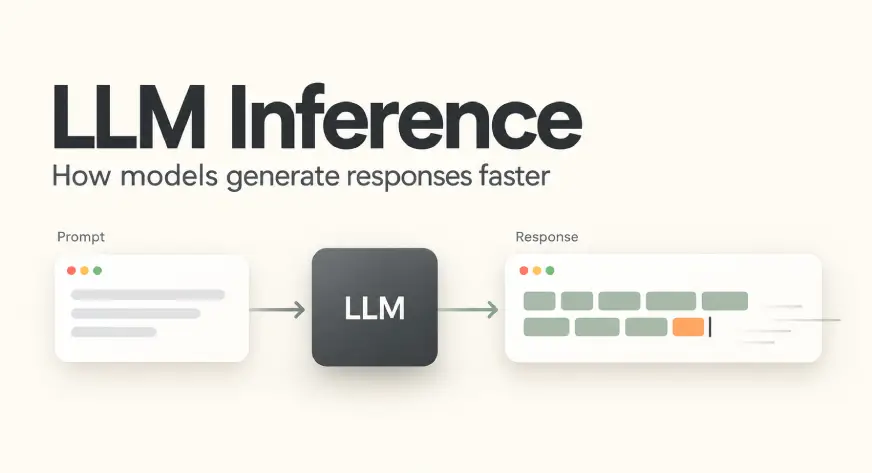
What Happens in That Split Second Before AI Responds
That brief pause before an AI starts typing isn't dead time, it's the first of two distinct jobs your GPU is handling. First comes comprehension: parsing your question into computational intent. Then comes generation: producing each word in sequence, one after another. Understanding that split-second workflow transforms how you build responsive AI applications. For deeper context on how these models work autonomously, explore "Your AI team works through the night so you wake to a finished newsletter."
Open video creation meets open weights in a faster, more accessible AI model
LTX-2.5 turns a single image into a 10-second video in under seven seconds on Nvidia superchips, and it's open weights. That speed, paired with native ComfyUI integration, gives builders a direct path from experimentation to production without locking data or IP into a closed API. For teams testing the edges of real-time video, this is the practical next step. Explore what an open model can do when the infrastructure finally catches up.