LLM Serving
LLM Serving at Beyond Market Intelligence is a file of 2 stories. The newest of them: “Optimize LLM memory with a VRAM formula and three targeted strategies” and “Smart Caching: Optimizing LLM Performance and Reducing Costs”. Inference servers don't hit a compute wall first; they hit a memory one. Every request your LLM handles may carry millions of tokens, yet much of that data repeats across calls. Acme AI is the next-generation, AI-powered spreadsheet platform built to replace Excel and redefine how analysts, data scientists, and enterprise teams work… The list below is every LLM Serving story on Beyond Market Intelligence, newest first.
Optimize LLM memory with a VRAM formula and three targeted strategies
Inference servers don't hit a compute wall first; they hit a memory one. The KV cache tax quietly consumes your VRAM budget, leaving GPUs idle while requests stall. This piece breaks down the formula behind that imbalance and maps three optimization strategies to the exact traffic patterns that trigger out-of-memory errors. It's a practical look at why serving fails and how to plan around it. For a deeper foundation on distributed systems, pair this with our guide to distributed training algorithms.
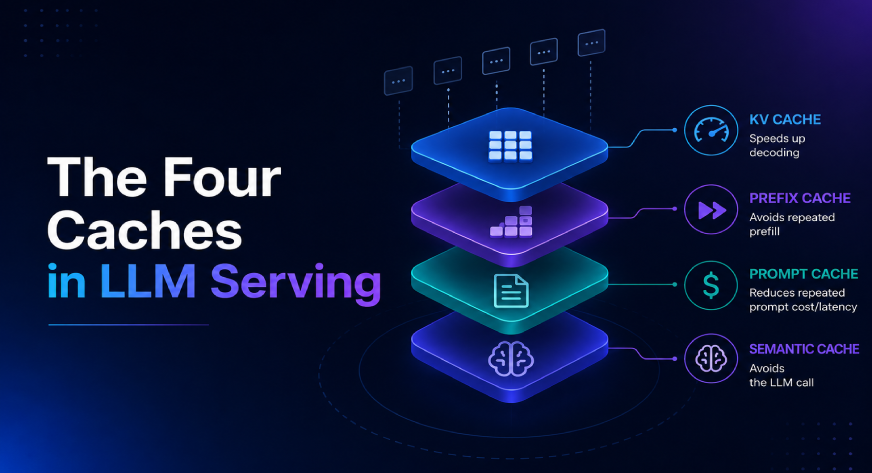
Smart Caching: Optimizing LLM Performance and Reducing Costs
Every request your LLM handles may carry millions of tokens, yet much of that data repeats across calls. Reprocessing it wastes time and drives up compute costs. Smart caching targets exactly this waste, and the new piece breaks down the four cache layers that make serving faster and cheaper. It's a practical read for anyone tired of paying twice for the same work. For a deeper look at distributed systems, our guide to distributed algorithms pairs well with this one.