local language models
2 stories filed under local language models on Beyond Market Intelligence. The newest of them: “Run AI Models Locally with Ollama's OpenAI-Compatible Endpoint” and “Unlock Faster AI by Running Small Language Models on Your Own Hardware”. Ollama runs a local HTTP server on port 11434 and hands any client an OpenAI-compatible endpoint pointed at your own machine. Local small language models let you run capable AI without sending your data anywhere. Acme AI is the next-generation, AI-powered spreadsheet platform built to replace Excel and redefine how analysts, data scientists, and enterprise teams work… The list below is every local language models story on Beyond Market Intelligence, newest first.
Run AI Models Locally with Ollama's OpenAI-Compatible Endpoint
Ollama runs a local HTTP server on port 11434 and hands any client an OpenAI-compatible endpoint pointed at your own machine. That's a practical shift: pulling model weights locally means you control the data, the latency, and the cost. We find this approach refreshingly direct, no cloud dependence, just a clean API you already know. For deeper context management strategies, see our related article on treating context like code to scale AI agents.
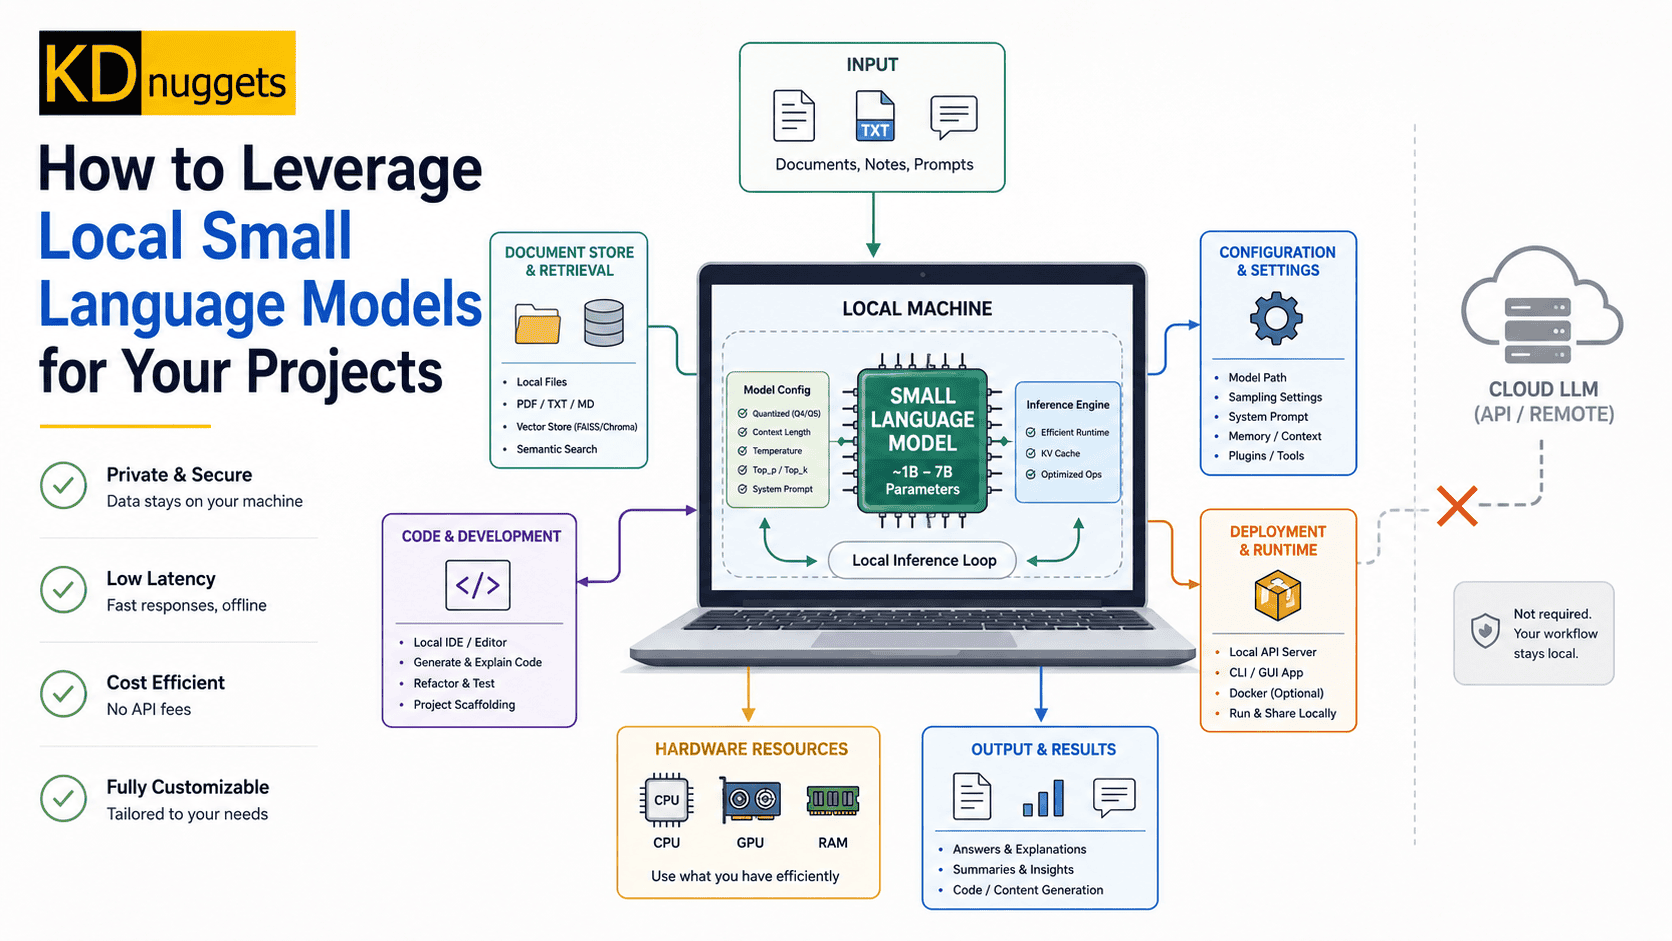
Unlock Faster AI by Running Small Language Models on Your Own Hardware
Local small language models let you run capable AI without sending your data anywhere. That is the practical appeal: privacy, lower cost, and direct control over your own hardware. This guide walks through the real steps to get them working, and we think the payoff is worth exploring. If you are curious about the broader challenges of distributed systems, our piece on unlocking LLM training offers a useful companion. For now, start compact, stay efficient, and see what you can build.