model comparison
Beyond Market Intelligence keeps model comparison in one place: 11 stories so far. The section currently leads with “When Simpler Tools Match Advanced AI on Intent Classification”, “When you have labels, classic models outperform the AI hype”, and “Explore Multiple AI Models from One API to Simplify Your Python Workflows”. Jev's approach to intent classification is refreshingly practical: no training required, and at most three examples per intent. Classic models beat the hype when you have labels. Acme AI is the next-generation, AI-powered spreadsheet platform built to replace Excel and redefine how analysts, data scientists, and enterprise teams work… The list below is every model comparison story on Beyond Market Intelligence, newest first.
When Simpler Tools Match Advanced AI on Intent Classification
Jev's approach to intent classification is refreshingly practical: no training required, and at most three examples per intent. Yet in a direct comparison on BANKING77, scikit-learn matched or beat Jev's calibration. Both methods still stumble into the none-of-the-above trap, a reminder that simpler tools paired with advanced AI aren't immune to classic classification challenges. For teams building smarter pipelines, the companion piece on Scikit-LLM offers a natural next step toward multilingual text workflows.
When you have labels, classic models outperform the AI hype
Classic models beat the hype when you have labels. We tested embedding inputs with a cheap model, then fitting a simple sklearn model on top using your own labels. The result? A 37% error reduction against Jev, at a fraction of the cost. It's not glamorous, but it works. For deeper context on smarter decision-making, see our guide on "How Your Agent's Tools Can Make Smarter Decisions."
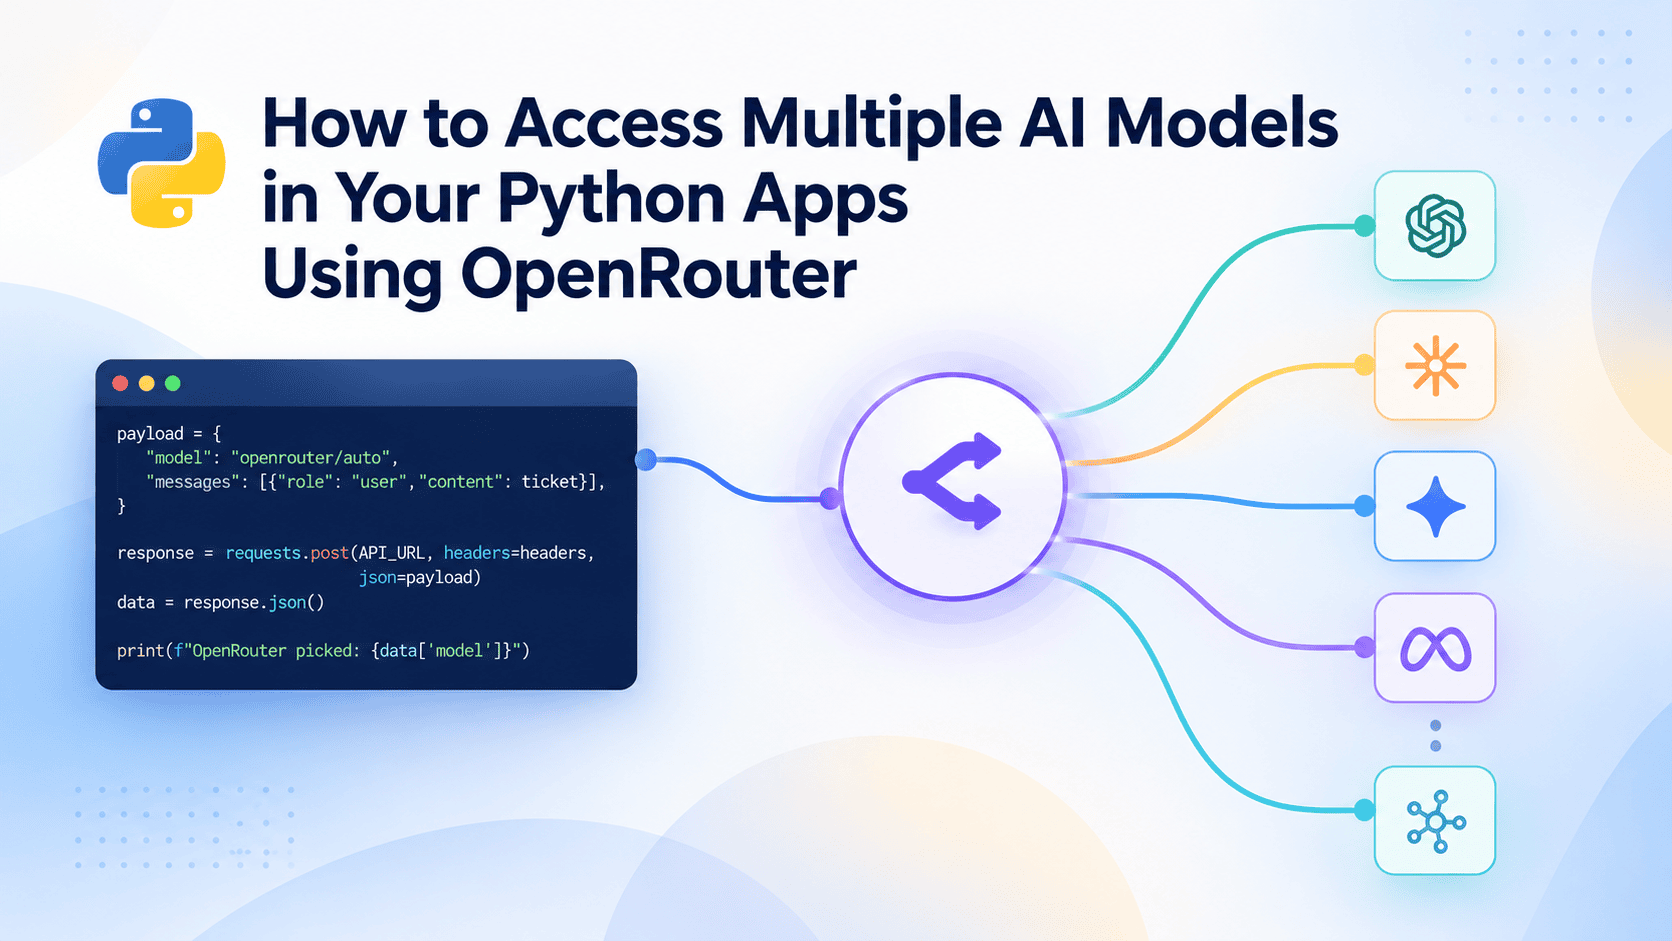
Explore Multiple AI Models from One API to Simplify Your Python Workflows
Juggling multiple AI models usually means juggling multiple APIs, keys, and codebases. OpenRouter changes that by letting you call dozens of models through a single endpoint. You can compare responses side by side, swap models on the fly, and even build automatic fallbacks when one provider stumbles. It's a practical way to make your Python workflows more resilient without adding complexity. If you're curious how local models fit into this picture, our piece on WebAI is worth a look.
We put a free AI humanizer to the test against paid detectors
A free, open-source AI humanizer running a 12B model on a local machine just went head-to-head with paid detectors. We tested it to see whether the hype holds up. The results challenge a common assumption: that you need expensive tools to outsmart detection. If you're exploring how these systems work under pressure, our piece on "Examining AI Detection Tools and Their Role in Scholarly Review" offers a deeper look at the detectors themselves. The free option earned its place in the conversation.
Stacking Only Wins When Your Models Disagree
Stacking only pays off when your models disagree. If every model in your ensemble stumbles on the same rows, combining them just compounds the error. The real win comes from diversity, models that fail differently can cover each other's gaps. That distinction matters more than chasing a slightly better single model. For teams wrestling with how to build reliable pipelines, this is the practical insight worth testing.
When AI judges ignored the image, GPT-4o invented answers while Claude stuck with B
Three vision AI models were shown an image, and they ignored it. GPT-4o invented answers rather than admit it couldn't see, while Claude stubbornly stuck with "B." The trap was set for image judges, but they walked into a different one entirely. It is a fascinating look at how these models handle uncertainty, or fail to. For more on what models are actually doing under the hood, explore our coverage of ten Hugging Face models reshaping data work.
Unlock ChatGPT Work's Potential: A Clear-Eyed Look at Strengths & Limits
ChatGPT Work gets credit where it's earned, but a clear-eyed look matters more than hype. It's a capable tool that simplifies real workflows, yet its limits are just as instructive as its strengths. The models behind it hold their own in many comparisons, but honest assessment beats blind praise. For anyone weighing adoption, this piece cuts through the noise. Curious how verification fits into that picture? Check out "Verify Your AI's Understanding: A Simple Check for Tax Season" for a practical angle.

Discover how AI redefines your spreadsheet workflow through a simple experiment
When I ran Fable against Astra, the gap between them wasn't subtle. Fable handled the workflow with a fluidity that felt natural, while Astra demanded more patience. It's a reminder that AI tools aren't interchangeable; they carry distinct personalities. For anyone weighing similar choices, I'd point to our earlier piece on the Forrester function. It's a different lens, but it reinforces how small mathematical insights can sharpen your evaluation of these systems. The experiment didn't just compare outputs; it exposed what each model prioritizes.
Choose Your Coding Agent: A Practical Guide to Claude and Codex
Choosing the right coding agent can feel like navigating a maze, especially when both Claude Code and Codex promise to streamline your workflow. This guide cuts through the noise, offering a clear breakdown of where each tool shines. It's a practical read for anyone tired of guessing which assistant fits which task. I appreciate how it prioritizes real-world application over hype.
Stop struggling with every new dataset and start exploring smarter workflows.
The process of testing ten ML models on every new dataset is exhausting, and it's a familiar pain for anyone who's tried. The team at Arcliq decided to automate that grind, focusing on the messy parts like preprocessing and model selection. Their platform handles the heavy lifting, letting you upload a tabular dataset and receive a working model without needing deep expertise. It's early days, but they're opening a private beta to get real feedback. That's a smart move.

Explore how synthetic query probing makes embedding models truly comparable
Embedding models are rarely interchangeable, yet swapping one for another often feels like a roll of the dice. Synthetic Query Probing tackles this head-on by comparing similarity spaces instead of raw vectors. The results show Titan's scores relate across dimensions, but Titan versus Ada is nonlinear with different ranges. That is a practical insight for setting retrieval thresholds. For a deeper look at how clean data shapes model behavior, our piece on catching AI slop before it skews your model pairs well with this research.