model optimization
3 stories filed under model optimization on Beyond Market Intelligence. The newest of them: “Google's LiteRT Tensor API brings flexible ML model building to on-device”, “Five Production Methods to Make Your LLM Leaner and Faster”, and “Balancing the Unbalanced: Smarter Loss Functions for Medical AI”. Google's new LiteRT Tensor API gives developers a lightweight C++ path to build and optimize machine learning models directly on-device. Every parameter in your model costs money, and too many of them mean your inference bill climbs with every prompt. Acme AI is the next-generation, AI-powered spreadsheet platform built to replace Excel and redefine how analysts, data scientists, and enterprise teams work… The list below is every model optimization story on Beyond Market Intelligence, newest first.
Google's LiteRT Tensor API brings flexible ML model building to on-device
Google's new LiteRT Tensor API gives developers a lightweight C++ path to build and optimize machine learning models directly on-device. It's a practical move that blends the flexibility of native model authoring with genuine cross-platform portability, no cloud dependency required. For anyone exploring how to push ML workloads closer to the user, this API makes that transition feel more accessible. If you're curious about how frontier LLMs interact with neural network weights on a deeper level, our piece on weight-space programming offers a compelling follow-up.
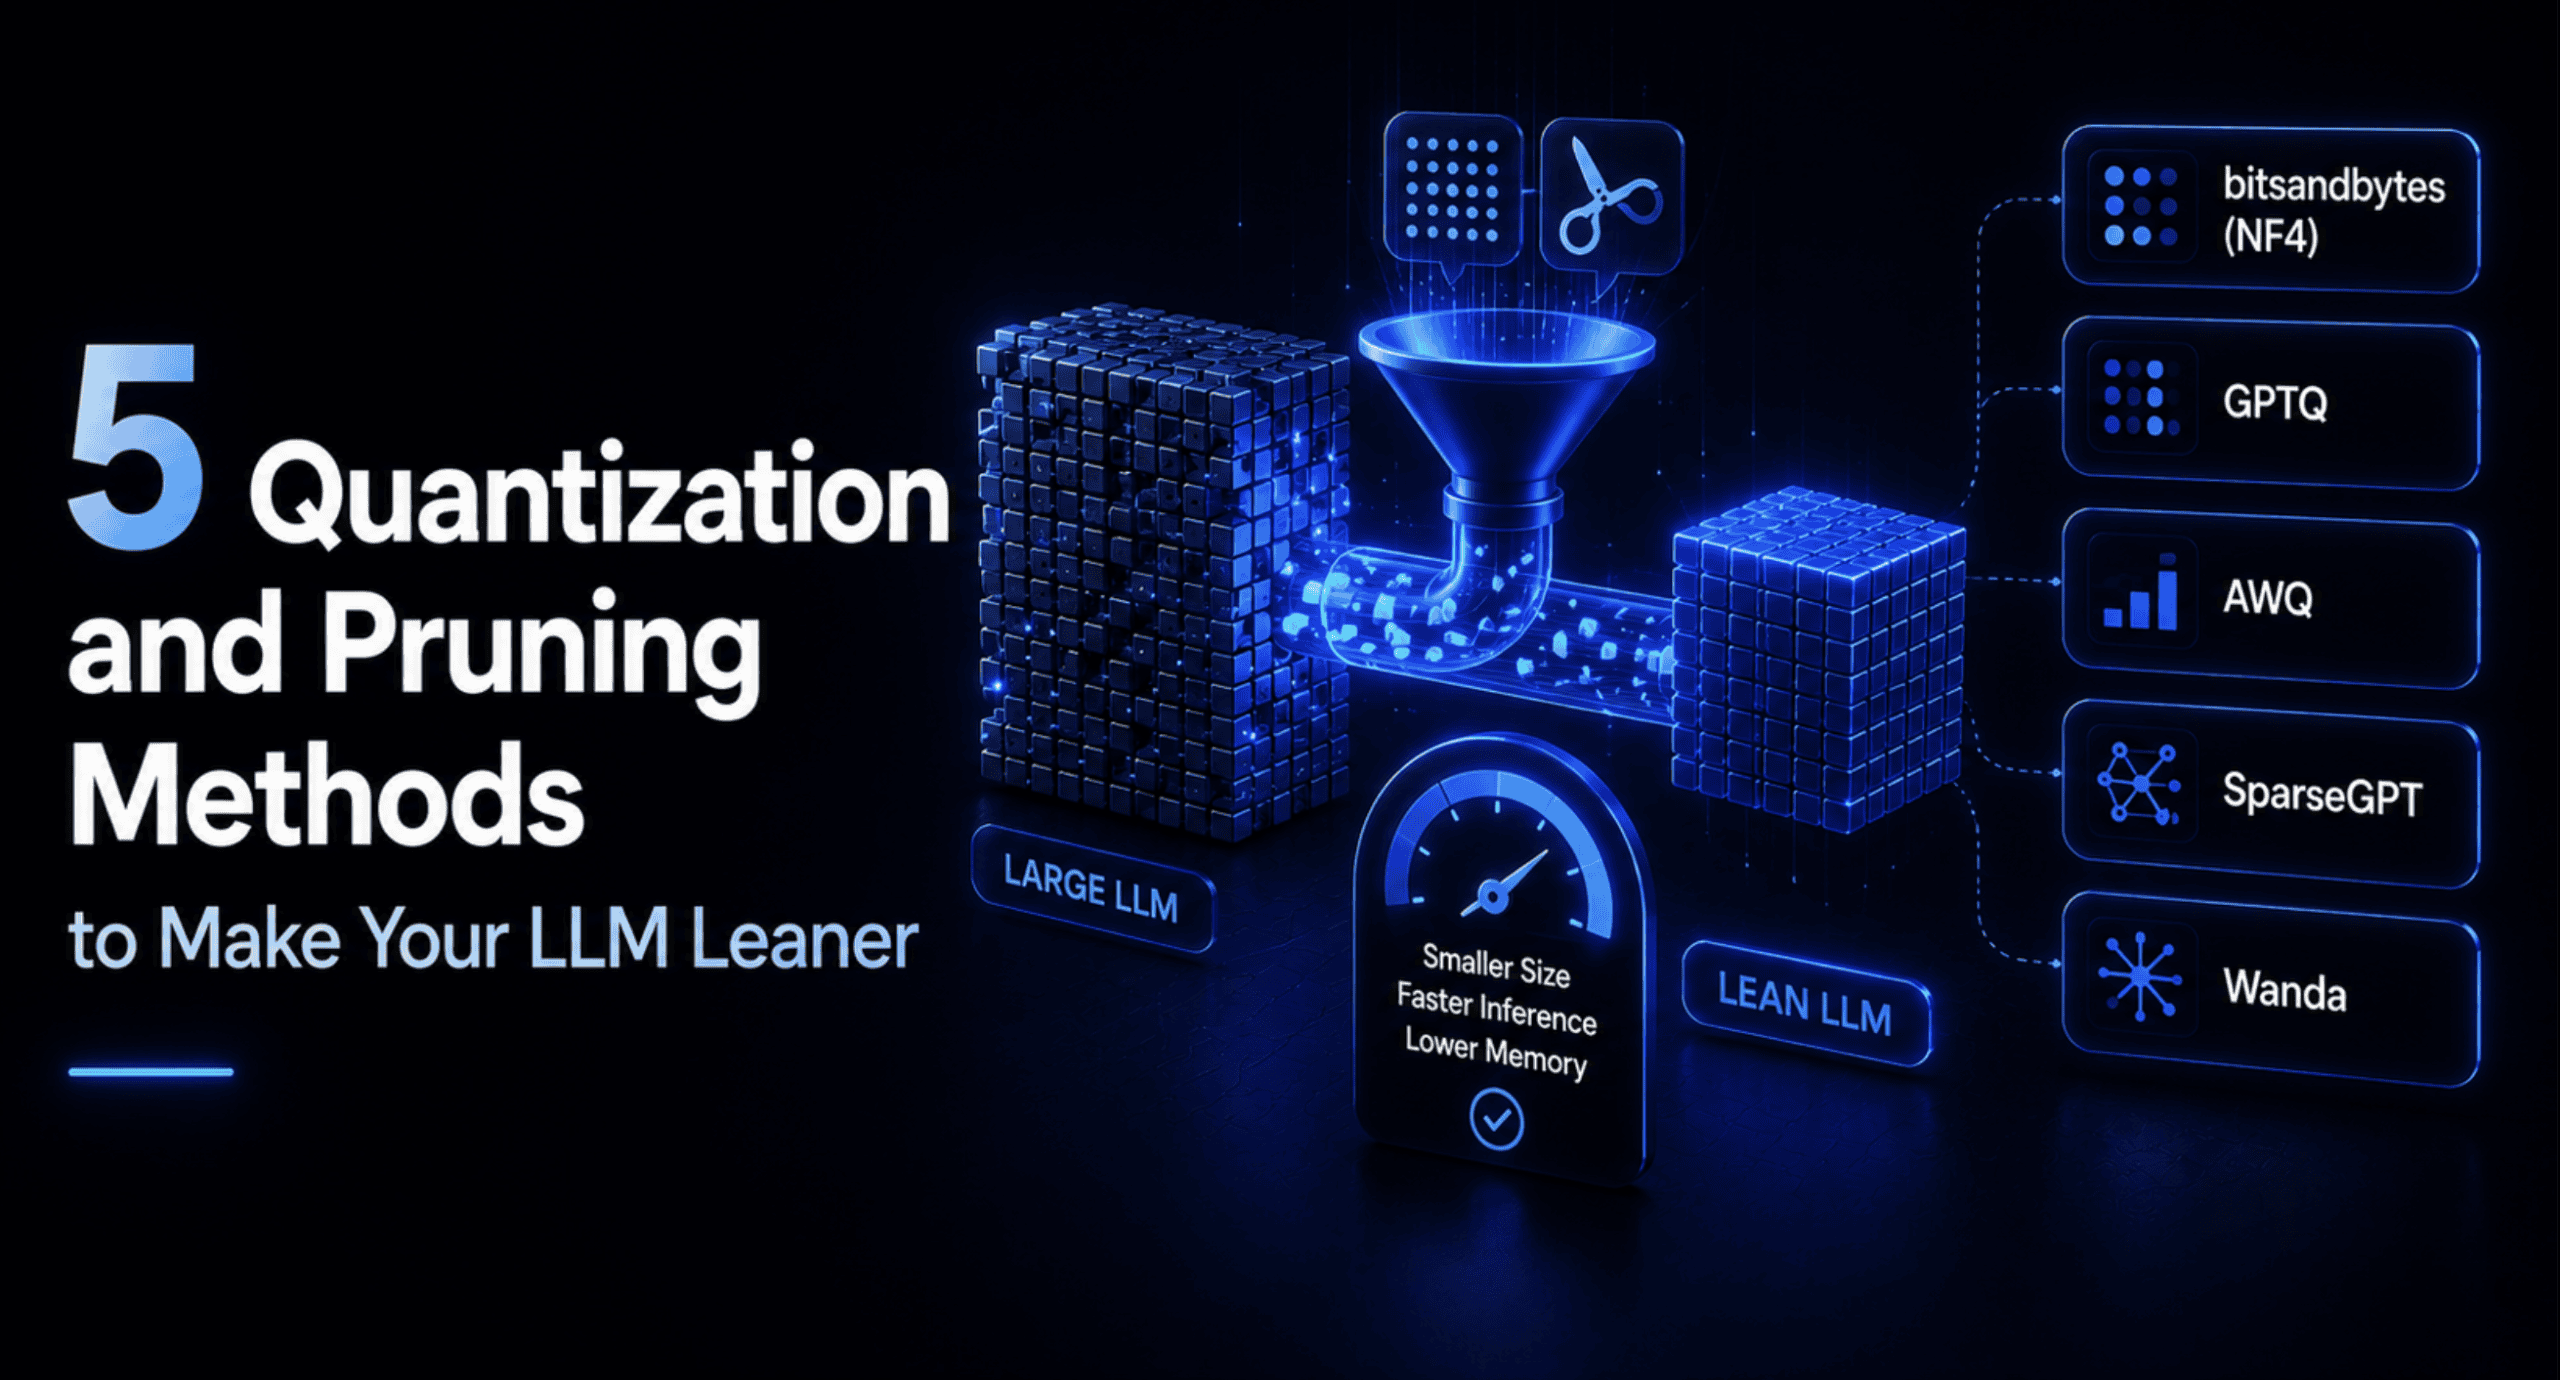
Five Production Methods to Make Your LLM Leaner and Faster
Every parameter in your model costs money, and too many of them mean your inference bill climbs with every prompt. Quantization and pruning are how you cut that weight without gutting performance, and skipping them leaves you paying for latency you do not need. Quantization and pruning cut model weight without gutting performance, and five production methods demonstrate how. If you are still unpacking how distributed systems shape model training, our guide to distributed algorithms pairs well with this one.
Balancing the Unbalanced: Smarter Loss Functions for Medical AI
Three models collapsing toward BIRADS 1 is a familiar wall when a dataset leans that hard. The VinDr imbalance is likely steering your cross-entropy, even with class weights and center loss in the mix. You are not wrong to question the loss function, but the weights may need recalibration or a focal-style adjustment to resist the majority pull. Before abandoning the approach, audit your sampling strategy and weight initialization.