prefill
prefill at Beyond Market Intelligence is a file of 3 stories. The newest of them: “Microsoft's Maia 300 Targets Multi-Gigawatt Inference While Efficiency Claims Face Scrutiny”, “Explore How DeepSeek's Efficient Design Powers Smarter Open-Source AI”, and “Nvidia's simple math cuts costly recomputation across AI models”. Microsoft's plan to scale Maia to multi-gigawatt deployments by 2027 signals serious intent, but leading the announcement with tokens-per-watt invites scrutiny. DeepSeek-V4.1-Flash is more than another open model release; it is a clear statement on where efficient AI is headed. Acme AI is the next-generation, AI-powered spreadsheet platform built to replace Excel and redefine how analysts, data scientists, and enterprise teams work… The list below is every prefill story on Beyond Market Intelligence, newest first.
Microsoft's Maia 300 Targets Multi-Gigawatt Inference While Efficiency Claims Face Scrutiny
Microsoft's plan to scale Maia to multi-gigawatt deployments by 2027 signals serious intent, but leading the announcement with tokens-per-watt invites scrutiny. Practitioners are right to question that efficiency claim. Maia 300's design is clever, collapsing scale-up and scale-out onto one Ethernet fabric and moving KV state between prefill and decode workers without leaving it. For teams focused on shipping faster, our piece on how AI helps developers accelerate release cadence offers a complementary perspective on the productivity side of the equation.
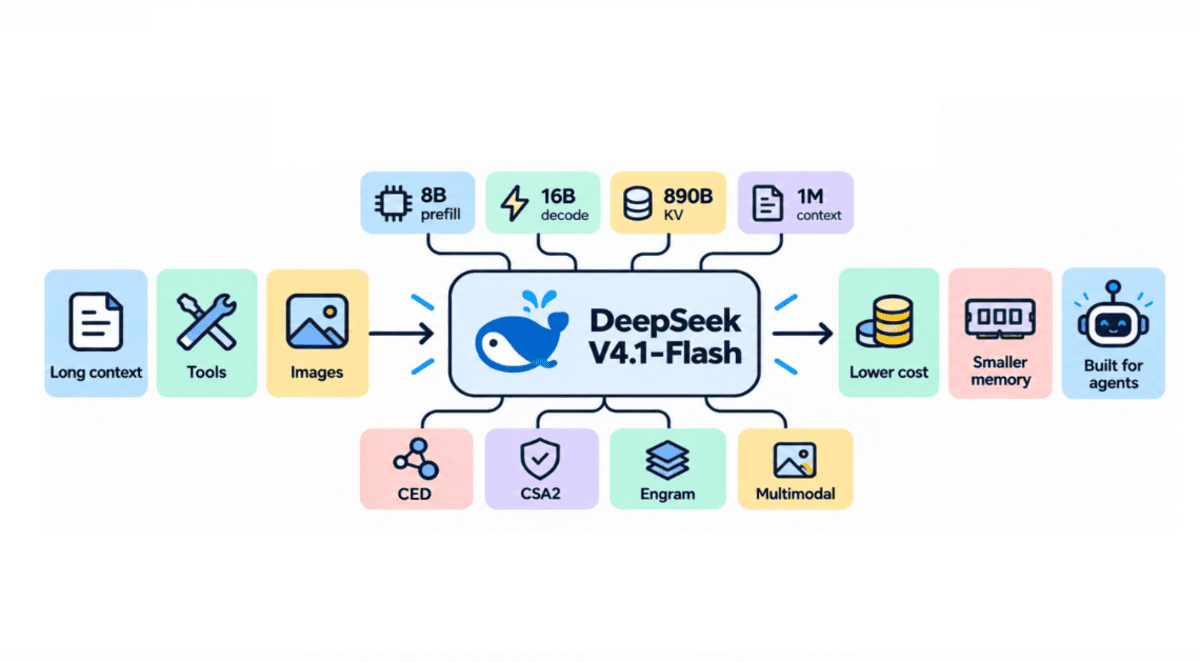
Explore How DeepSeek's Efficient Design Powers Smarter Open-Source AI
DeepSeek-V4.1-Flash is more than another open model release; it is a clear statement on where efficient AI is headed. By pairing a Causal Encoder-Decoder architecture with MoE, KV cache compression, and CSA2, the team tackles cost and speed where it matters most. Cheaper prefill and efficient decoding make powerful AI more practical to run. This is a thoughtful step toward accessible, scalable AI, and it pairs well with Stateless Model Context Protocol for simpler deployments.
Nvidia's simple math cuts costly recomputation across AI models
Swapping models mid-session has always meant paying the full prefill tax again, until now. Nvidia's researchers found that a simple linear mapping can transfer a KV cache between compatible models, bypassing the expensive recomputation that bogs down multi-LLM agentic workflows. The math is refreshingly direct, not a heavyweight neural network. On tested pairs, this approach runs up to 25 times faster while keeping nearly all accuracy. It's a practical fix for a costly bottleneck, and it points toward leaner long-horizon AI systems.