probabilities
3 stories filed under probabilities on Beyond Market Intelligence. The newest of them: “Calibrate classifier probabilities in Python with Platt scaling and isotonic regression”, “Cross-platform AI compression that stays consistent across any hardware”, and “Explore How Jev Projects Bring Clarity to AI Decision-Making”. A classifier that outputs confident probabilities isn't always telling the truth. One hash across seven backends proves that integer-only inference can solve the cross-platform compression problem that has long plagued LLM deployment. Acme AI is the next-generation, AI-powered spreadsheet platform built to replace Excel and redefine how analysts, data scientists, and enterprise teams work… The list below is every probabilities story on Beyond Market Intelligence, newest first.
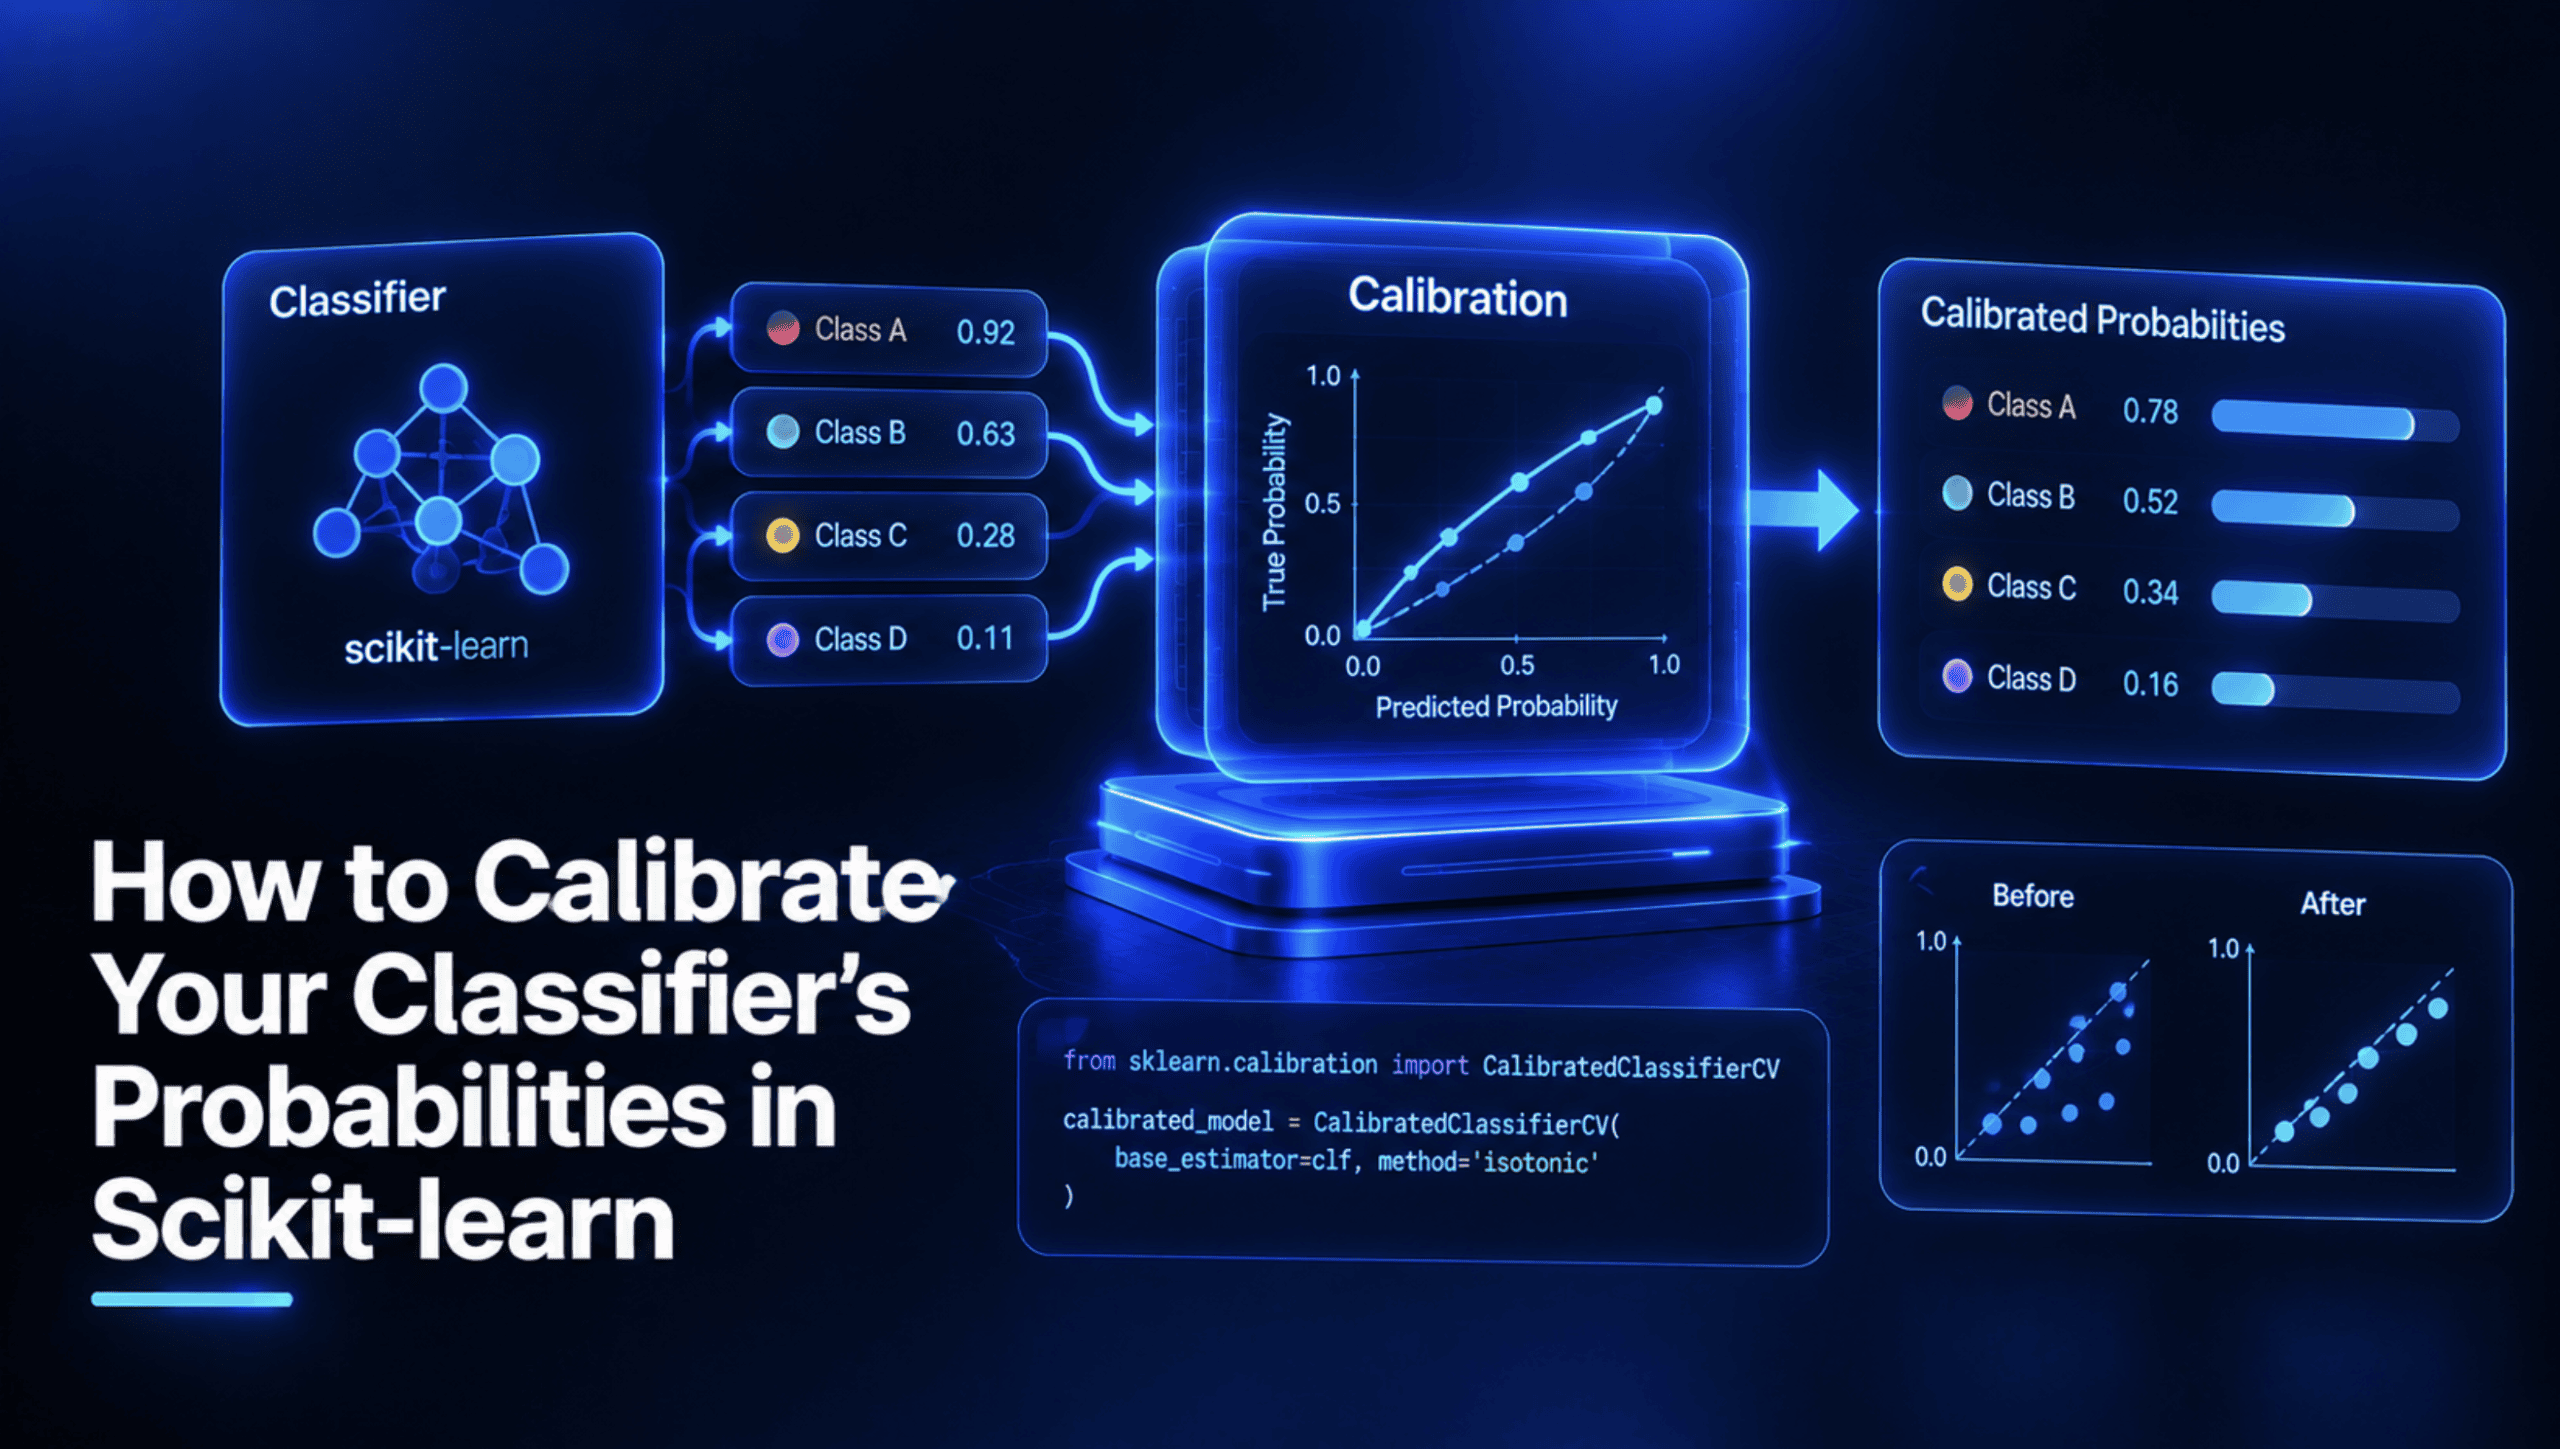
Calibrate classifier probabilities in Python with Platt scaling and isotonic regression
A classifier that outputs confident probabilities isn't always telling the truth. Miscalibration is a quiet problem that undermines trust in your model's predictions. This tutorial walks through training two scikit-learn classifiers on real data, exposing their miscalibration with a reliability diagram and Brier score, then fixing it with Platt scaling and isotonic regression. It's a practical fix for a common gap. For more on building reliable tools, see our piece on turning product updates into videos your audience will actually watch.
Cross-platform AI compression that stays consistent across any hardware
One hash across seven backends proves that integer-only inference can solve the cross-platform compression problem that has long plagued LLM deployment. When float GPT-2 encoded on a Mac decoded zero of four windows on x86, the root cause was clear: floating-point inconsistency across hardware. This project's solution, int8 weights, fixed rounding, and lookup tables, delivers exact reproducibility without sacrificing performance. For deeper context on building efficient AI systems, our "Building a GPT-2 KV Cache" piece explores similar performance measurement challenges.
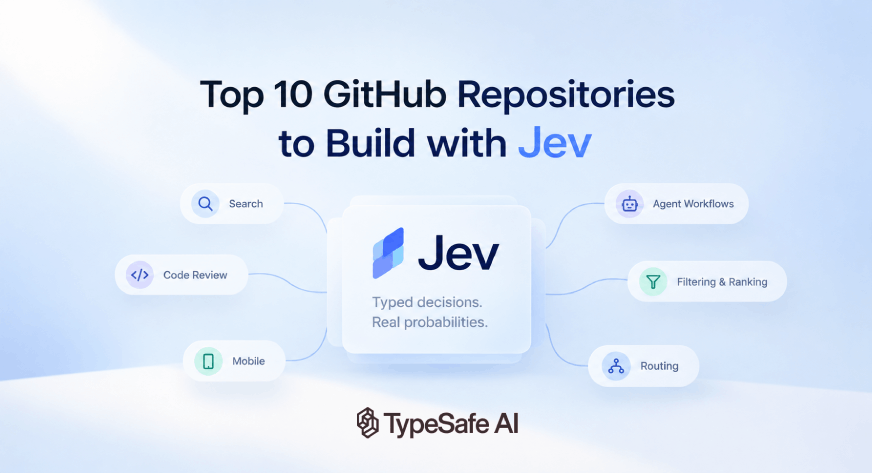
Explore How Jev Projects Bring Clarity to AI Decision-Making
Every agent makes dozens of small calls before delivering something useful: which source to trust, which tool to invoke, when to stop. Jev pulls those hidden choices into the open, converting them into typed decisions with probabilities rather than free-form text. That clarity makes the reasoning auditable and the output more dependable. For anyone exploring how structured judgment improves AI workflows, the GitHub projects offer a practical starting point. Related coverage on why small decision models outperform LLMs for answer evaluation deepens the conversation nicely.