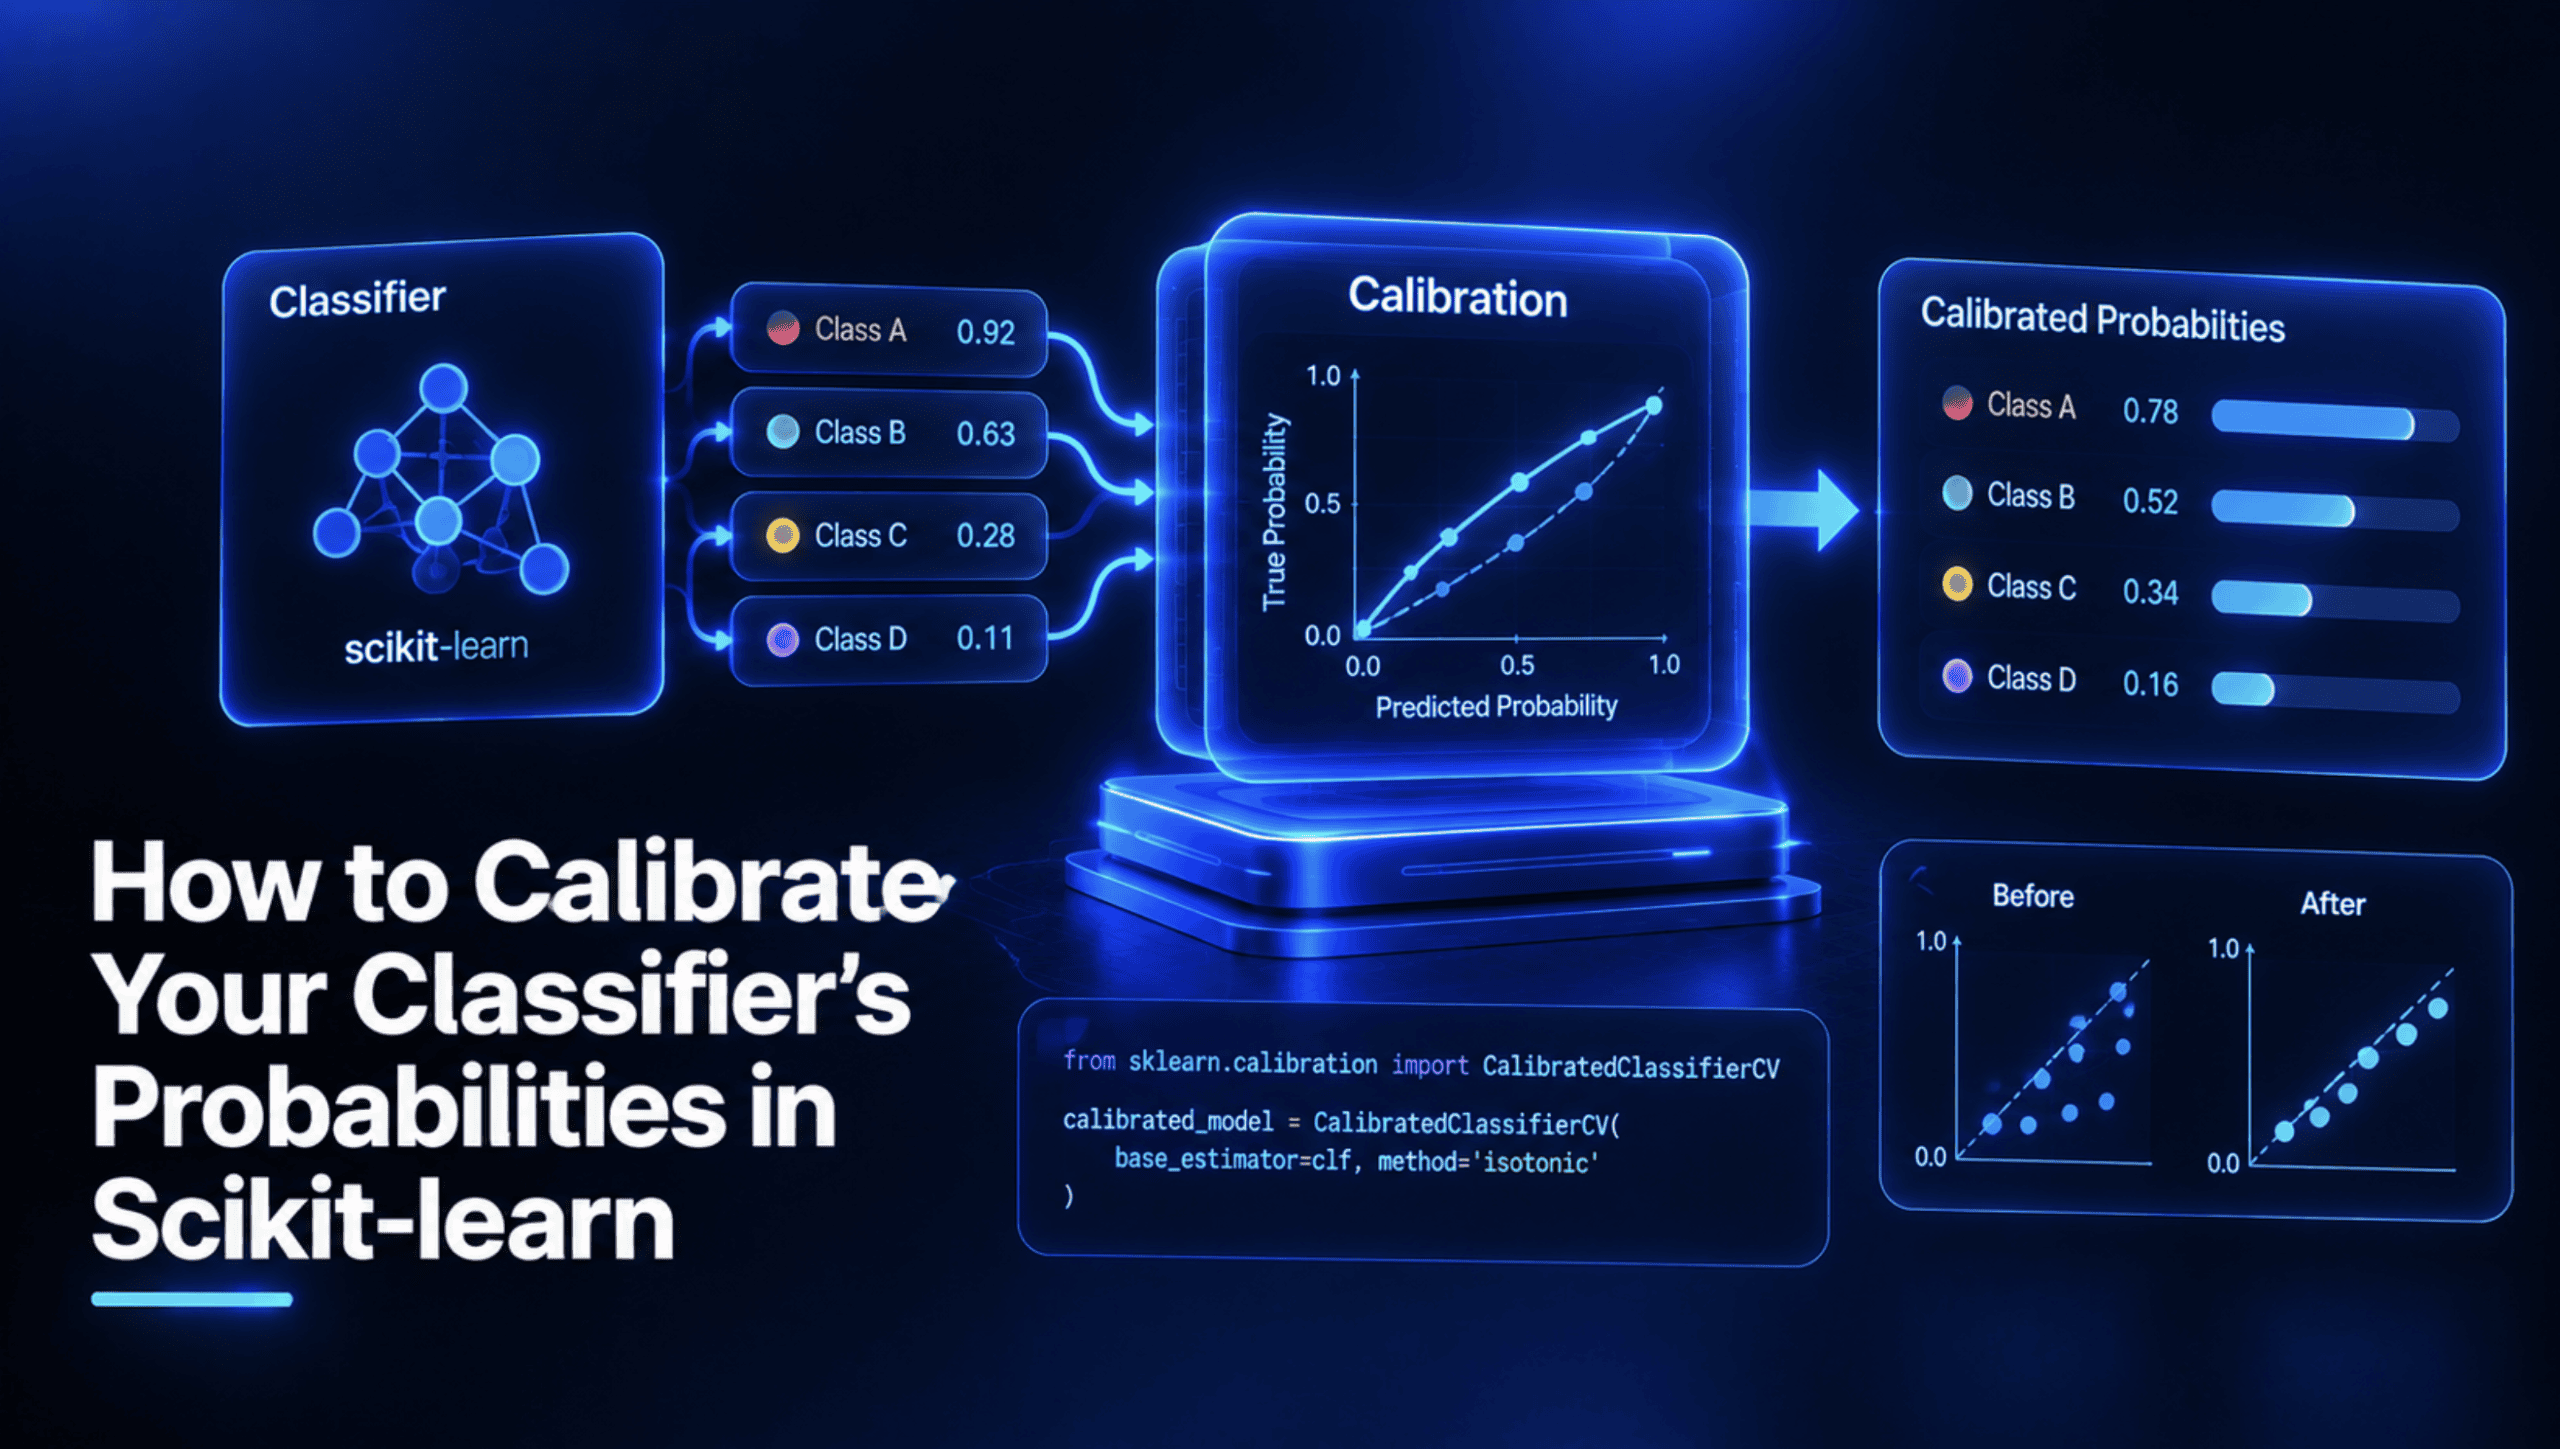
If your classifier outputs a confidence score of 0.8, you want that to mean it's right 80% of the time. That's the baseline promise of a well-calibrated model. Yet most off-the-shelf classifiers don't deliver this, and when we train them on real-world data, the gap between what they claim and what they deliver can quietly undermine every decision downstream. The tutorial on calibrating classifier probabilities with Platt scaling and isotonic regression is a necessary course correction: it walks through training two scikit-learn classifiers, exposing their miscalibration with a reliability diagram and a Brier score, and then fixing it. This isn't a niche concern. It's the difference between a model that looks good on paper and one that actually earns your trust in production.
The practical insight here is that probability calibration is a step many teams skip, and they do so at their own risk. A reliability diagram shows you, in plain visual terms, where your model is overconfident or underconfident. The Brier score gives you a single number to track improvement. Then Platt scaling (parametric) and isotonic regression (non-parametric) offer two distinct paths to alignment. This mirrors a pattern we see across modern data workflows: the tools exist to make models more honest, but they require deliberate adoption. It's similar to the approach we explored in Model Markov Chains in Python with NumPy for Smarter Data Workflows, where building a transition matrix isn't just an academic exercise, it gives you a concrete handle on uncertainty in state-based systems. Both cases demand that you move beyond training accuracy and into the harder question of how your model behaves when it's wrong.
What makes this calibration technique particularly valuable is its accessibility. You don't need a deep learning cluster or a custom loss function. You need a real dataset, two classifiers from scikit-learn, and the willingness to inspect your own output. The same spirit of lightweight, high-leverage tooling shows up in A fast, lightweight audio model that delivers typed decisions from speech, where the goal is to strip away unnecessary complexity and get straight to reliable decisions. Platt scaling and isotonic regression are exactly that kind of tool: they correct the calibration without retraining the classifier, so you preserve the model's discriminative power while making its probabilities trustworthy. For any team shipping predictions to customers or stakeholders, that's a direct improvement to the product.
The concrete takeaway is this: add a reliability diagram and a Brier score to your evaluation pipeline before your next deployment. You will likely discover miscalibration you didn't know existed. Then apply isotonic regression if you have enough calibration data to avoid overfitting, or Platt scaling if you need a simpler, more robust fix. The tutorial gives you the code to do both. The open question is whether your organization has the discipline to inspect its own models that closely, because the data won't flag this problem for you.