profiling
7 stories filed under profiling on Beyond Market Intelligence. The newest of them: “From naive GEMM to FlashAttention: a free code-first GPU kernel series”, “A free guide to making ML models faster, from silicon to agents”, and “Unlock Deeper TPU Insights: Cycle-Level Profiling Now Available in XProf”. Most GPU kernel tutorials treat optimization as a black art. Performance engineering isn't just about reducing FLOPs. Acme AI is the next-generation, AI-powered spreadsheet platform built to replace Excel and redefine how analysts, data scientists, and enterprise teams work… The list below is every profiling story on Beyond Market Intelligence, newest first.
From naive GEMM to FlashAttention: a free code-first GPU kernel series
Most GPU kernel tutorials treat optimization as a black art. This series opens it up. The insight that performance is a data-movement problem first, compute second, reframes everything. Building FlashAttention from scratch, where tiling avoids writing the full attention matrix to memory, is a perfect worked example. The 44-session roadmap covers GEMM through Hopper architecture, with live profiling at every step. If you write production kernels, this is the kind of resource worth contributing feedback to.
A free guide to making ML models faster, from silicon to agents
Performance engineering isn't just about reducing FLOPs. Usamah Zakir spent months writing the guide he wished he'd had when starting out: *How to Make Your Model Fast*. It moves from silicon to agents, using roofline analysis to help you diagnose whether you're compute, bandwidth, or memory bound before optimizing. That systems-first thinking is rare and valuable. The whole thing is free and open source. If you're working on inference or edge AI, it's worth exploring.
Unlock Deeper TPU Insights: Cycle-Level Profiling Now Available in XProf
For developers wrestling with TPU workloads, opaque blocks in trace captures have long been a frustration. Google's addition of a Kernel Profiling suite to XProf changes that. This open-source profiler now exposes cycle-level details for custom Pallas kernels, turning what was once a black box into a map of precise execution paths. It's a practical step toward finer-tuned performance work. Claudio Masolo's report is worth your attention, especially if you're already exploring how AI tools reshape developer workflows.
When AI ships faster, performance demands smarter systems.
Shipping code faster creates a different kind of bottleneck. Martin Spier's talk on keeping ChatGPT fast reveals a truth many overlook: agentic workflows multiply change volume, and that pressure lands squarely on performance. It's not just about GPUs. The hidden costs of rapid deployment demand constant vigilance. Spier's approach, using always-on AI agents to automate profiling and regression detection, is a practical answer to a systemic problem. It's a smart, grounded strategy.
Explore How Android Studio Quail 2 Empowers Parallel AI Conversations
Android Studio's Quail 2 release is stable now, and it brings a meaningful upgrade: parallel AI conversations inside the IDE. That's a practical step toward making Gemini feel like a true coding partner rather than a one-off assistant. The enhanced debugging and profiling tools also deserve attention, as they target real workflow friction. If you're curious about the human side of AI interactions, our piece "Talking to My AI Clone Taught Me to Question the Tech" offers a thoughtful counterpoint worth exploring.
Why Your AI Model Slows 170x on a T4 vs A100
A 170x slowdown between a T4 and an A100 is not a generational gap; it's a signal that something structural is off. For a point-tracking model with dense 4D correlation volumes and transformer layers in pure FP32, you're likely hitting the T4's lack of Tensor Core support for your exact ops, forcing a fallback to inefficient kernels. But that alone shouldn't explain the magnitude. Profile kernel-level timing first. Look for operations like `grid_sample` or `einsum` that might be serializing on the T4's memory bandwidth.
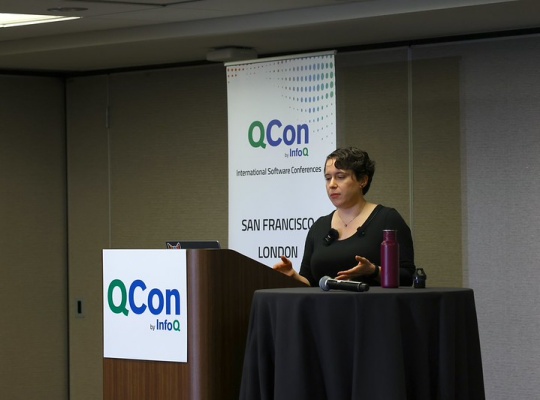
How Rust's compile-time safety reshaped our thinking on delivery speed
Rust's borrow checker often gets framed as a barrier, but Ruth Linehan's talk flips that assumption. She shows how migrating high-performance caching services from Kotlin to Rust actually shortens the developer feedback loop, turning compile-time safety into a daily advantage. It's a practical look at how the language reshapes delivery velocity, not just runtime performance. For those exploring how modern infrastructure choices ripple outward, this pairs well with our coverage of Perplexity's move to CobbleDB.