RAG pipelines
Beyond Market Intelligence keeps RAG pipelines in one place: 3 stories so far. The section currently leads with “Explore how memt-1.0 bakes memory into AI computation for massive storage savings”, “Building Smarter RAG Pipelines That Earn Their Complexity”, and “When Every Passage Holds the Answer, RAG Needs a New Shape”. Building long-horizon agents that don't drown in context windows? Most teams add complexity to RAG pipelines before they've earned it. Acme AI is the next-generation, AI-powered spreadsheet platform built to replace Excel and redefine how analysts, data scientists, and enterprise teams work… The list below is every RAG pipelines story on Beyond Market Intelligence, newest first.

Explore how memt-1.0 bakes memory into AI computation for massive storage savings
Building long-horizon agents that don't drown in context windows? That's the promise of memt-1.0, which bakes memory directly into AI computation rather than stacking prompts or bolting on external RAG. The engineering tradeoffs here are genuinely fascinating. By internalizing procedural experience into model weights via gated deltanet-2 and a mixture-of-storage layer, they achieve a 66x storage reduction at 128k context. For teams wrestling with kv cache bottlenecks, this architecture-level approach feels like a genuine path forward.
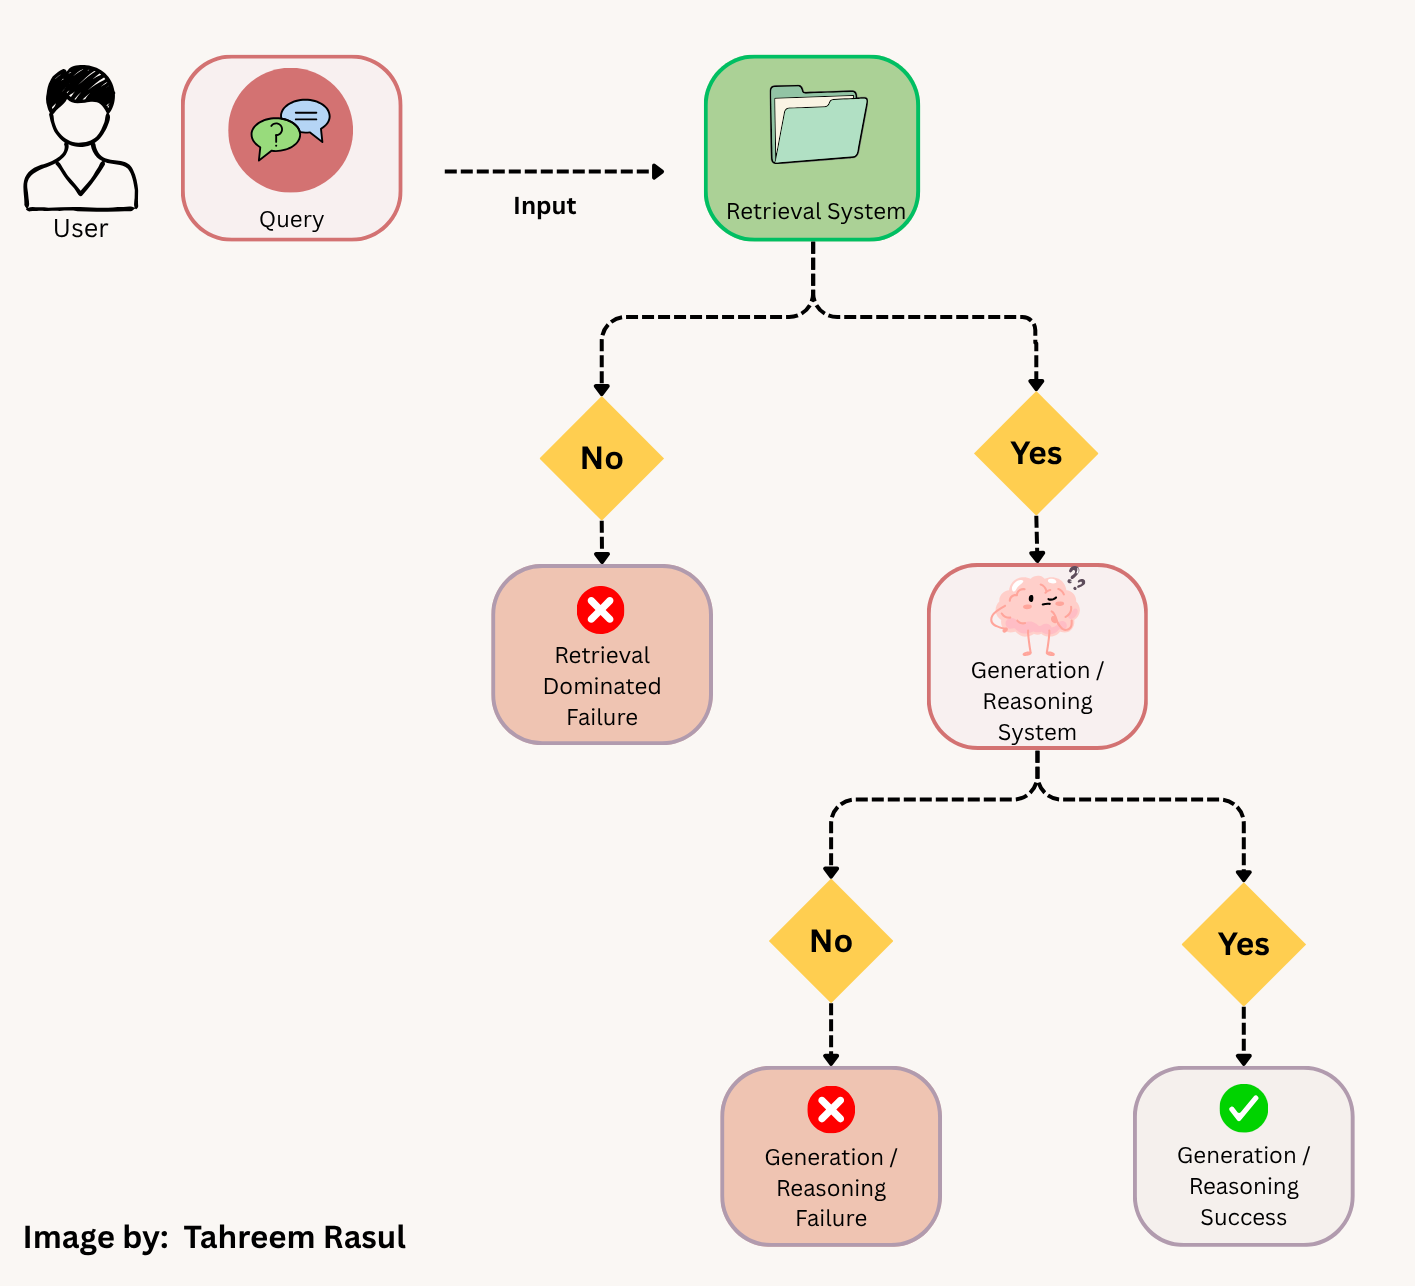
Building Smarter RAG Pipelines That Earn Their Complexity
Most teams add complexity to RAG pipelines before they've earned it. This framework flips that instinct, introducing advanced techniques only when observed failures demand them. Starting with lexical and hybrid search, then moving to reranking and agentic information seeking, the approach keeps systems lean and understandable. It's a disciplined counter to the temptation of overbuilding. For readers tracking how retrieval evolves into action, the related piece on bridging retrieval and action offers a useful follow-up.

When Every Passage Holds the Answer, RAG Needs a New Shape
Most RAG pipelines retrieve a single top passage and call it a day. But some questions don't work that way. Listing questions demand every relevant passage, not just the highest-scoring one. This pipeline walks through that silent failure point and the pipeline shape that actually handles it. It's a practical look at a real limitation, and the reasoning is clear. For readers who want to go deeper, "Exploring Paragraph Structure: How LLMs Navigate Token Space" offers a useful follow-up on how token coordinates shape retrieval.