regression testing
3 stories filed under regression testing on Beyond Market Intelligence. The newest of them: “Beyond Green: Understanding True Test Suite Efficacy”, “How One Capital Letter Can Break Your AI Support Bot”, and “Astra and Fable 5.1: A practical look at AI spreadsheet tradeoffs”. A green test suite can create a false sense of security. A single uppercase letter can quietly break an AI support bot, and the culprit wasn't the new model. Acme AI is the next-generation, AI-powered spreadsheet platform built to replace Excel and redefine how analysts, data scientists, and enterprise teams work… The list below is every regression testing story on Beyond Market Intelligence, newest first.
Beyond Green: Understanding True Test Suite Efficacy
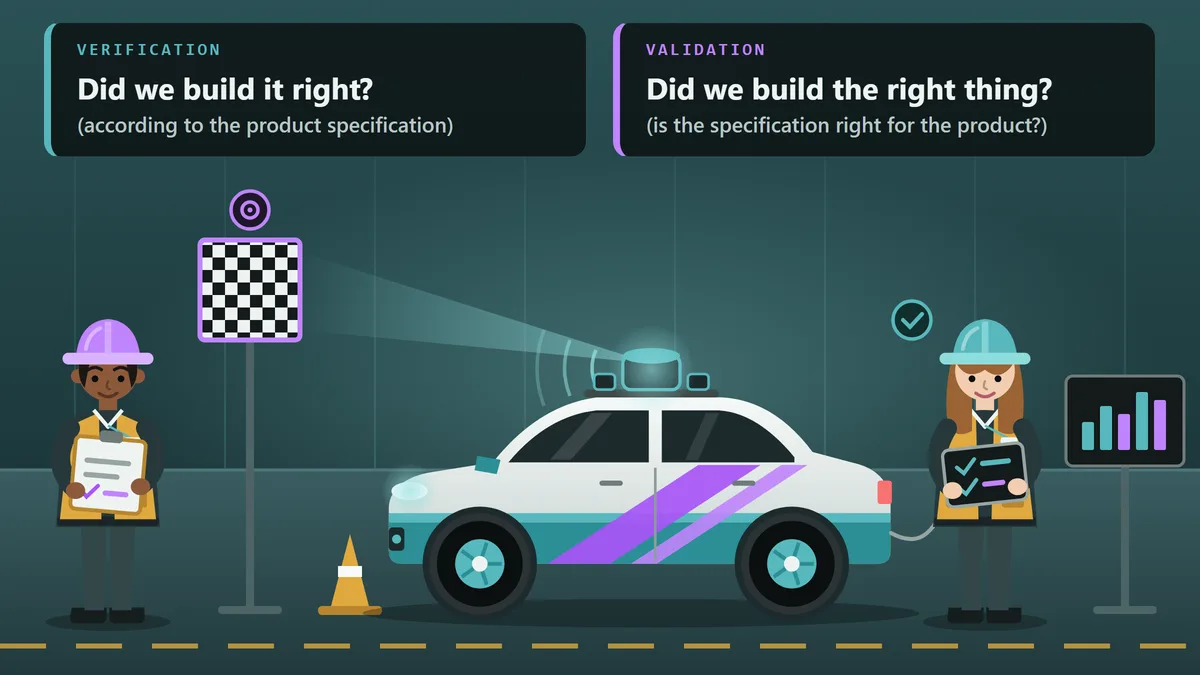
A green test suite can create a false sense of security. Passing tests don't always mean your software is healthy, and that gap deserves attention. This piece challenges you to look beyond the color of the results and ask what your tests are truly verifying. It's a practical call to focus on efficacy, not just outcomes. If you're ready to rethink your approach to automation, this is the right starting point.
How One Capital Letter Can Break Your AI Support Bot
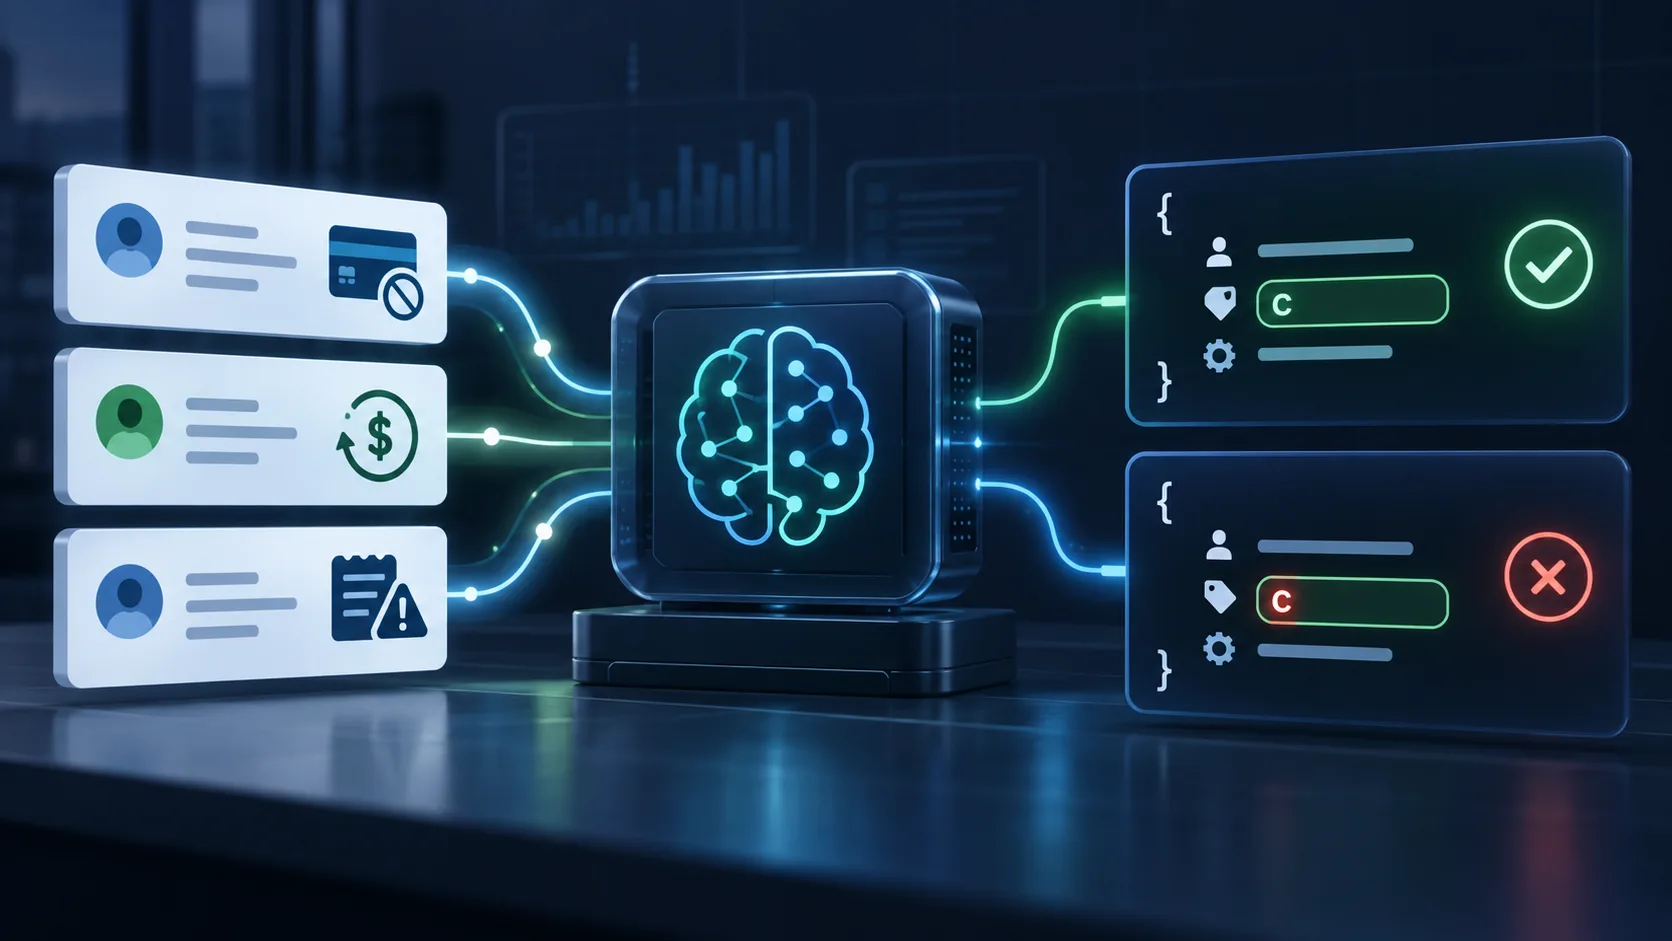
A single uppercase letter can quietly break an AI support bot, and the culprit wasn't the new model. This real Weave project regression-tests three OpenAI models against the exact reply format your app depends on. It's a sharp reminder that precision matters more than model size. If you're building on these tools, this is the kind of detail worth verifying early. For a related angle, our piece "Verify Your AI's Understanding: A Simple Check for Tax Season" offers a practical parallel.
Astra and Fable 5.1: A practical look at AI spreadsheet tradeoffs
Two very capable models can still fail differently. In a side-by-side ML workflow, Astra and Fable 5.1 both improved by 0.02-0.04 F1 after human feedback, proving neither has mastered the process. Astra wins on agentic debugging and reproducibility, while Fable writes cleaner code and more insightful analysis. The real lesson? Pick your tool based on whether you need forensic rigor or readable, adaptable output. For deeper context on model tradeoffs, our related piece, "Explore the Forrester Function," explores similar evaluation themes.