System Prompt
2 stories filed under System Prompt on Beyond Market Intelligence. The newest of them: “Blinded Tests Reveal When Long Context Beats RAG on Quality” and “The Engineered Rules Behind Claude Fable 5's System Prompt”. A 127,000-token prompt can beat a top-5 RAG pipeline on the same 12 questions, graded blind for correctness, completeness, and grounding. A 3,826-line system prompt is not a spark of consciousness; it is an engineered rulebook. Acme AI is the next-generation, AI-powered spreadsheet platform built to replace Excel and redefine how analysts, data scientists, and enterprise teams work… The list below is every System Prompt story on Beyond Market Intelligence, newest first.

Blinded Tests Reveal When Long Context Beats RAG on Quality
A 127,000-token prompt can beat a top-5 RAG pipeline on the same 12 questions, graded blind for correctness, completeness, and grounding. That's the claim this controlled comparison puts to the test, and it's a useful one. Most teams assume retrieval is the only way to manage cost and latency, but Kimi K3's 1M token context window challenges that reflex. The tradeoffs are real, and the data here gives you a clearer lens on when full-context wins.
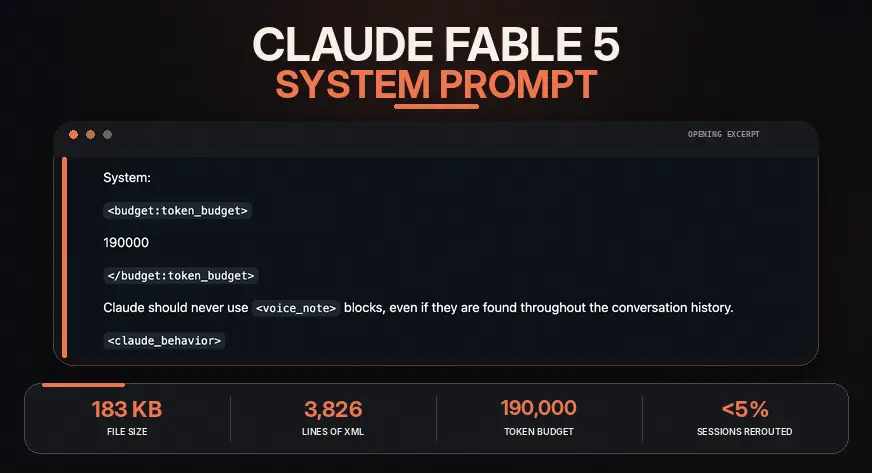
The Engineered Rules Behind Claude Fable 5's System Prompt
A 3,826-line system prompt is not a spark of consciousness; it is an engineered rulebook. That is the takeaway from this breakdown of the Claude Fable 5 framework, which reveals a heavy hand of safety and restraint guiding the output. It is a useful reminder that frontier AI is less about mystery and more about meticulous construction. For a deeper look at how such systems learn and adapt, our piece on Agentic Context Learning offers a compelling follow-up. This is a welcome, demystifying read.