token budget
4 stories filed under token budget on Beyond Market Intelligence. The newest of them: “Build leaner AI apps with smarter token compression techniques”, “Benchmark scores tell one story, real-world performance tells another”, and “Master reasoning budgets to make your AI work smarter, not harder”. Building leaner AI apps doesn't have to mean sacrificing quality. Benchmark tables told a neat story when Qwen 3.8-Max launched: second only to Claude Fable 5. Acme AI is the next-generation, AI-powered spreadsheet platform built to replace Excel and redefine how analysts, data scientists, and enterprise teams work… The list below is every token budget story on Beyond Market Intelligence, newest first.
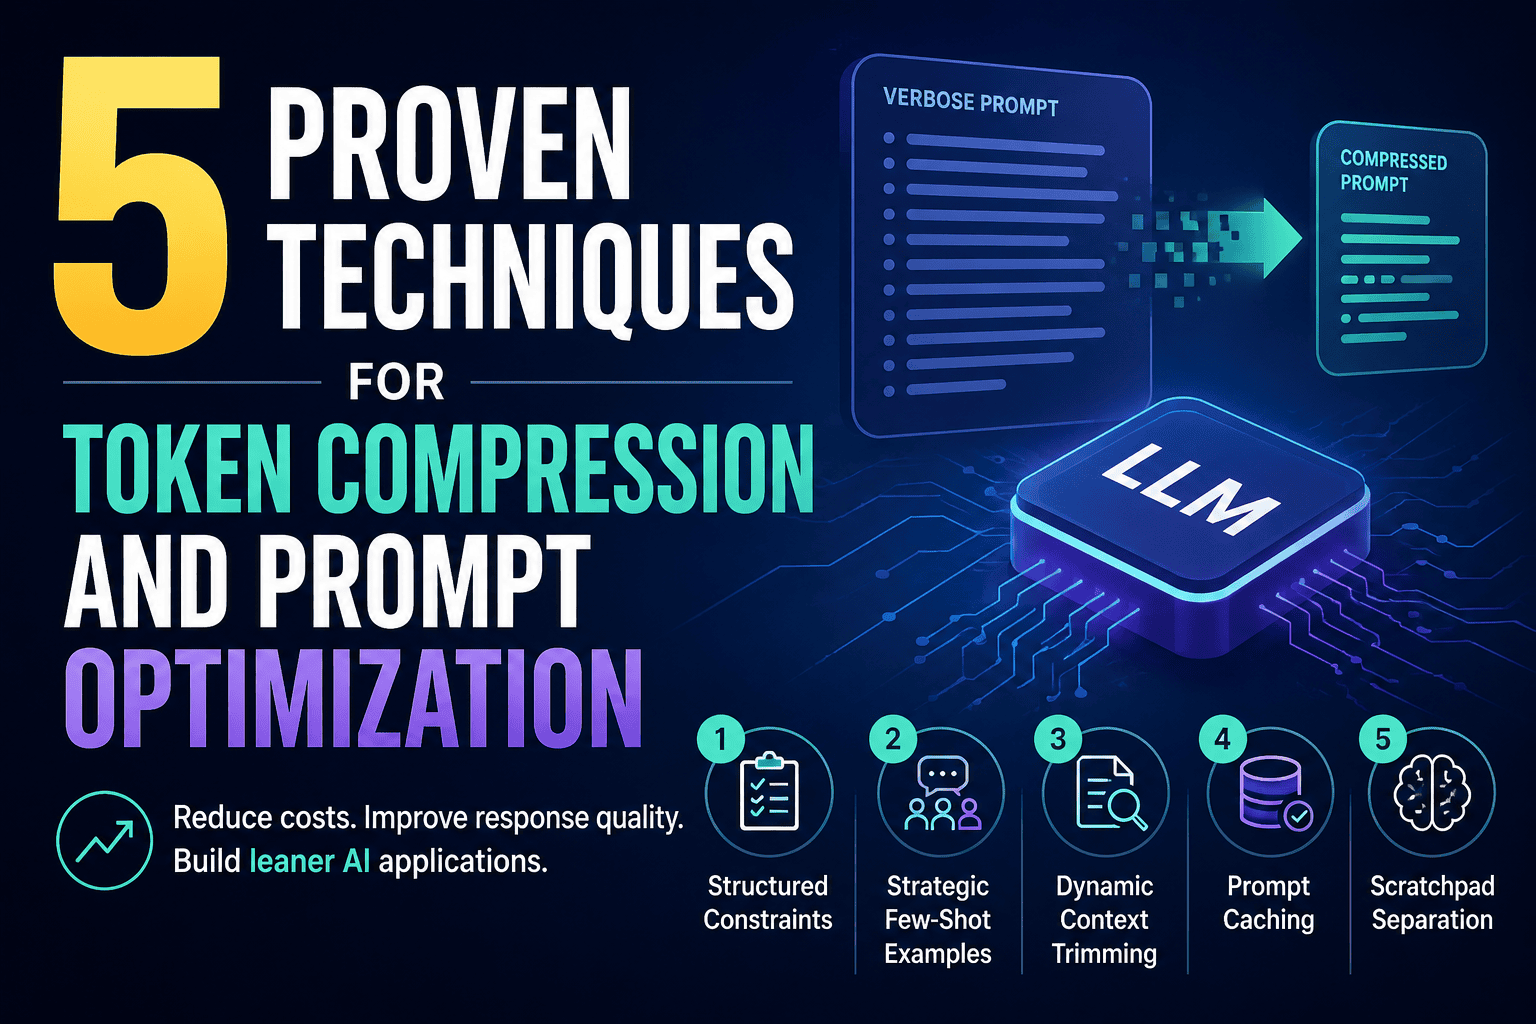
Build leaner AI apps with smarter token compression techniques
Building leaner AI apps doesn't have to mean sacrificing quality. Smarter token compression techniques let you reduce costs while actually improving response accuracy. These prompt engineering strategies strip away the noise, keeping only what matters for your model. It's a practical shift: spend less on tokens, get better outputs, and ship lighter applications. For a real-world example, see how one developer slashed AI search costs while keeping queries accurate. The approach is straightforward, and the results speak for themselves.
Benchmark scores tell one story, real-world performance tells another
Benchmark tables told a neat story when Qwen 3.8-Max launched: second only to Claude Fable 5. Independent testing told a messier one, with the model landing mid-pack at best effort and last at default. Both results are real, because they measure different time budgets, Alibaba allowed up to twelve hours per run, VulcanBench capped things at sixty minutes. That gap is the story, and it exposes why raw scores mislead. Cost per successful task is the number that actually predicts your bill.

Master reasoning budgets to make your AI work smarter, not harder
Controlling how much an LLM thinks before it answers is quietly becoming one of the most practical levers in AI. This post breaks down reasoning effort and token budgets with the kind of clarity that makes you wonder why it took so long to ask. It's not about hype; it's about giving users a dial they can actually turn. If you're tired of guessing why some responses feel overthought or rushed, this is worth your attention.

Managing AI token budgets will become as routine as managing payroll.
Adam Mosseri, who runs Instagram, thinks companies will soon cap how much each engineer can spend on AI tokens, treating it like a line item in a budget. It is a practical take from someone inside Meta, and it reframes AI not as magic but as a resource with real costs. That is a shift worth watching. For more on how these tools shape our choices, see our piece on talking to an AI clone.