variance
5 stories filed under variance on Beyond Market Intelligence. The newest of them: “Designing marketplace experiments means choosing between clean data and real impact”, “Why Your Forecast Gets the Future Right and Still Fails”, and “Simplify complex gradients by shifting randomness outside the computation graph”. When designing marketplace experiments, you're often choosing between clean data and real impact. A forecast can nail the mean and the variance and still describe a future that never happens. Acme AI is the next-generation, AI-powered spreadsheet platform built to replace Excel and redefine how analysts, data scientists, and enterprise teams work… The list below is every variance story on Beyond Market Intelligence, newest first.

Designing marketplace experiments means choosing between clean data and real impact
When designing marketplace experiments, you're often choosing between clean data and real impact. The metrics that matter most, like revenue or contribution margin, have far more variance than simple conversion rates, making them harder to power. Running a geo experiment longer helps less than expected when weekly bookings within regions are correlated. You can accept more uncertainty, apply variance reduction techniques like CUPED, or power on lower-variance metrics while bounding assumptions.
Why Your Forecast Gets the Future Right and Still Fails
A forecast can nail the mean and the variance and still describe a future that never happens. That is the paradox this piece tackles head-on, introducing a diffusion head for probabilistic time series forecasting that fixes the gap between statistical accuracy and real-world outcomes. It is a sharp, necessary correction for anyone who trusts their MSE a little too much. For a related look at how models can mislead, explore our coverage of why Gemini Argon tops charts but skips the test that counts.
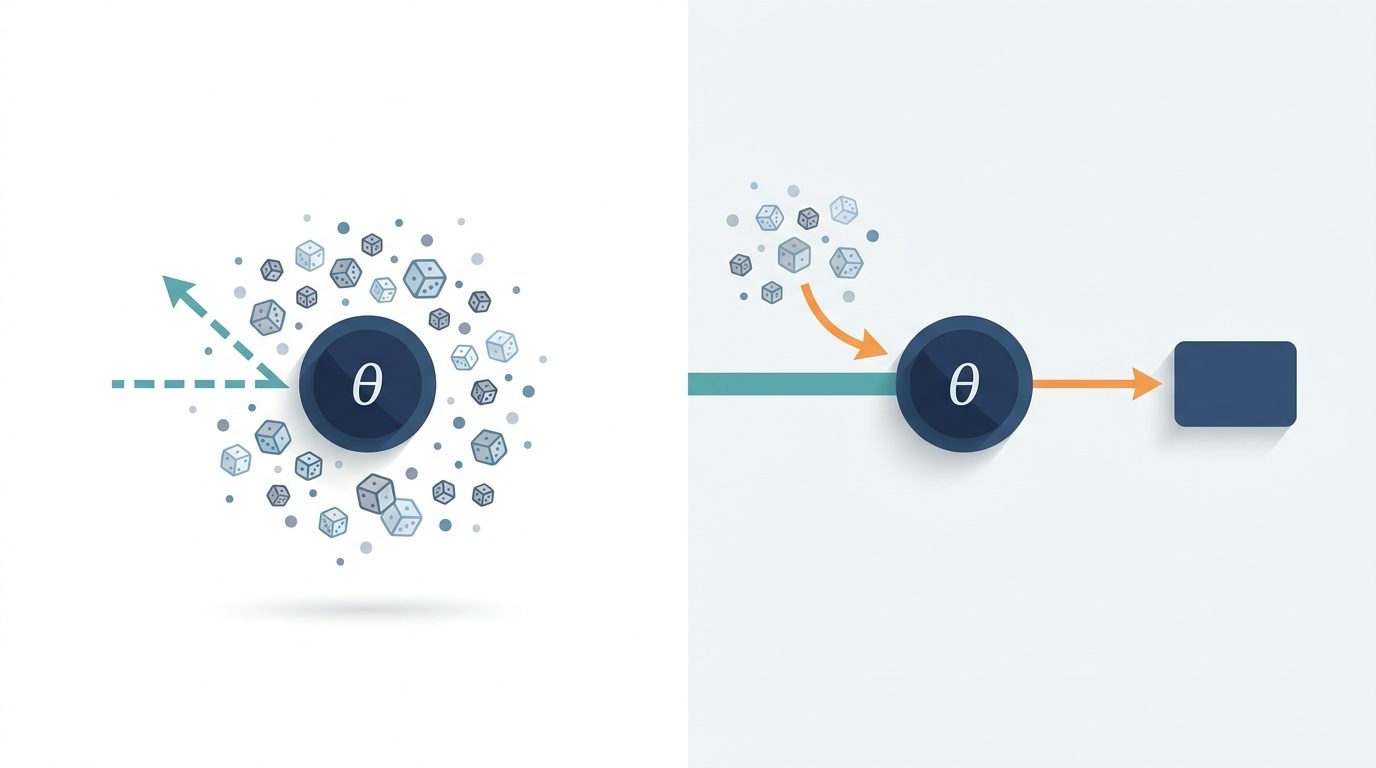
Simplify complex gradients by shifting randomness outside the computation graph
Noisy gradients are the price of sampling inside the computation graph. Moving randomness outside the computation graph changes everything. By reparameterizing, you keep the model differentiable while trimming variance that slows training. It is a practical, accessible breakdown of a technique that feels abstract until you see it applied. If you are exploring how to make your own models more stable, this is worth your time. For another angle on practical ML, our piece on real-world computer vision deployments pairs well here.
The Equation That Reveals Bagging's Limits and Why Randomness Matters
Bagging has a ceiling, and no amount of trees will break it. The equation explains why random forests need that extra layer of chaos to keep improving. It's a sharp reminder that more isn't always better when the mechanism stalls. The experiment makes the point concrete, turning theory into something you can see. If distributed systems intrigue you, *Unlock LLM Training* pairs well with this mindset, though it stands firmly on its own.
Theory guided machine learning: A practice worth rediscovering.
The gap between machine learning theory and practice has never been wider, and the confusion is understandable. Many of the field's most famous guidelines, like avoiding overfitting or trusting only certain optimizers, started as narrow mathematical results but became rigid folklore. We now know breaking these rules often works better, yet no one formally retracts the old lessons. This leaves practitioners questioning whether any theoretical guidance still holds, or if empirical trial-and-error is the only honest approach.