causal inference
Beyond Market Intelligence keeps causal inference in one place: 10 stories so far. The section currently leads with “How to Spot the 4 Case Study Types in Data Science Interviews”, “Choosing the Right Causal Model When Truth Is Unseen”, and “Answering the Unanswerable: Real-World Lessons in Causal Inference”. Case study rounds used to mean marketplace experimentation. Causal inference models carry a hidden risk: you can never see the true effect, yet you still have to pick one. Acme AI is the next-generation, AI-powered spreadsheet platform built to replace Excel and redefine how analysts, data scientists, and enterprise teams work… The list below is every causal inference story on Beyond Market Intelligence, newest first.

How to Spot the 4 Case Study Types in Data Science Interviews
Case study rounds used to mean marketplace experimentation. After 80+ interviews across 16 companies, the picture is broader. You might face a launch evaluation, a root cause analysis, an opportunity sizing decision, or a targeting problem built on heterogeneous treatment effects. Spotting which of the four you are facing matters because each demands a distinct approach. The included maps break down the opening, the test, and the trap.
Choosing the Right Causal Model When Truth Is Unseen
Causal inference models carry a hidden risk: you can never see the true effect, yet you still have to pick one. This simulation makes that tension concrete. Difference-in-differences overestimated a 10% impact by more than double, while synthetic control landed far closer. The fix isn't a better algorithm, it's a placebo test. Running an A/A check on pre-treatment data exposes which model carries the least error before you trust it in the wild. That workflow, not any single method, is the durable lesson.
Answering the Unanswerable: Real-World Lessons in Causal Inference
Causal inference answers questions that feel impossible: what would have happened otherwise? This blog makes that abstract field concrete by walking through real-world examples where the methods actually solved problems. For newcomers, the clarity is the point. The examples do the teaching, turning tricky concepts into something you can grasp and apply. If you are exploring how AI reshapes data workflows, this is a natural next stop. Happy reading.
When you shift marketing spend, does your MMM finally tell the truth?
A shift in marketing spend timing can expose an MMM's blind spots, because the model only learns from data that never held the right answers. Testing when you spend, not just how much, reveals whether the model can finally tell the truth. It is a practical challenge to a tool many trust too easily. For deeper coverage on AI-driven analysis, see "Beyond the Search Box: Defining Real Research in AutoResearch."
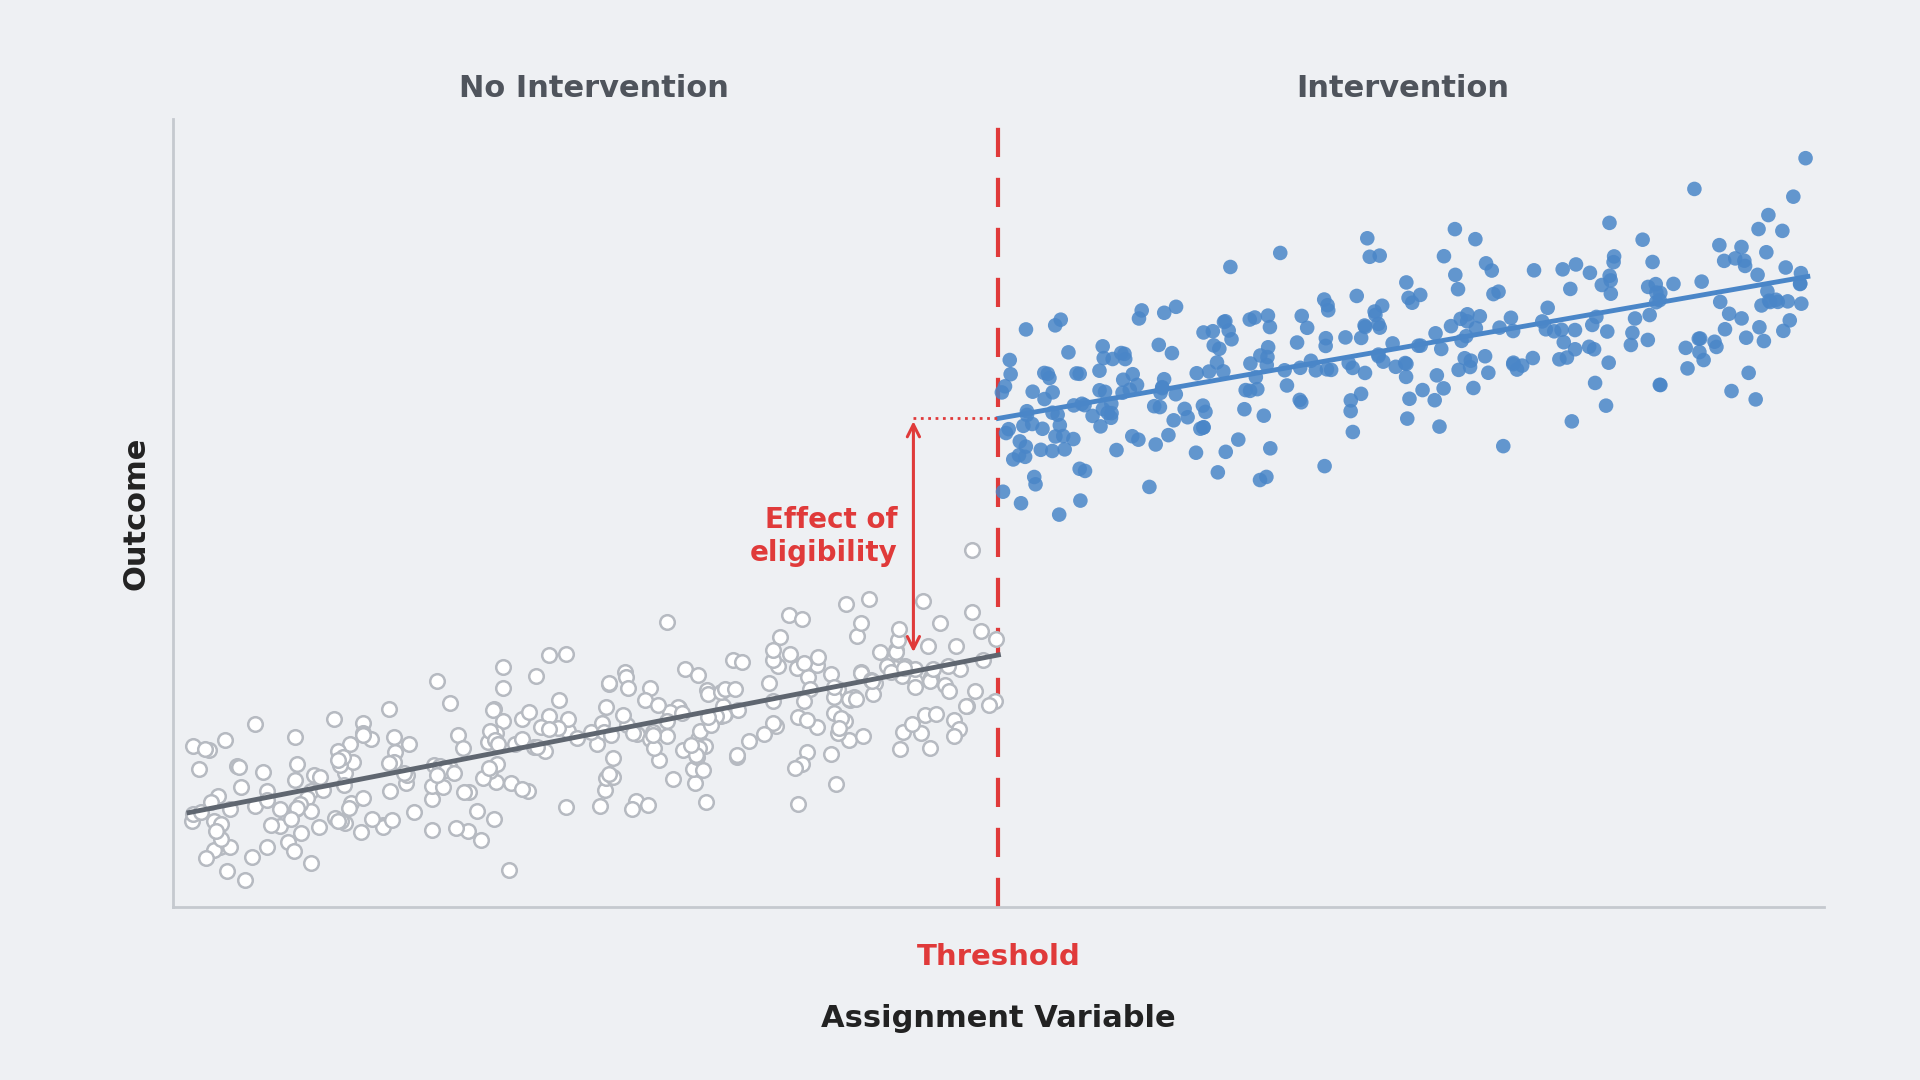
See Through the Hype of Your AI Feature's Adoption Numbers
When a team opts into an AI feature, the lift you measure isn't just the tool's effect. It's a selection effect, a reflection of who chose to engage. This guide offers a practical framework for estimating what that opt-in feature actually did, even without randomization. It's a sharp, honest look at a messy problem. For practitioners ready to dig deeper into the mechanics of modern AI systems, our guide to distributed algorithms pairs well with this mindset.
Discover how causal attribution solves delayed penalty problems in constrained RL.
Standard constrained RL assumes consequences are immediate and attributable to the current action. That assumption frays the moment violations arrive late and stochastically, leaving you penalizing whatever action happened to precede the observed harm rather than the one that caused it. CCPL tackles this head-on with a delay-corrected Bellman operator and an Interventional Consequence Net for causal attribution. The contraction proof holding under unknown stochastic delay is solid. The real constraint is the ICN's dependence on structural-causal-model labels, a practical limit worth acknowledging.
Explore how Netflix's open-source agent simplifies causal analysis workflows.
Netflix has open-sourced an agentic workflow for Observational Causal Inference that cuts through the usual grind of causal analysis. Given your data and a clear plan, the agent runs an actor-critic loop to estimate causality, draft a report, and point to next steps. It's a practical move toward making complex inference less manual. If you're exploring how agents handle structured tasks, our guide to distributed algorithms offers a useful foundation. This is the kind of tool that turns ambition into action.
Why causal inference was missing from NeurIPS workshops this year
Seventy-three workshops at NeurIPS, and causality doesn't get a single slot. That stings, especially for those of us who've watched the field push real boundaries at UAI and CLeaR. It's not that those venues lack merit; they're excellent. But the energy at the top conferences has clearly pivoted toward LLMs and agents, leaving causal inference on the periphery. We're not saying the work vanished, just that its visibility is shrinking. For researchers who value rigorous, human-centered data science, this feels like a quiet loss.
From Academia to Impact: Translating Public Health Expertise into Industry
Four years in academia, with publications in JAMA Open and experience in doubly robust methods, gives you a real analytical foundation. That is not the problem. The gap is likely in how you are framing your transition. You are studying SQL and probability, which is good, but you need to show how your causal inference work solves business problems. Frame your research as applied decision-making. Also, revisit that tech internship network; it is your strongest asset.

Why Prediction Alone Fails to Uncover True Causal Effects
A model that predicts an outcome with high accuracy can still mislead you on treatment effects. That is the uncomfortable truth this piece tackles. The issue is variable selection: predictive models chase correlation, not causation, so they often drop confounders that matter for estimating impact. Bayesian Adjustment for Confounding offers a more principled path forward. It is a technical fix, but the lesson is practical. If your data strategy is off, even the smartest model will lead you astray.