continuous evaluation
Beyond Market Intelligence keeps continuous evaluation in one place: 5 stories so far. The section currently leads with “Agentic AI Demands Smarter Governance to Tame Silent Failures”, “LLM Benchmarks Show Surprising Daily Performance Fluctuations”, and “From Policy to Practice: Microsoft's Blueprint for AI Governance in Action”. Agentic AI systems don't fail loudly, they drift silently. A single hourly LLM benchmark score can mislead you. Acme AI is the next-generation, AI-powered spreadsheet platform built to replace Excel and redefine how analysts, data scientists, and enterprise teams work… The list below is every continuous evaluation story on Beyond Market Intelligence, newest first.
Agentic AI Demands Smarter Governance to Tame Silent Failures
Agentic AI systems don't fail loudly, they drift silently. A recent InfoQ webinar highlighted how semantic and embedding drift can quietly produce costly errors. The solution demands smarter governance, not just better models. Automated code reviews, continuous model evaluation, and stronger privacy measures were called essential. This is a strategic challenge, not a technical patch. For a deeper look at keeping AI systems adaptable over time, see our related piece, "Design for Change: Keep Software Evolvable as Teams and Technology Shift."

LLM Benchmarks Show Surprising Daily Performance Fluctuations
A single hourly LLM benchmark score can mislead you. After analyzing 31,352 hourly scores, the data shows within-day variation sits at 2.8 points, while between-day variation jumps to 8.4 points. That threefold gap matters. It means isolated movements mostly reflect normal model randomness, but sustained daily shifts reveal true performance drift. This is the missing observability layer for production AI. You cannot manage what you only sample once. Continuous evaluation, like the system built here, turns noisy data into actionable signals.
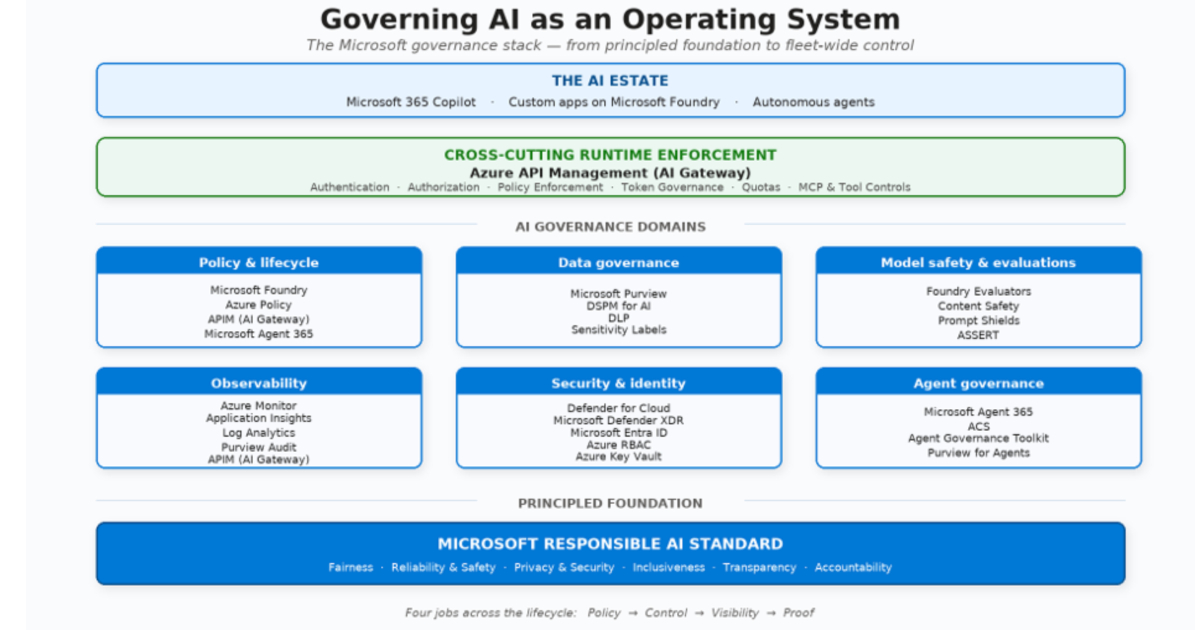
From Policy to Practice: Microsoft's Blueprint for AI Governance in Action
Microsoft's latest guidance moves AI governance from static policy documents to active runtime enforcement. By mapping nine governance domains across policy, control, visibility, and proof, the company connects intent with live execution. That matters because production AI demands continuous evaluation, not just upfront checks. It's a practical step toward verifiable accountability, and it pairs well with our coverage of observability in testing, like Grafana's approach to monitoring Cypress suites. Governance is becoming operational, and that's a shift worth watching closely.
Waymo's real test begins after the model works
Waymo's evaluation-first approach is the discipline most AI teams are missing. Before any model earns a deployment, its tests must prove maturity, not just performance. That standard, enforced through continuous evaluation and human oversight, is what has carried the company to 220 million rider-only miles with dramatically fewer serious injuries. For enterprises, the lesson is direct: if you cannot measure an agent's edge cases, you are not ready to trust it in production.

Continuous Evaluation Keeps Your RAG Systems Reliable and User-Ready
A production RAG system isn't a set-and-forget deployment. It's a living thing, and like any living thing, it drifts. That's why this practical guide focuses on building an evaluation workflow that catches retrieval failures, hallucinations, and performance drift before they ever reach your users. It's about moving from hoping your system works to knowing it does. For those ready to go deeper into the underlying mechanics, our guide on distributed training offers a solid foundation. But start here, where trust is built continuously.