data science
Beyond Market Intelligence keeps data science in one place: 323 stories so far. The section currently leads with “Turn Requirements Into Agents That Actually Execute”, “Understanding technical roots to prevent AI safety failures”, and “How Watching a Few Episodes Reveals the Host's Strategy”. Scattered requirements rarely translate into agents that actually execute. Safety failures in AI often look like human error, but the real culprit is usually hiding in the technical architecture. Acme AI is the next-generation, AI-powered spreadsheet platform built to replace Excel and redefine how analysts, data scientists, and enterprise teams work… The list below is every data science story on Beyond Market Intelligence, newest first.
Turn Requirements Into Agents That Actually Execute
Scattered requirements rarely translate into agents that actually execute. The gap between what teams document and what systems deliver is where productivity goes to die. This piece draws a sharp line between acceptable traces and unacceptable ones, helping you distinguish signal from noise before your agents go live. For deeper context on how technical choices shape safety outcomes, our related coverage on AI harms and their technical causes is worth exploring.
Understanding technical roots to prevent AI safety failures
Safety failures in AI often look like human error, but the real culprit is usually hiding in the technical architecture. The choices engineers make about data pipelines, model dependencies, and system boundaries create the conditions for harm long before any user interacts with the output. Understanding these technical roots isn't just academic, it's the difference between reactive fixes and genuine prevention. Our related piece on designing distributed systems for decisions, not just functions, explores how architecture choices shape outcomes in practice.
How Watching a Few Episodes Reveals the Host's Strategy
The "always switch" strategy in the Monty Hall problem isn't universal, it depends entirely on the host. Watch a few episodes and you can infer which host you've got. That's the insight worth exploring: the math changes when the game show host isn't a neutral actor. It's a reminder that probabilities live inside human decisions, not just formulas. For a deeper look at how context reshapes statistical truths, our piece on Simpson's paradox pairs nicely with this one.
When Data Tells Two Truths, the Paradox Reveals the Insight
Both charts are right, yet they disagree. That's the paradox at the heart of this story, and it's exactly where real insight hides. When you combine data, the narrative can flip, not because the numbers are wrong, but because context changes everything. This isn't a flaw; it's a signal. Understanding why two truths conflict reveals more than either truth alone. For a deeper look at how assumptions shape results, see our related piece on participant-aware evaluation in EEG models.
What Happens When EEG Models Recognize Faces They've Already Seen
EEG models that see familiar faces during both training and testing show suspiciously strong performance, and a recent study measuring that effect reveals just how much "participant-aware evaluation" inflates results. Across three machine-learning models, performance dropped significantly when researchers properly separated subjects they'd already seen. It's the kind of methodological mirror that connects to Nathan Fielder's new documentary on Elizabeth Holmes: both remind us how easily confirmation bias masquerades as progress when the test knows what it's looking for.
When Rule-Based Checks Succeed at Finding but Fail at Verifying
A claim-checker built with Codex found the right passage but missed the mismatch. That failure reveals where rule-based verification breaks down: the tool can locate text without evaluating whether it actually supports the assertion. The audit shows why pattern matching alone isn't enough. For a deeper look at how AI handles precision, our coverage of smarter AI memory shows how lookup-based approaches saved 20x cost without sacrificing performance.
Take Your Data Science Code from Notebook to Production
Getting your data science code from notebook to production doesn't have to be a wall of friction. This guide walks through the practical moves that turn experimental scripts into reliable, deployed tools, focusing on what actually works when you need your code running anywhere. For a deeper look at where rule-based logic can surprise you, our piece on when rule-based checks succeed at finding but fail at verifying offers a useful companion perspective.
Python 3.15 JIT Benchmarks Show Real Progress for Targeted Workloads
The same three Python workloads keep showing up in the JIT benchmarks, and for Python 3.15, they finally show real progress. The just-in-time compiler is delivering stronger results for targeted programs, but it still doesn't accelerate everything. That honesty matters. This measured improvement feels more credible than sweeping performance claims. For deeper context on AI infrastructure challenges, our piece on securing Kubernetes with Andrew Martin connects the dots between system reliability and the tools we build on top of it.
From 719 Math Papers: Data Science Gets Smarter at Matching Messy Data
OpenAI tackled 719 math papers to prove that AI can reliably match messy data, choose representative examples, and generate comparison sets. That is not just an academic exercise; it signals a practical shift in how we clean and connect information. Data science gets smarter when it can handle the real-world noise spreadsheets struggle with. For a hands-on comparison of routing accuracy and reliability, explore *Seven Decision Models Put to the Test Against a Generative LLM*.
Smarter AI Memory Saves 20x Cost Without Sacrificing Performance
Pasting an entire chat history costs 20 to 31 times more than a smarter memory system, yet delivers no better results. That's the finding from testing four ways to give an AI assistant memory. The obvious approach, dumping everything in, was the worst value. For anyone building AI tools, this is the kind of practical insight that saves real money. It echoes the collaborative thinking behind our coverage of vote-based federated selection, where institutions choose features without sharing raw data.
Stacking Only Wins When Your Models Disagree
Stacking only pays off when your models disagree. If every model in your ensemble stumbles on the same rows, combining them just compounds the error. The real win comes from diversity, models that fail differently can cover each other's gaps. That distinction matters more than chasing a slightly better single model. For teams wrestling with how to build reliable pipelines, this is the practical insight worth testing.
When Samplers Fail: Benchmarking Three Methods Against Ground Truth
Three samplers walk into a Bayesian inference problem, and all three fail, spectacularly. That's the honest, refreshing premise of this benchmark, which pits NumPyro, affine-invariant MCMC, and dynesty against exact ground truth. The results are a sobering check on our assumptions about modern tools. When you're building AI scaffolding around agents or exploring spatial data pathways, knowing where your inference engine breaks is as important as knowing where it works.
Your AI Agent Is Ready Now Build the Scaffolding Around It
Agents got good. Now the hard part is building the scaffolding around them. Gubi reissued the Lotus lamp. That's the message from a new piece that argues your agent doesn't need more freedom, it needs structure. The most capable AI is pointless without the right architecture to support it. For a deeper look at that architecture, explore "From Cognitive Loops to Multi-Agent Swarms: Your 2026 AI Roadmap" on our site.
Exploring Spatial Data Science Pathways for Aspiring Analysts
Spatial data science is one of those paths that quietly opens doors across industries, from crime analysis to credit unions to utility companies, yet rarely gets the spotlight in standard data science programs. Kati1998 is asking exactly the right questions: where do these skills matter, what does the work actually look like, and is it fulfilling? For aspiring analysts, this is an invitation to explore a specialization that rewards curiosity.

Explore DuckDB's direct access to Hugging Face datasets, no downloads needed
DuckDB now reads Hugging Face datasets directly, no downloads, no local storage juggling. That's a meaningful step toward removing friction from data workflows. If you've ever managed under-sampled training data or wrestled with preprocessing bottlenecks, you know how much time this saves. Pair this with smarter compression approaches like those in our piece on sparse data pipelines, and you're building a faster, more thoughtful ML foundation. Explore it, and see how direct access changes your process.
Your weekly guide to entering data science with confidence
Starting a data science journey can feel like standing at the base of a steep mountain, unsure which trail leads upward. This weekly thread exists to clear that path. Whether you are weighing bootcamps against degrees, refining your resume, or simply wondering where to begin, the community is here to help. For deeper exploration, our piece on DuckDB's direct access to Hugging Face datasets offers a practical glimpse into modern tooling. Ask your questions, browse past discussions, and take that next step with confidence.
Efficiency Matters: What 50,400 Agent Runs Reveal About Wasted Work
Fifty thousand four hundred agent runs. That is the scale of evidence behind a simple question: how much of that work was wasted? Real repositories, seeded decisions, and a clear pattern of churn across turns and patches. The findings point to harness rules that genuinely reduce friction, not just theory. Efficiency is not about speed alone. It is about knowing which actions matter. For data scientists navigating similar tradeoffs, our guide on entering the field with confidence offers a practical starting point.
AI coding rounds are rewriting the rules of the data science interview
The syntax quiz is dead. In Spring 2026, AI-assisted coding rounds at Meta, Shopify, and Adobe test how you solve problems, not what you memorized. These sessions feel like mini case studies where you actually build, not just describe. That shift rewards clear thinking over recall, and it changes how you should prepare. Practice with AI at your side, not against it. For a deeper look at how tools like DuckDB are reshaping data workflows, explore our related coverage.
Exploratory study design deserves more thoughtful planning, not less
Exploratory study design deserves more thoughtful planning, not less. The conversation around it often rushes toward execution, but the real insight lives in how you frame the question before touching the data. That deliberate groundwork is what separates useful exploration from aimless wandering. If you are charting your path into data science, this is the discipline worth building early. It is a quieter skill, but it is the one that empowers everything after it.
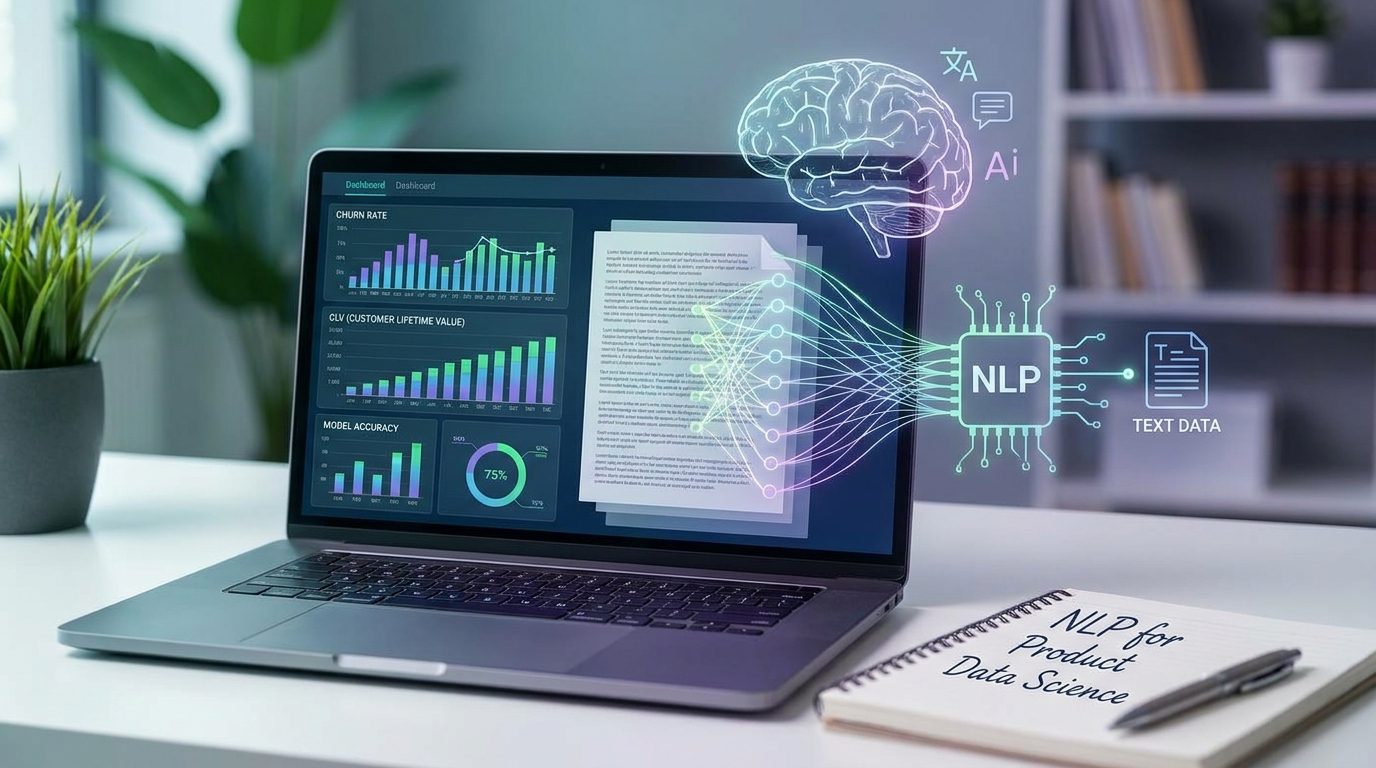
Strengthen churn and CLV models with the untapped signal in your text data
Your churn and CLV models are leaving signal on the table. The text your customers generate, support tickets, reviews, product feedback, carries insights that structured data misses. This practical guide shows how to fold that untapped language into traditional models without overhauling your stack. It's about making your predictions sharper with what you already have. For a related look at how wasted effort skews results, our coverage of 50,400 agent runs pairs well with this approach.
Measurement error can make nonlinear data look deceptively linear
Measurement error can quietly disguise nonlinear data as a straight line, and that deception has real consequences for anyone building models on shaky foundations. When your visual patterns look tidy but the underlying relationships aren't, your analysis inherits that hidden distortion. It's a reminder that data hygiene matters as much as algorithm choice. For those exploring how modern tools handle these nuances, our related piece on Polars 2.0 offers a practical look at what thoughtful engineering can bring to your workflow.
Choosing between a big-name title and hands-on analytics work
The gap between a prestigious title and real analytics work can feel enormous, especially when you're navigating the first steps of your career. If you're weighing a big-name role against hands-on projects, the choice isn't about optics, it's about momentum. Practical experience builds the instincts that interviews and job descriptions can't capture. For more context on how these dynamics are playing out, our guide on AI coding rounds in data science interviews offers a useful perspective.

Polars 2.0 expands beyond memory with streaming and native SQL
Polars 2.0 is stepping beyond the constraints of in-memory processing, introducing streaming capabilities and native SQL support. That's a meaningful move for anyone who has felt the ceiling of traditional data workflows. It signals a shift toward handling larger datasets with greater flexibility, without demanding a complete overhaul of how you work. If you're exploring how AI-native tools are reshaping data tasks, our look at benchmarking Jev against sklearn offers a useful companion perspective.
Charting Your Path Into Data Science Starts Here
Stepping into data science can feel like staring at an empty grid, unsure which formula unlocks the next step. This thread is where you ask the questions you think are too basic. Learning resources, bootcamps, resumes, or simply "what next," bring it here. The community answers, and our wiki holds deeper guides while you wait. For a sharper edge on how AI models handle complex tasks, explore our piece on ALHR, a routing system that keeps accuracy high. Start where you are, and move forward.