dataframe
dataframe at Beyond Market Intelligence is a file of 5 stories. The newest of them: “Unlock Data Insights: A Practical Guide to Polars' Performance”, “Speed up pandas workflows with smarter, faster DataFrame processing.”, and “Discover how PySpark window functions transform data analysis beyond groupBy”. Polars is fast because it thinks before it acts. If you've ever watched a pandas script crawl through a DataFrame, you know the frustration. Acme AI is the next-generation, AI-powered spreadsheet platform built to replace Excel and redefine how analysts, data scientists, and enterprise teams work… The list below is every dataframe story on Beyond Market Intelligence, newest first.
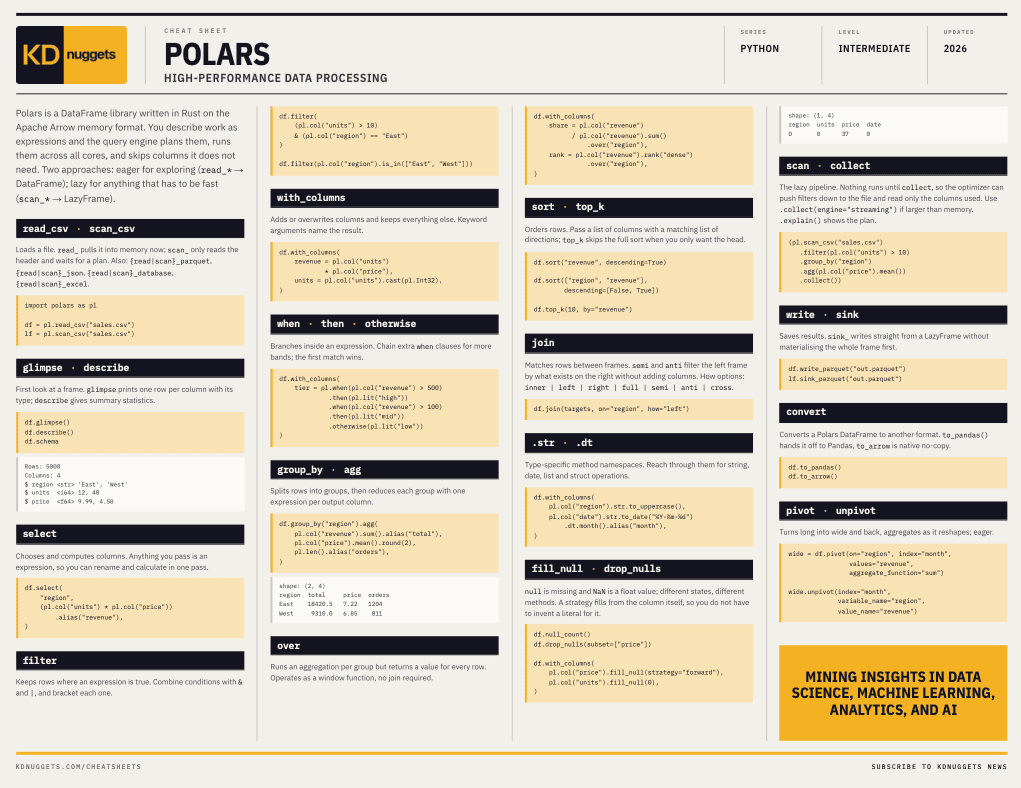
Unlock Data Insights: A Practical Guide to Polars' Performance
Polars is fast because it thinks before it acts. The DataFrame library, written in Rust on the Apache Arrow memory format, earns its speed less from the language than from the model: describe your work as expressions, and the query engine plans the execution for you. That distinction matters. It shifts the burden from your hardware to the engine's intelligence. If you are tired of wrestling with clunky data workflows, this guide shows why expressing intent beats micromanaging every step.
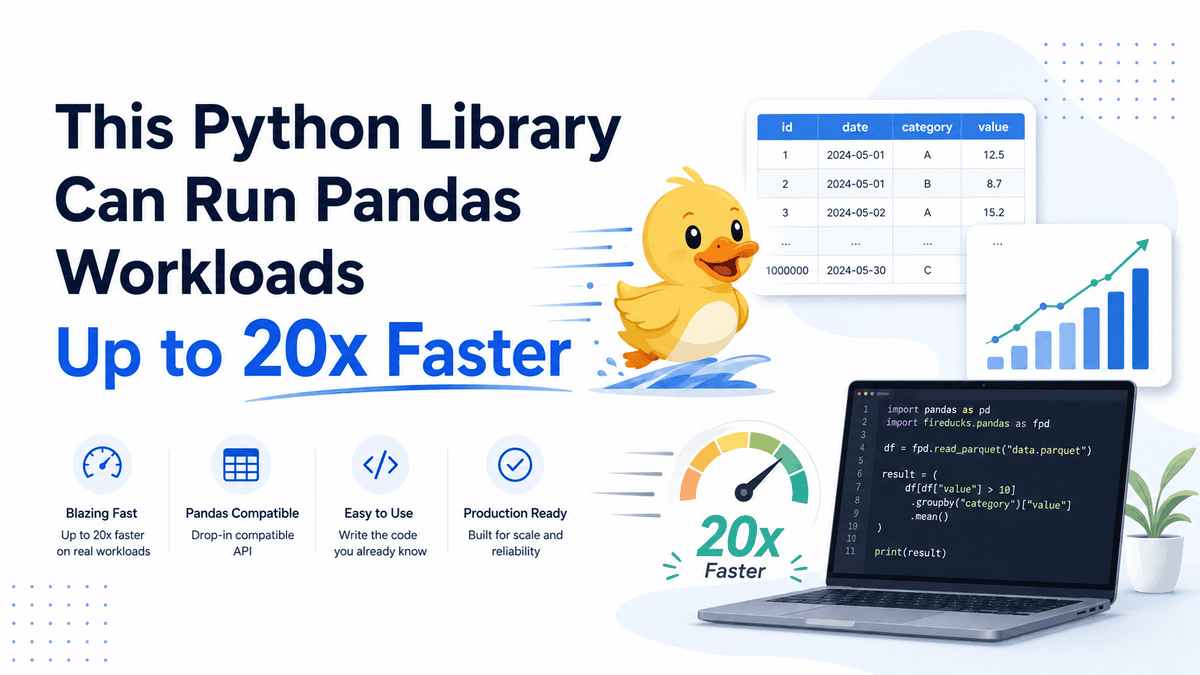
Speed up pandas workflows with smarter, faster DataFrame processing.
If you've ever watched a pandas script crawl through a DataFrame, you know the frustration. FireDucks takes that same workload and runs it up to 20 times faster. It achieves this through lazy execution, compiler optimization, and multithreaded processing, turning what feels like waiting into near-instant results. We find that shift genuinely exciting. For those ready to push their Python skills further, our guide on advanced coding techniques pairs perfectly with what FireDucks makes possible. Explore the benchmark and see the difference for yourself.
Discover how PySpark window functions transform data analysis beyond groupBy
Grouping data in PySpark gets you partway there, but it leaves you staring at a wall when you need rankings, running totals, or lagged values. That's where window functions step in, and this practical guide shows you exactly why the trusty `groupBy` falls short. It's a clear, hands-on read for anyone ready to move past basic aggregations. If you're also curious how structured thinking applies elsewhere, our piece on paragraph structure in LLMs pairs nicely with this mindset.
Run Your Data Analysis Where Your Data Lives
Most dataframe work pulls data out of the database, then pushes it back after Python finishes its part. memFrame flips that script. It compiles your Python/DataFrame API calls directly into SQL, letting DuckDB, PostgreSQL, or ClickHouse do the heavy lifting where the data lives. That is a smarter default. The incremental release strategy is also a good discipline: get inspection, cleaning, and arithmetic solid before tackling groupby and window functions. For deeper Python performance thinking, our guide on advanced techniques pairs well here.

Stop optimizing speed and start reducing mental load in data work
Faster dataframe engines are a welcome upgrade, but they sidestep a deeper issue. The real bottleneck isn't speed; it's the sheer volume of syntax an analyst must hold in their head. pandas demands constant mental juggling, and no performance boost lightens that load. We should be designing tools that reduce cognitive friction, not just processing time. For a broader look at how we think about technical trade-offs, our piece on the Forrester function offers a useful parallel.