inference cost
4 stories filed under inference cost on Beyond Market Intelligence. The newest of them: “One transformer model replaced 15 specialized generators in Yandex Music's A/B test”, “Build leaner AI apps with smarter token compression techniques”, and “Smart Caching: Optimizing LLM Performance and Reducing Costs”. One transformer replaced 15 specialized generators in Yandex Music's production stack. Building leaner AI apps doesn't have to mean sacrificing quality. Acme AI is the next-generation, AI-powered spreadsheet platform built to replace Excel and redefine how analysts, data scientists, and enterprise teams work… The list below is every inference cost story on Beyond Market Intelligence, newest first.
One transformer model replaced 15 specialized generators in Yandex Music's A/B test
One transformer replaced 15 specialized generators in Yandex Music's production stack. That's the kind of result that makes you rethink how we build recommenders. Sona, their single-model generative recommender, achieved a +4.53% lift in Active Users and +6.30% in Total Listening Time on smart speakers. History Compression cuts inference cost roughly in half while retaining most of the quality. For deeper context on how models manage long contexts efficiently, see our article on smarter token compression techniques.
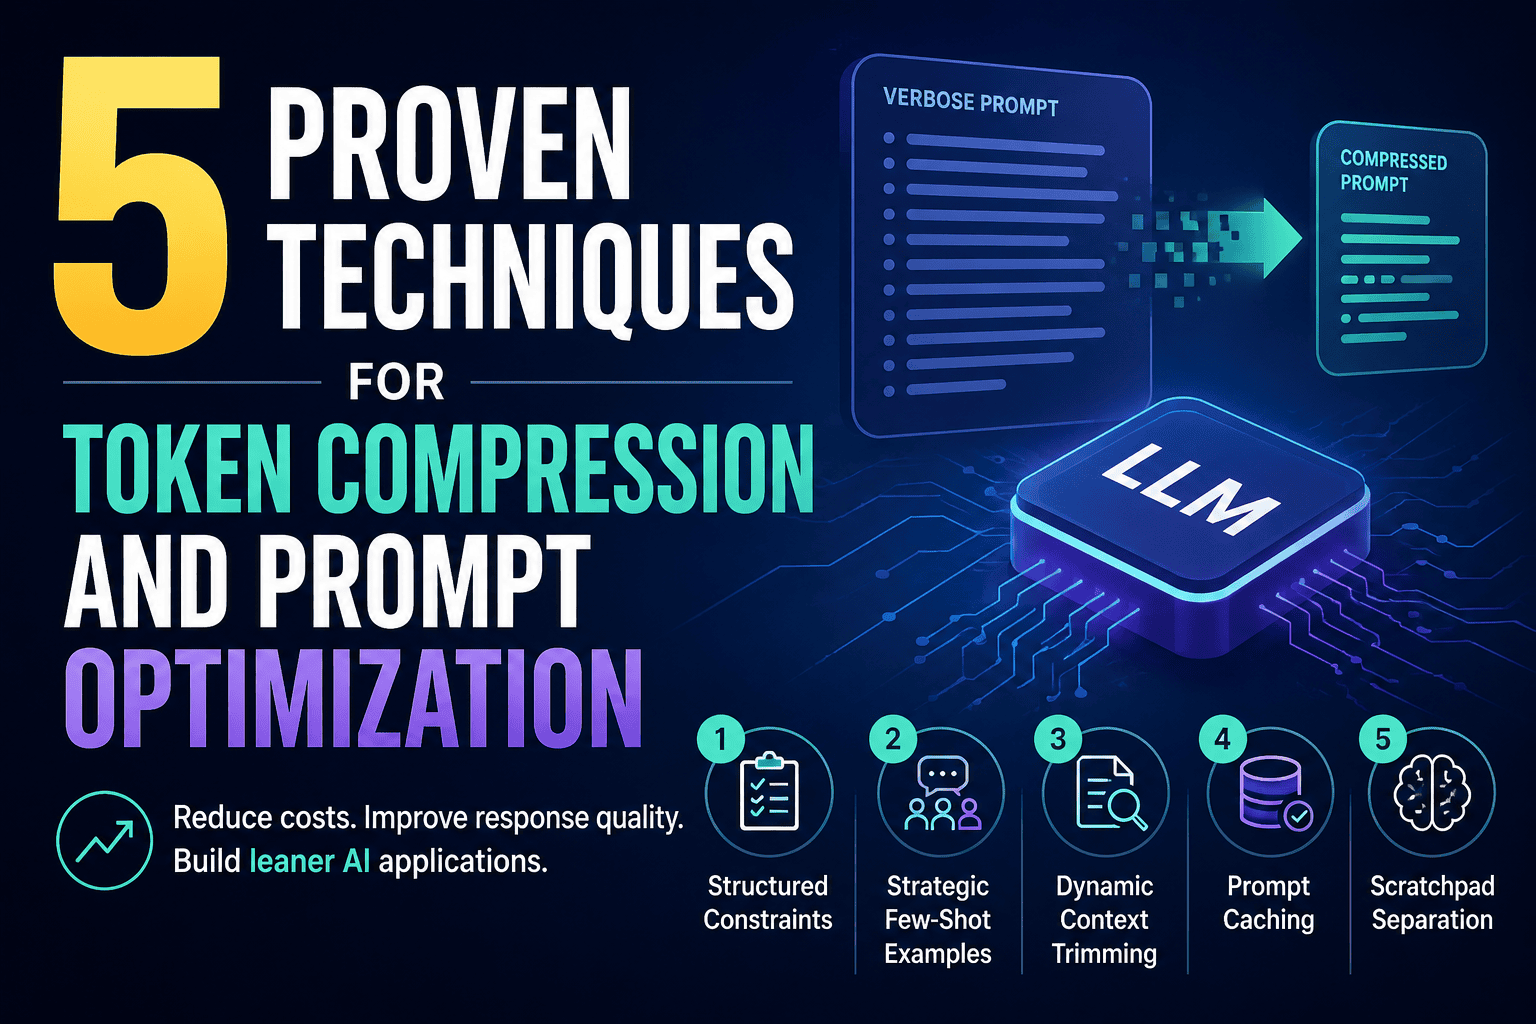
Build leaner AI apps with smarter token compression techniques
Building leaner AI apps doesn't have to mean sacrificing quality. Smarter token compression techniques let you reduce costs while actually improving response accuracy. These prompt engineering strategies strip away the noise, keeping only what matters for your model. It's a practical shift: spend less on tokens, get better outputs, and ship lighter applications. For a real-world example, see how one developer slashed AI search costs while keeping queries accurate. The approach is straightforward, and the results speak for themselves.
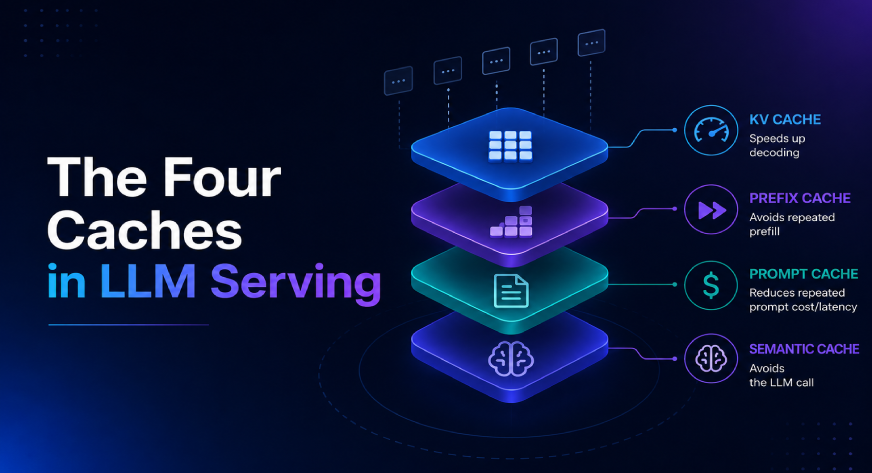
Smart Caching: Optimizing LLM Performance and Reducing Costs
Every request your LLM handles may carry millions of tokens, yet much of that data repeats across calls. Reprocessing it wastes time and drives up compute costs. Smart caching targets exactly this waste, and the new piece breaks down the four cache layers that make serving faster and cheaper. It's a practical read for anyone tired of paying twice for the same work. For a deeper look at distributed systems, our guide to distributed algorithms pairs well with this one.
Shopify's Gisting Technique Compresses AI Prompts for Faster Inference
Shopify's engineering team has introduced gisting, a technique that compresses long LLM prompts into a smaller set of learned tokens. The result? Better throughput and lower inference costs without sacrificing performance. That's a practical step toward making AI more accessible, especially for teams wrestling with unwieldy system prompts. We see this as a meaningful move for developers who want efficiency without complexity.