markdown
12 stories filed under markdown on Beyond Market Intelligence. The newest of them: “Keep Your Data Science Notebooks Running: Six Essential Habits”, “Cut Through the ML Paper Clutter with AI-Powered Research.”, and “Reduce Search Result Tokens by 74% with Smarter Data Structuring”. A notebook that runs perfectly on your screen can fall apart the moment you close the laptop. Reading papers as they drop sounds noble until you're drowning in arXiv alerts and can't tell a novel method from a rehash. Acme AI is the next-generation, AI-powered spreadsheet platform built to replace Excel and redefine how analysts, data scientists, and enterprise teams work… The list below is every markdown story on Beyond Market Intelligence, newest first.
Keep Your Data Science Notebooks Running: Six Essential Habits
A notebook that runs perfectly on your screen can fall apart the moment you close the laptop. That frustrating reality is exactly what these six essential habits address. They are not about writing fancier code, but about building a workflow that survives interruptions and returns you to your work with confidence. We appreciate the practical focus on resilience. For another perspective on keeping complex work sustainable, you might explore our related article, "Expanding Your Tech Fluency: Key Insights Beyond Artificial Intelligence.

Cut Through the ML Paper Clutter with AI-Powered Research.
Reading papers as they drop sounds noble until you're drowning in arXiv alerts and can't tell a novel method from a rehash. This developer felt that pain and built an AI agent to handle the grunt work: filtering, deduping, ranking against your interests, and producing a structured report in English and Portuguese. It's refreshingly practical. The scheduler is a smart touch, too. For anyone tired of the research grind, this feels less like another tool and more like a relief.
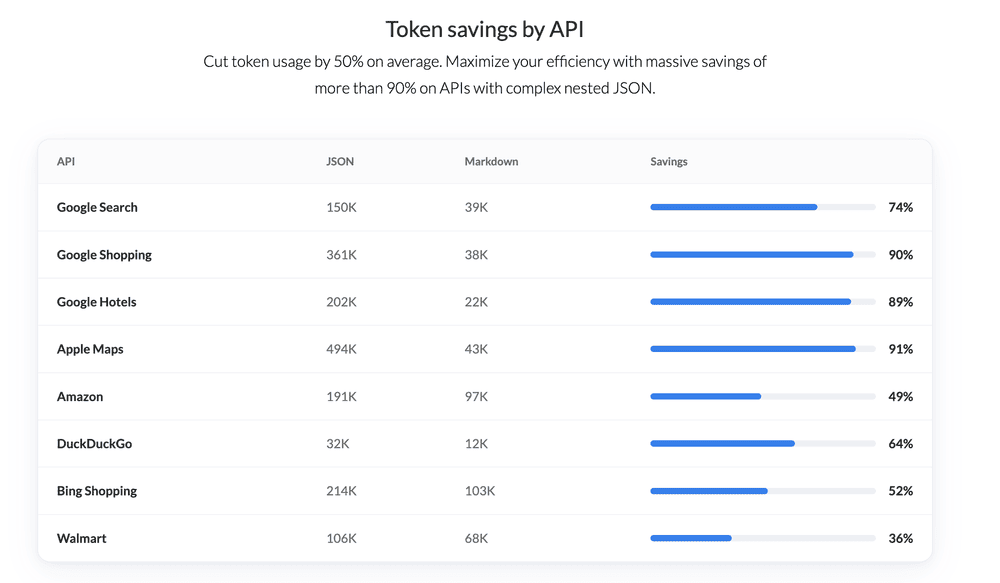
Reduce Search Result Tokens by 74% with Smarter Data Structuring
A single search result can quietly consume thousands of tokens, and that weight adds up fast when you're paying for every call. SerpApi's Markdown output tackles this directly, trimming usage by up to 74% by stripping away the noise and keeping only what matters. That's a meaningful reduction in context-window overhead and agent costs. It's the kind of practical efficiency that pairs well with the broader optimization thinking in our guide to distributed training.
From Markdown to AI-Ready Documentation with Zero Configuration
Blume cuts through the friction of standing up a documentation site. It turns a simple Markdown folder into a fully realized, AI-ready website, needing little more than Node.js and a single file to start. Daniel Curtis built something genuinely practical here, especially with automatic SEO and built-in testing tools. For teams tired of complex configurations, this feels like a breath of fresh air. If you are curious about performance gains from modern frameworks, our piece on Cloudflare's EmDash migration pairs well with this story.
Parse 5 brings structure to complex documents with precision and clarity
Extracting structured data from complex PDFs has long been a bottleneck for teams drowning in visual documents. Cohere's Parse 5 takes a direct swing at that problem, using a 2.3-billion-parameter multimodal model to turn rich pages into Markdown while keeping spatial context through bounding boxes. Scoring 79.2 across over 2,000 enterprise pages, it's a solid, practical step forward. We're watching this space closely, especially alongside our look at retrieval benchmarking in "Measure Embedding Relevance: A New Approach to Retrieval Benchmarking."
Enterprise data extraction meets its cost-performance sweet spot
Most document parsers force enterprises to choose between accuracy and affordability. Cohere's Parse 5 doesn't dodge that trade-off; it prices it honestly. At $1.50 per 1,000 pages, it trails frontier models like GPT-5.5 on raw scores but slashes costs by over 98 percent in high-volume workflows. That's a practical bet on structure preservation, not benchmark glory. For teams feeding millions of documents into AI pipelines, the real question isn't who wins parse tests, but what survives downstream.
Explore how Astro's Sätteri transforms build speed with Rust-powered Markdown.
Astro's new Sätteri processor is worth paying attention to if you've felt the drag of slower builds. Built in Rust, it speeds up Markdown and MDX processing by up to 61% for Astro 7.0, which is a meaningful leap for teams juggling content-heavy sites. What stands out is its balance: flexible JavaScript plugins and native Markdown features, all while staying compatible with the unified ecosystem. It's a practical step forward, not hype.
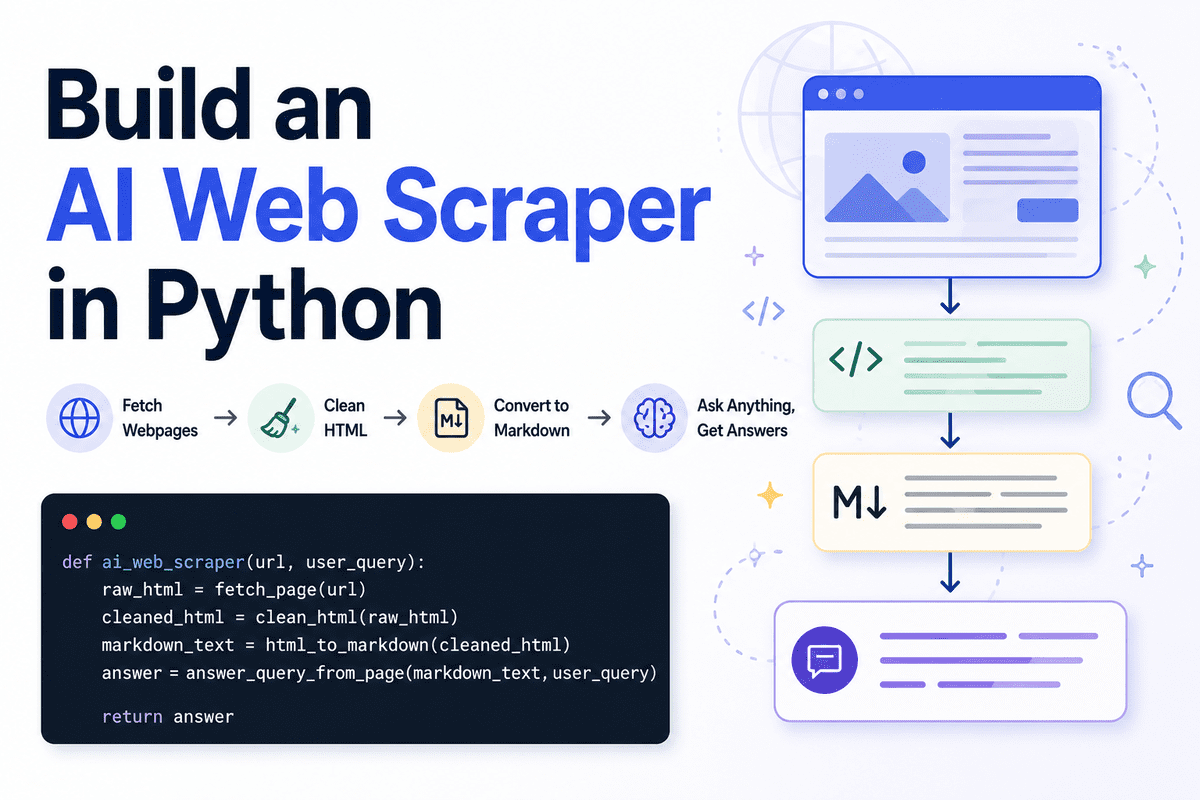
Turn Web Pages into Smart Q&A Engines with AI
Most tutorials make web scraping sound harder than it needs to be. This one strips away the noise: clean the HTML, convert it to Markdown, and let an LLM answer focused questions. The payoff is real, especially when you want answers without burning through tokens on messy page structures. It's a practical, no-nonsense approach that respects your time and your budget. If you're tired of wrestling with raw scraped data, this method feels like a quiet win.

OKF enables 30% faster LLM handoffs with a simple safety check
Sending pre-tokenized integer arrays between three Qwen2.5-Coder models sounds like a niche task, but it's exactly where OKF's Markdown+YAML skeleton earns its keep. The Markdown+YAML skeleton doesn't just explain the format; it demonstrates a practical agent-to-agent hand-off that cuts TTFT by 28 to 37 percent. What stands out is the discipline: one full-vocabulary equivalence check keeps the entire exchange safe. If you're exploring structured knowledge sharing, this walkthrough feels like a solid next step.
Astro 7 delivers faster builds with native Rust tooling and smarter processing.
Astro 7 is built for speed, and the numbers show it: builds up to 61% faster thanks to a rewritten Rust compiler and native tooling. Markdown processing gets a significant boost, while stricter HTML rules keep output clean. It's a thoughtful push for content-driven sites that want less JavaScript overhead. We've seen this pattern before with Perplexity's CobbleDB migration, and the focus on performance over flash feels right. If you're wrestling with slow builds, this is worth exploring.
Move Beyond Begging for Valid JSON with Constraint Decoding
If you're tired of begging your model to "output valid JSON without including any markdown," this guide is for you. Practical constraint decoding takes the guesswork out of formatting, turning a frustrating negotiation into a reliable, repeatable process. It's a straightforward approach that puts control back in your hands. We think it's an essential read for anyone building on AI. For more ways to keep your work smooth, check out "Keep Your Data Science Notebooks Running: Six Essential Habits" to round out your workflow.
Link figures in your NeurIPS rebuttal without crossing the line
Submitting a rebuttal with figures that reviewers explicitly asked for is the right instinct, but linking them against the rules is a gamble. The community knows OpenReview's limits, and many have quietly shared external links with mixed results. A single violation unlikely sinks a paper, but it signals disregard for protocol. A better path: embed the plots directly in the rebuttal's markdown, or summarize key trends in a table and offer the full figure upon request. That respects the process while keeping your results digestible.