request
4 stories filed under request on Beyond Market Intelligence. The newest of them: “Seeking a Sydney badge for NeurIPS 2026? A Paris swap awaits”, “Unlock New Reasoning Power: A Deep Dive into Claude Opus 5.5”, and “Smart Caching: Optimizing LLM Performance and Reducing Costs”. A Sydney badge for NeurIPS 2026 is out there, but it might come with a Paris detour. Claude Opus 5.5 reasons on every request, responds faster, and costs less to run. Acme AI is the next-generation, AI-powered spreadsheet platform built to replace Excel and redefine how analysts, data scientists, and enterprise teams work… The list below is every request story on Beyond Market Intelligence, newest first.
Seeking a Sydney badge for NeurIPS 2026? A Paris swap awaits
A Sydney badge for NeurIPS 2026 is out there, but it might come with a Paris detour. One attendee assigned to Paris wants to swap with anyone holding a Sydney slot, hoping to trade locations before the conference begins. It's a straightforward request that highlights how flexible conference planning can be. If you're in a similar position, exploring these swaps could simplify your travel. For more on navigating event logistics, check out our coverage of TechCrunch Disrupt 2026.
Unlock New Reasoning Power: A Deep Dive into Claude Opus 5.5
Claude Opus 5.5 reasons on every request, responds faster, and costs less to run. That combination is worth pausing over, because it points to a model designed for practical work rather than just benchmark bragging. Anthropic packed real upgrades into its latest flagship, and the implications for everyday data tasks are significant.
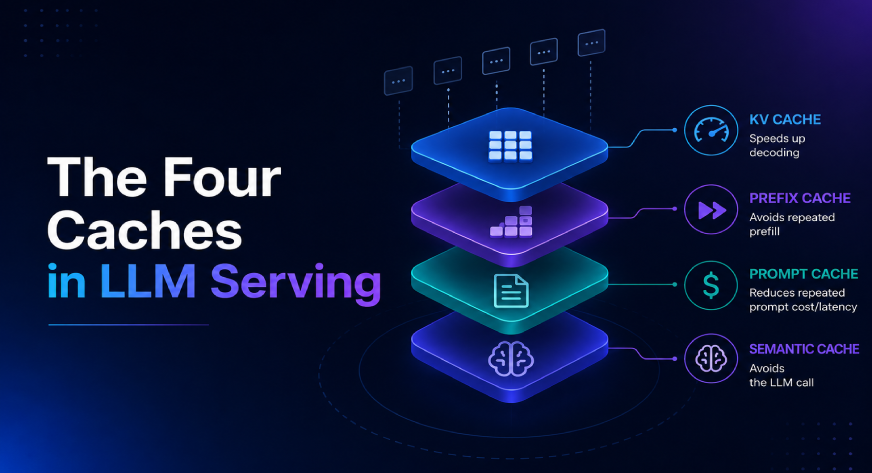
Smart Caching: Optimizing LLM Performance and Reducing Costs
Every request your LLM handles may carry millions of tokens, yet much of that data repeats across calls. Reprocessing it wastes time and drives up compute costs. Smart caching targets exactly this waste, and the new piece breaks down the four cache layers that make serving faster and cheaper. It's a practical read for anyone tired of paying twice for the same work. For a deeper look at distributed systems, our guide to distributed algorithms pairs well with this one.
Stop Wasting Compute: Smarter Ways to Speed Up LLM Inference
Scaling LLMs isn't about adding GPUs. It's about removing wasted work from every request. That distinction shapes our latest guide, which lays out 12 practical ways to cut latency and inference costs without chasing hardware. Each tactic targets the inefficiencies that quietly slow production systems. If you're ready to move past brute-force scaling, this is where you start. For a deeper look at how distributed systems underpin these choices, our guide on unlocking distributed training algorithms pairs well with the conversation.