request batching
Beyond Market Intelligence keeps request batching in one place: 2 stories so far. The section currently leads with “Explore the LLM Frameworks Shaping Smarter Production Deployments” and “Smarter resource use: how batching transforms LLM performance”. Comparing LLM frameworks for production can feel like navigating a maze of technical trade-offs. Four people heading to the same destination in separate taxis make four identical trips. Acme AI is the next-generation, AI-powered spreadsheet platform built to replace Excel and redefine how analysts, data scientists, and enterprise teams work… The list below is every request batching story on Beyond Market Intelligence, newest first.
Explore the LLM Frameworks Shaping Smarter Production Deployments
Comparing LLM frameworks for production can feel like navigating a maze of technical trade-offs. We cut through the noise to compare inference frameworks on request batching, KV cache management, and efficient deployment. Our goal is to make these complex systems accessible so you can choose the right tool for smarter production serving. For a different kind of data challenge, explore our related coding puzzle, "Quest 6: The Nullspiracy," which transforms spreadsheet puzzles into a discovery journey.
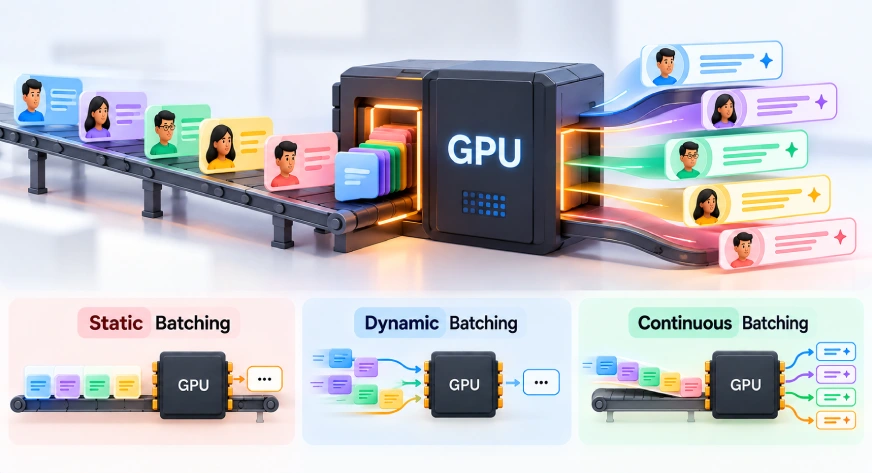
Smarter resource use: how batching transforms LLM performance
Four people heading to the same destination in separate taxis make four identical trips. Put them on a single bus, and everyone arrives together using far less fuel. That is the logic behind batching in large language models. Instead of processing one request at a time, the system groups them, sharing memory and compute across the batch. It is a smarter use of resources that makes AI faster and more efficient. For deeper coverage, explore how hierarchical routing cuts memory while preserving long-context accuracy.