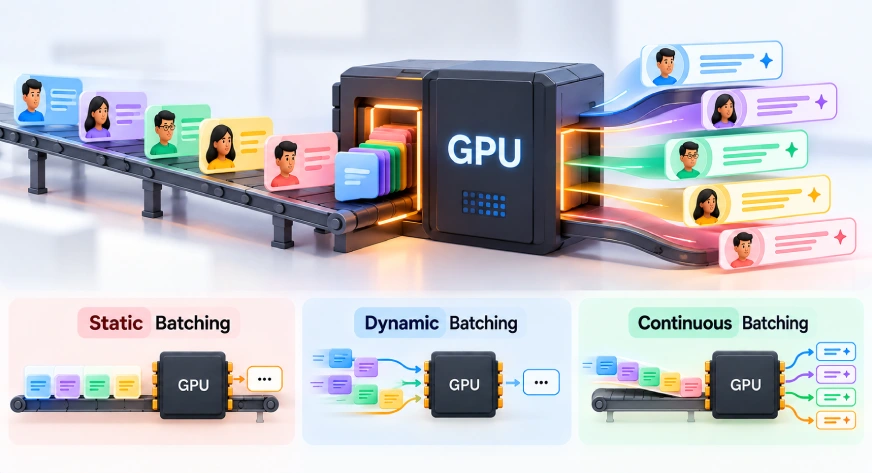
Batching is the quiet workhorse behind every fast, affordable LLM deployment, and the ride-sharing analogy in the story from Analytics Vidhya captures it perfectly: four people to the same destination should take the bus, not four taxis. Static batching groups requests into fixed-size blocks, dynamic batching adjusts on the fly, and continuous batching keeps the bus moving, picking up passengers as seats free up instead of waiting for a full load. The practical difference is enormous. Static batching is simple but wasteful, dynamic improves throughput but still stalls at boundaries, and continuous batching is what makes modern inference servers feel responsive under real-world, unpredictable traffic. This is not a niche engineering detail; it is the difference between paying for four taxis and paying for one bus, at scale.
For anyone building on LLMs, the takeaway is direct: your cost per token and your latency are largely determined by how well your serving layer batches requests. If you are using a managed API, you are already benefiting from continuous batching behind the scenes, but if you are self-hosting or designing a data pipeline, ignoring batching strategy means leaving money on the table. This connects to the broader theme we have been exploring in our coverage of efficient AI infrastructure, such as how hierarchical routing cuts memory while preserving long-context accuracy, where the same principle applies: smarter resource allocation beats brute-force compute. Likewise, when we look at teaching AI to learn from screen video, the underlying efficiency of the model matters as much as the novelty of the interface. And for teams assembling a stack on a budget, the open-source tools we highlighted in building a complete data science stack for free are only viable if the inference layer is cost-conscious.
Our opinion is straightforward: static batching is legacy thinking, and any team still treating it as the default is optimizing for simplicity over economics. The move from static to dynamic to continuous is not a gradual improvement; it is a step change in what a single GPU can deliver. The ride-sharing analogy undersells the magnitude. A bus carries maybe fifty passengers, but continuous batching can increase throughput by several times over static approaches under bursty workloads, with no degradation in user experience. That is not a marginal gain; it is the difference between a service that feels instant and one that feels like waiting for a taxi in the rain.
The specific detail to watch is how batching interacts with memory constraints. Continuous batching requires holding multiple requests in flight, which increases KV-cache pressure, and that is where the trade-off lives. The next wave of optimization will not just batch smarter; it will compress what each request holds in memory, much like the hierarchical routing approach does for long-context tasks. That is the frontier we are watching: not just filling the bus, but making each passenger lighter.