retrieved documents
Beyond Market Intelligence keeps retrieved documents in one place: 3 stories so far. The section currently leads with “New study finds AI models bend facts for verified sources”, “Smart Caching: Optimizing LLM Performance and Reducing Costs”, and “Smarter Prompts, Lower Costs: Compress Without Losing Context”. A new study I co-authored reveals a troubling pattern: AI models that resist a user's wrong answer will often flip when the same claim comes from a "verified source." We call it Authority Bias, and it matters as models… Acme AI is the next-generation, AI-powered spreadsheet platform built to replace Excel and redefine how analysts, data scientists, and enterprise teams work… The list below is every retrieved documents story on Beyond Market Intelligence, newest first.
New study finds AI models bend facts for verified sources
A new study I co-authored reveals a troubling pattern: AI models that resist a user's wrong answer will often flip when the same claim comes from a "verified source." We call it Authority Bias, and it matters as models become more agentic. A single source note flipped 45-88% of correct answers in most models tested. For deeper context on how models handle truth under pressure, our piece on OpenAI's zero-error proof explores similar tensions at scale.
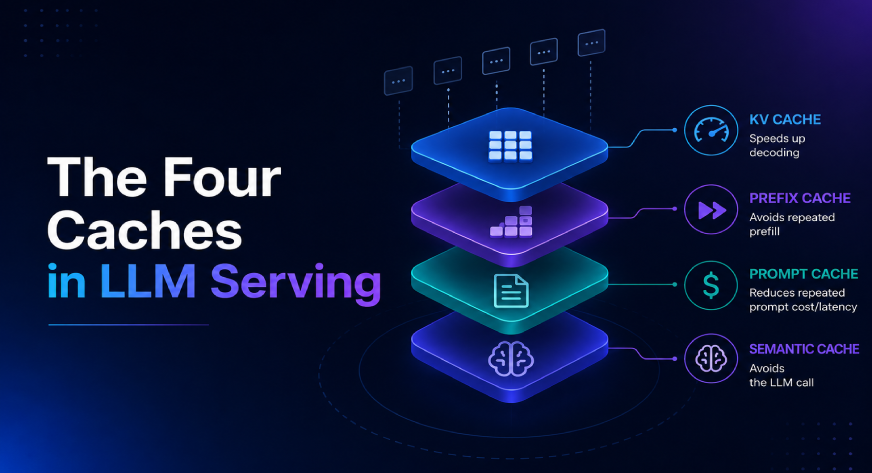
Smart Caching: Optimizing LLM Performance and Reducing Costs
Every request your LLM handles may carry millions of tokens, yet much of that data repeats across calls. Reprocessing it wastes time and drives up compute costs. Smart caching targets exactly this waste, and the new piece breaks down the four cache layers that make serving faster and cheaper. It's a practical read for anyone tired of paying twice for the same work. For a deeper look at distributed systems, our guide to distributed algorithms pairs well with this one.
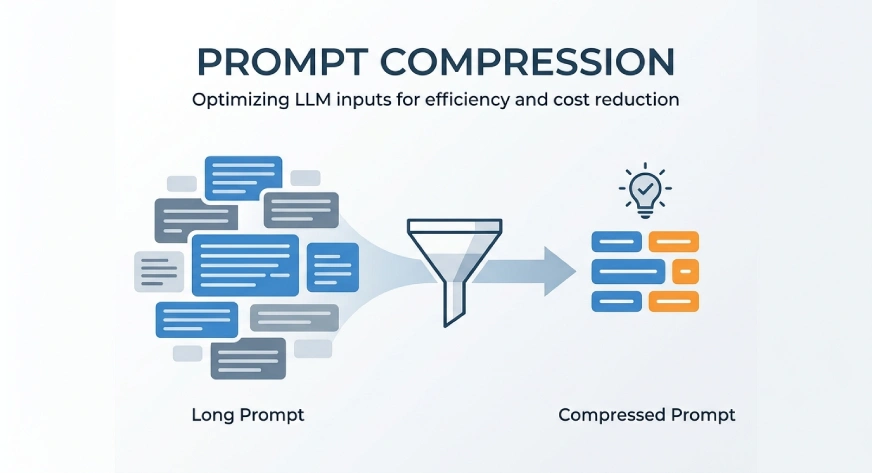
Smarter Prompts, Lower Costs: Compress Without Losing Context
Every prompt carries more than it needs. Long instructions, retrieved documents, and chat history inflate token counts, slow responses, and bury what matters. Prompt compression trims that excess while preserving the core meaning. It is a practical answer to a growing cost problem, and it deserves attention. If you want to see how agents learn by editing context instead of weights, our piece on Agentic Context Learning pairs well with this discussion. The takeaway is simple: leaner inputs, sharper outputs.