system reliability
Beyond Market Intelligence keeps system reliability in one place: 7 stories so far. The section currently leads with “How Gearset replaced guesswork in queue debugging with OpenTelemetry tracing”, “When Tools Break, Your AI Agent Keeps Writing Confident Answers”, and “Uber's dependency analysis moves beyond sampled tracing to classify failure types”. Queue debugging often feels like guessing. When a tool fails, most systems go silent. Acme AI is the next-generation, AI-powered spreadsheet platform built to replace Excel and redefine how analysts, data scientists, and enterprise teams work… The list below is every system reliability story on Beyond Market Intelligence, newest first.
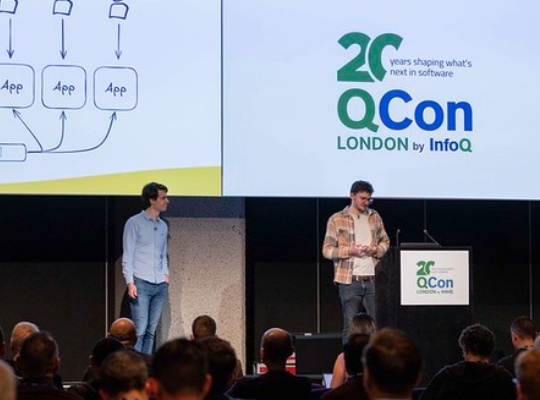
How Gearset replaced guesswork in queue debugging with OpenTelemetry tracing
Queue debugging often feels like guessing. Gearset's Oli Lane and Julian Wreford show how OpenTelemetry tracing replaces that uncertainty in distributed asynchronous queues. They explain why traditional metrics miss the mark and offer practical tips for implementing user-centric SLOs based on latency distributions. For senior developers and engineering leaders, this is a concrete path to better reliability and team culture. Readers exploring observability may also appreciate how Pinterest and Intel scaled open-source profiling across the internet.
When Tools Break, Your AI Agent Keeps Writing Confident Answers
When a tool fails, most systems go silent. But an AI agent built for production doesn't stop, it keeps writing confident answers from nothing, even as the dashboard stays green. That resilience is the point. For a deeper look at keeping these agents reliable, our guide on adding practical guardrails with Gemma 4 and Ollama is a natural next step.
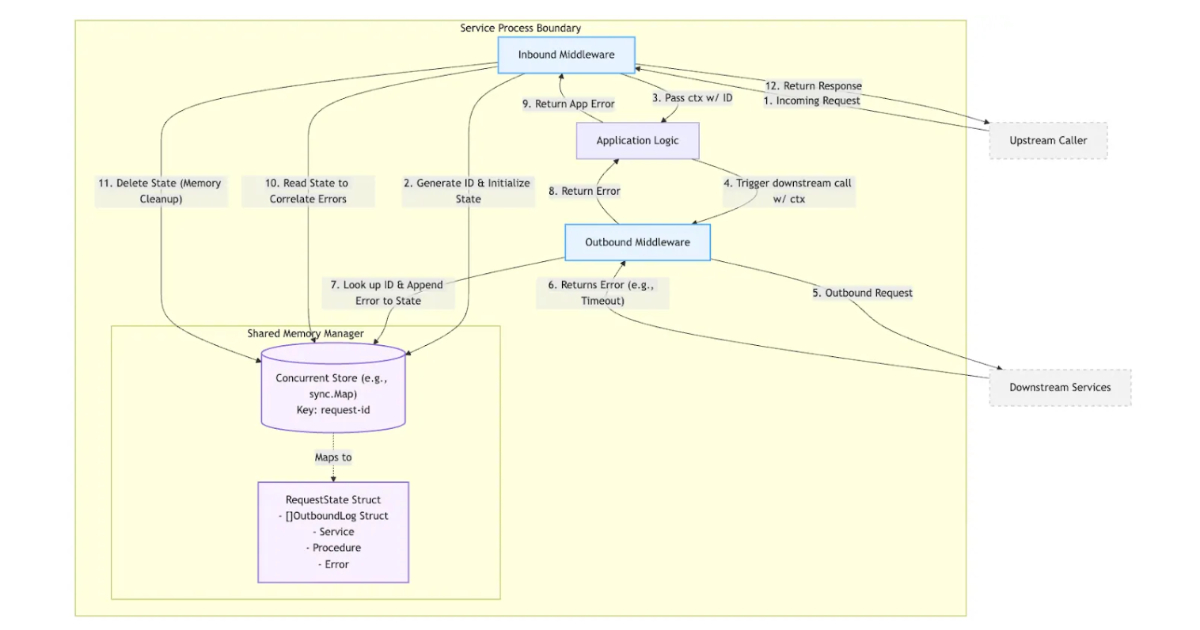
Uber's dependency analysis moves beyond sampled tracing to classify failure types
Uber's dependency analysis moves beyond the limits of sampled tracing, which can miss rare failures across a sprawling service mesh. By using RPC middleware and production metrics, the system classifies dependencies as fail-close, fail-open, or unknown. This approach is a practical step forward for engineers tired of guessing which downstream service caused an outage. For more on how platforms manage complex infrastructure, see our coverage of Grafana Tempo 3.1, which empowers operators to redact traces with simple queries.
When health checks lie, high availability becomes a hollow promise
Most system outages aren't caused by hardware failure. They're caused by control-plane dependencies, the invisible threads that tie your application to authentication services, DNS, or configuration stores that nobody remembers to test. Alexey Golev's article makes a clear case: high availability and resilience are not the same problem, and treating them as interchangeable leaves teams with a false sense of safety. Recovery capability erodes without explicit ownership.
Move beyond basic RAG with four knowledge graph patterns for agentic AI.
Knowledge graphs are moving from the background to the backbone of agentic AI, and Cassie Shum is here to show you why. In her talk, she moves past basic retrieval to outline four practical architecture patterns that bring reasoning into production. It's a grounded, actionable look at building systems that don't just retrieve, but reason. For a broader perspective on how these ideas connect, our piece on bridging retrieval and action offers a useful parallel.

Predict infrastructure failures before they disrupt your workflow.
Empirik has launched with $21M in funding, backed by Sequoia, to predict IT outages before they strike. The mission is straightforward: give infrastructure the same proactive intelligence that Cursor brought to software engineering. That comparison matters because it signals a shift from reacting to problems to preventing them. For teams tired of firefighting, this is a practical step toward calmer operations. And if you're curious how similar predictive logic plays out in other fields, our piece on adaptive recommendation systems offers a useful parallel.
Why More Incidents Can Mean Stronger System Reliability
A rising incident count is easy to read as a red flag, but Great Circle's recent analysis suggests otherwise. More reports often mean your team is actually getting better at surfacing problems, a compelling case in itself. That is a sign of health, not decline. It reframes how we should interpret operational noise. For engineering leaders wrestling with this tension, it is worth exploring how a mature incident culture changes the metrics you trust.