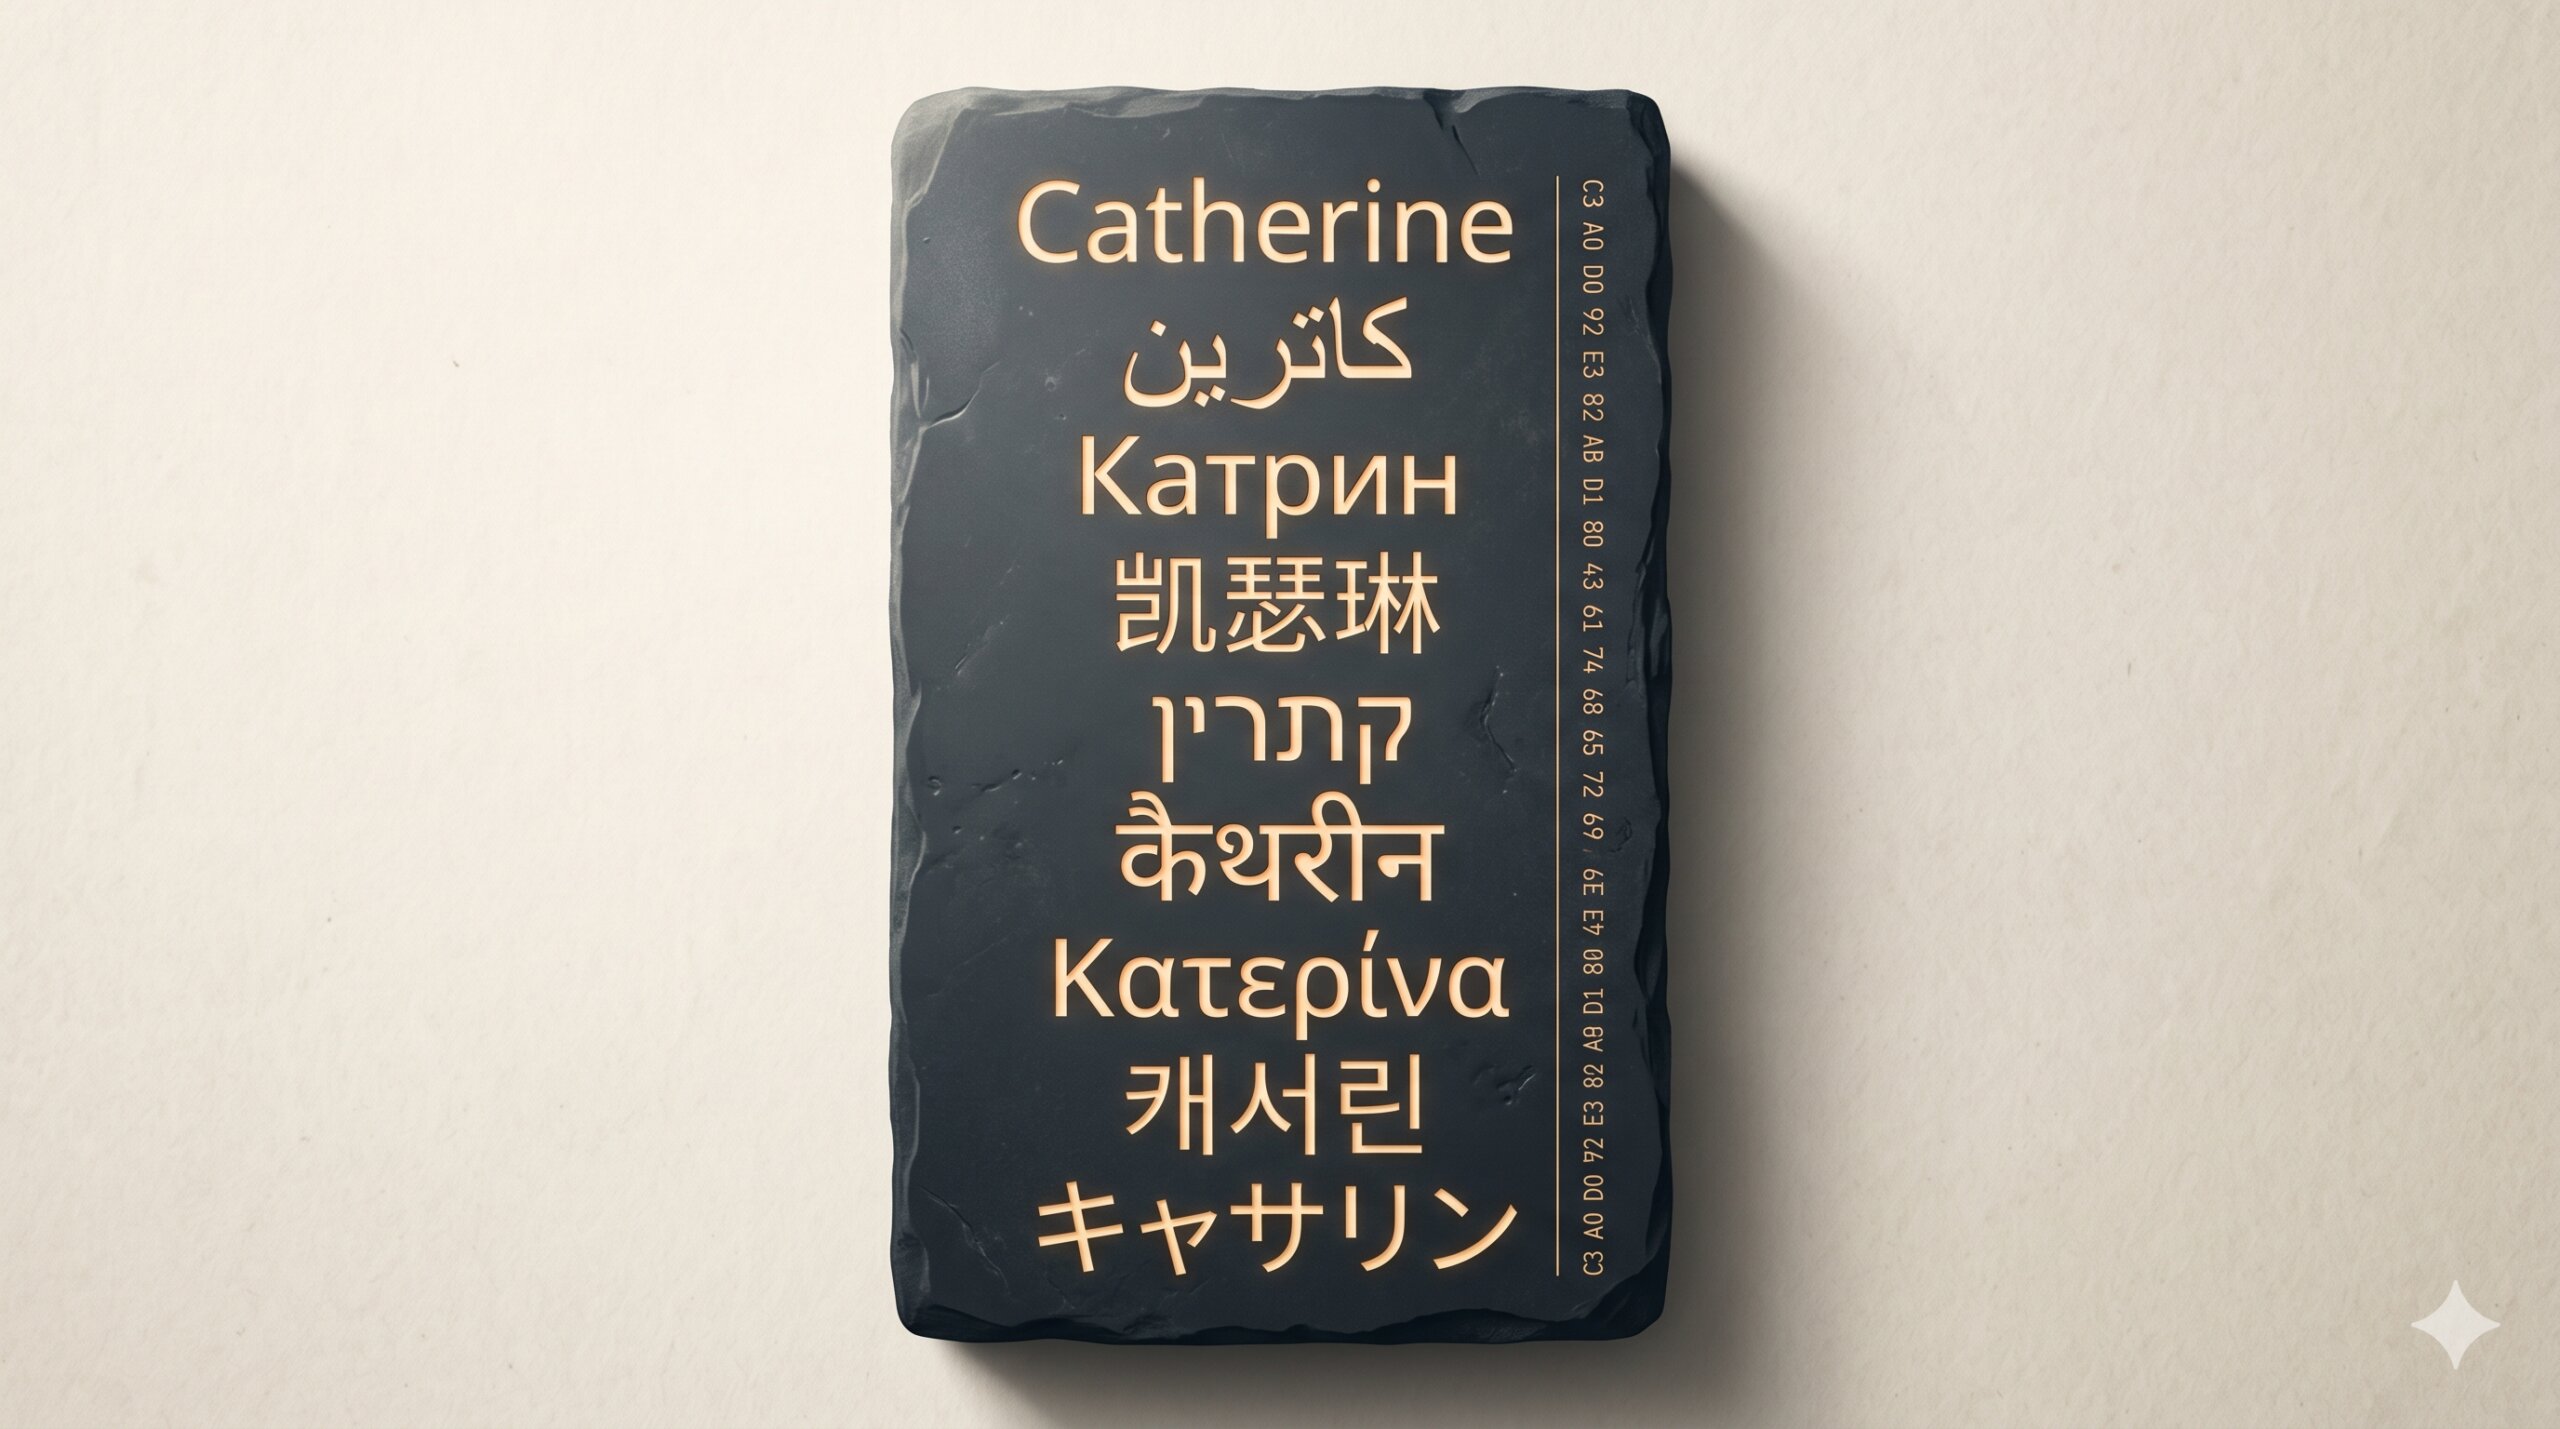
The idea that a single model can learn to retrieve names across scripts without ever seeing a translation dictionary is quietly ambitious. The core insight, that 256 bytes can speak every language, reframes what we should expect from AI-native tools. Instead of forcing users to learn eight scripts to search one database, we can build systems that recognize the underlying identity of a name, regardless of whether it is written in Devanagari, Cyrillic, or Latin characters. That is not a minor convenience; it is the difference between a tool that meets you where you are and one that demands you adapt to its limitations.
For anyone who has wrestled with mismatched name fields in a CRM or tried to reconcile customer records across borders, the practical impact is immediate. Traditional spreadsheets treat "José" and "何塞" as entirely unrelated strings. A cross-script retrieval system, built on contrastive learning, learns that these are the same person, the same vendor, the same patient, simply by understanding the bytes that represent them. This means your workflow no longer hinges on a single language standard. You stop translating data into one canonical form and start letting the model bridge the gap for you. The time saved is not measured in seconds per search but in hours per week, and the accuracy improves because you are no longer relying on lossy transliterations.
What makes this approach feel right for the future of data management is that it does not ask you to abandon how you already work. You are not learning a new query language or memorizing a new schema. You are simply asking your tool to be smarter about the messy, multilingual reality of your data. The contrastive learning method at the heart of this research is not about brute-force memorization; it is about teaching the model to recognize patterns of similarity across scripts. That is a more human-centered approach than forcing everyone to standardize on one script, because it respects the diversity of how people actually write their own names.
The takeaway is this: the next time you feel stuck because a name does not match across two systems, the answer is not to build a bigger mapping table. The answer is to explore a model that already understands the relationship between scripts. This research points toward a practical path forward, one where data entry and retrieval stop being a barrier to collaboration. It is a concrete step toward tools that feel less like software and more like a patient assistant who just happens to read every language. We should be paying attention to that, not because it is a novelty, but because it changes what we can reasonably ask of our spreadsheets tomorrow.