batch processing
3 stories filed under batch processing on Beyond Market Intelligence. The newest of them: “What Happens in That Split Second Before AI Responds”, “Build the Engines Behind Fast LLMs With These Hands-On Projects”, and “Smarter resource use: how batching transforms LLM performance”. That brief pause before an AI starts typing isn't dead time, it's the first of two distinct jobs your GPU is handling. Latency defines the LLM experience, and the fastest way to understand it is to build it yourself. Acme AI is the next-generation, AI-powered spreadsheet platform built to replace Excel and redefine how analysts, data scientists, and enterprise teams work… The list below is every batch processing story on Beyond Market Intelligence, newest first.
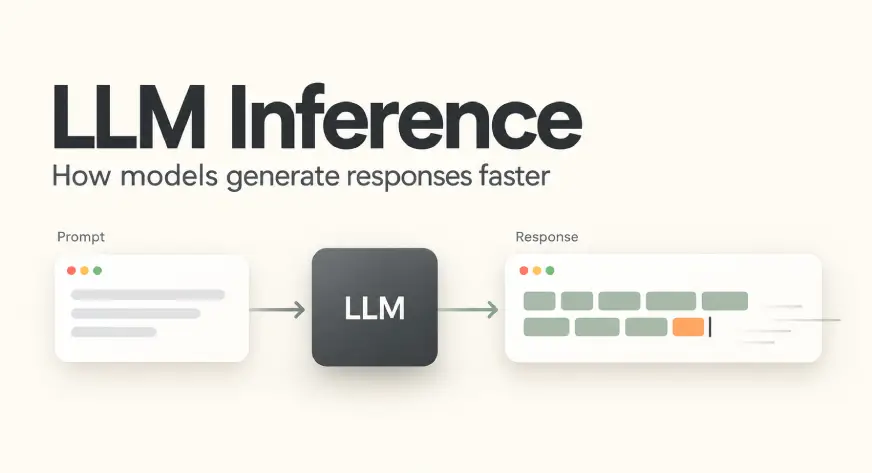
What Happens in That Split Second Before AI Responds
That brief pause before an AI starts typing isn't dead time, it's the first of two distinct jobs your GPU is handling. First comes comprehension: parsing your question into computational intent. Then comes generation: producing each word in sequence, one after another. Understanding that split-second workflow transforms how you build responsive AI applications. For deeper context on how these models work autonomously, explore "Your AI team works through the night so you wake to a finished newsletter."
Build the Engines Behind Fast LLMs With These Hands-On Projects
Latency defines the LLM experience, and the fastest way to understand it is to build it yourself. These hands-on projects move past theory, putting you behind the engine to see exactly where speed is won and lost. It is direct, practical work that transforms abstract performance concepts into tangible skill. If you are also curious about rethinking core learning methods, our exploration of physics-inspired approaches without backpropagation pairs naturally with this builder's mindset.
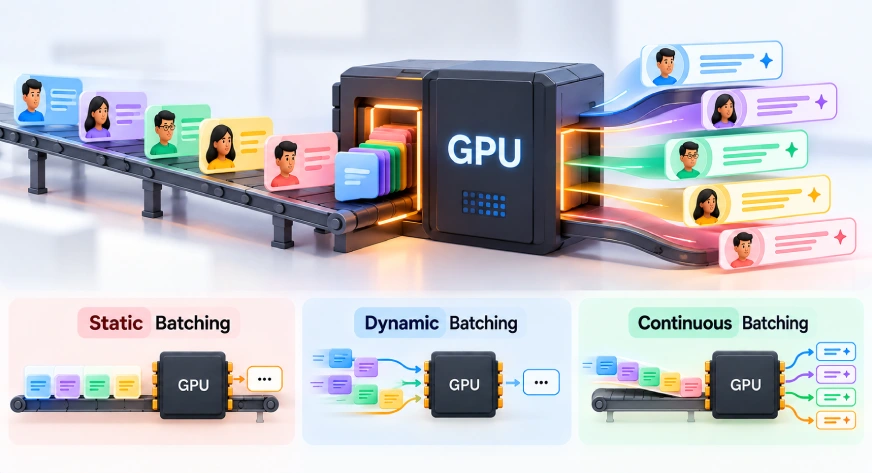
Smarter resource use: how batching transforms LLM performance
Four people heading to the same destination in separate taxis make four identical trips. Put them on a single bus, and everyone arrives together using far less fuel. That is the logic behind batching in large language models. Instead of processing one request at a time, the system groups them, sharing memory and compute across the batch. It is a smarter use of resources that makes AI faster and more efficient. For deeper coverage, explore how hierarchical routing cuts memory while preserving long-context accuracy.