database
database at Beyond Market Intelligence is a file of 25 stories. The newest of them: “CedarDB unifies operational and analytical data as AI agents demand more”, “Explore DuckDB's direct access to Hugging Face datasets, no downloads needed”, and “Explore 5.6 Billion TikTok Videos Through an Accessible Public Database”. Traditional databases force you to choose: optimize for operational speed or analytical depth. DuckDB now reads Hugging Face datasets directly, no downloads, no local storage juggling. Acme AI is the next-generation, AI-powered spreadsheet platform built to replace Excel and redefine how analysts, data scientists, and enterprise teams work… The list below is every database story on Beyond Market Intelligence, newest first.

CedarDB unifies operational and analytical data as AI agents demand more
Traditional databases force you to choose: optimize for operational speed or analytical depth. CedarDB refuses that trade-off. Its engine was built from the ground up to handle both, a design choice that looks prescient as AI agents demand real-time access to live data alongside complex queries. This isn't an incremental upgrade, it's a different foundation. For a glimpse at how agents are already reshaping workflows, see our piece on Floqer's approach to prospect research.

Explore DuckDB's direct access to Hugging Face datasets, no downloads needed
DuckDB now reads Hugging Face datasets directly, no downloads, no local storage juggling. That's a meaningful step toward removing friction from data workflows. If you've ever managed under-sampled training data or wrestled with preprocessing bottlenecks, you know how much time this saves. Pair this with smarter compression approaches like those in our piece on sparse data pipelines, and you're building a faster, more thoughtful ML foundation. Explore it, and see how direct access changes your process.
Explore 5.6 Billion TikTok Videos Through an Accessible Public Database
Five point six billion TikTok videos is a staggering number, but the real story here is access. The dataset is massive, yet the creator behind this project has made it genuinely approachable by hosting it on ClickHouse. You can dig into 4.5 billion creator rows or 633 million sounds without spinning up your own cluster. Just be kind and avoid heavy queries. It is a practical, human-centered way to explore a monumental cultural archive.
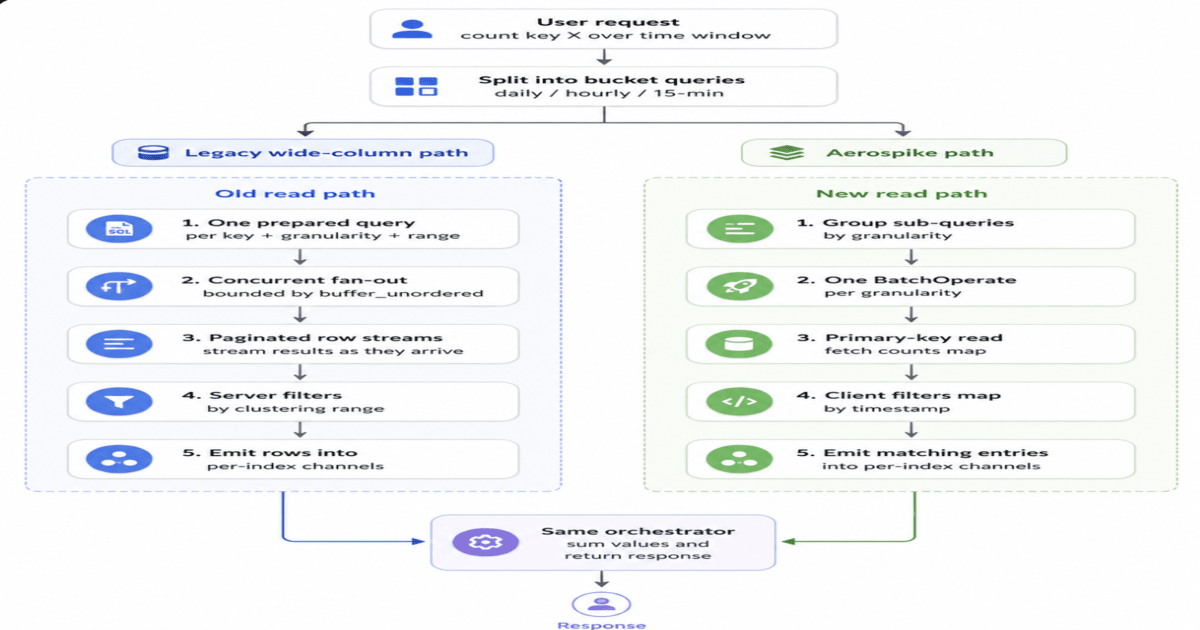
Grab Cuts Spreadsheet-Style Data Delays With a Smarter Storage Shift
Grab cut spreadsheet-style data delays by rethinking how it stores high-volume Counter Service data. Moving from a wide column database to Aerospike, with storage abstraction, shadow traffic, and gradual migration, slashed production p99 read latency by roughly 50%. Disk usage dropped to 1 TB from 3 TB, and per-node costs fell up to 50%. That is a smarter storage shift worth exploring. For deeper engineering lessons, our piece on building Python AI libraries in production pairs well with this story.
Maximize Your Power BI Pipeline Without Wasting Time on Dead Ends
You're right to question whether Excel VBA opening a file is the most reliable path, it often creates more dead ends than solutions. Power BI Premium with Copilot gives you a cleaner option: schedule a direct refresh through the service, or use Power Automate to trigger a refresh when a new CSV lands in SharePoint. Skip the Excel middleman entirely. Your data pipeline should flow forward, not loop through fragile workarounds.
Mastering Multi-Link Data: Calculate Across 500K Records in One Move
Working with 500K records across linked tables is a real test of any tool. The situation here is familiar: Table 1 and Table 2 hold the raw data, but the desired result in Table 3 requires calculating across multiple links, with averages as the fallback. The challenge is determining the scenario without cross-referencing data from the other table first. This isn't a Power Query limitation, it's a structural puzzle.
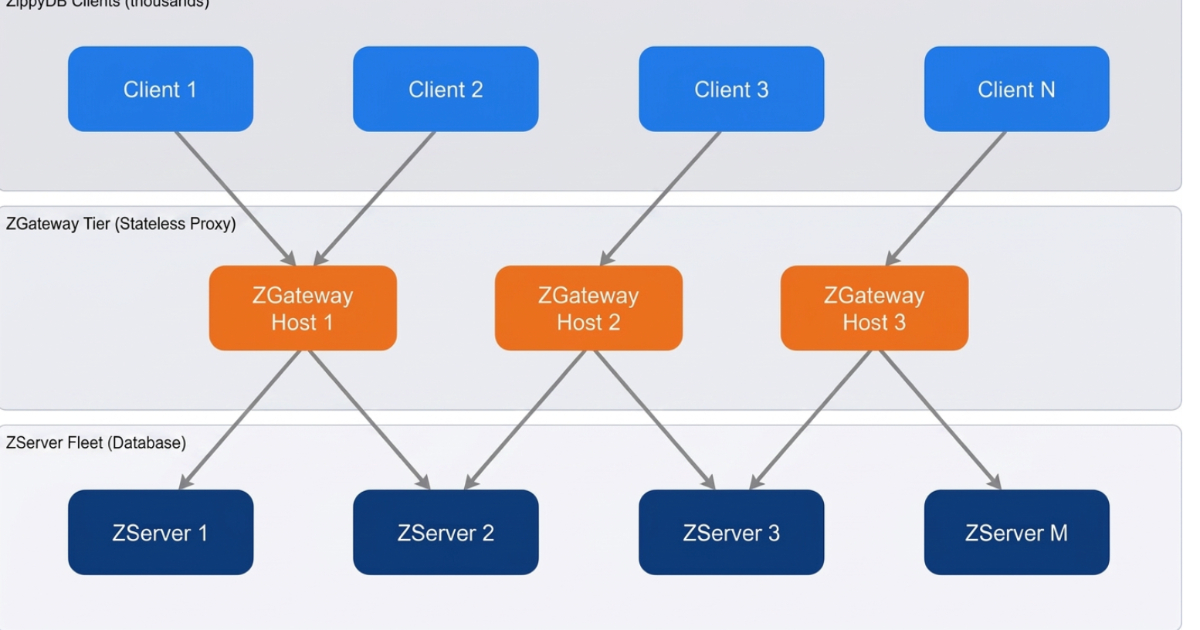
How Meta's ZGateway Slashes Connections 19x While Processing a Billion Operations Per Second
Meta's ZGateway is doing something quietly remarkable: slashing persistent connections by 19x while processing over a billion operations per second. That's not just efficiency; it's a rethinking of how stateless proxies can centralize traffic without becoming a bottleneck. By handling 40% of ZippyDB traffic, it proves scale and simplicity can coexist. For teams wrestling with connection sprawl, this is a model worth studying. And if you're curious about Meta's broader engineering bets, our piece on Linear's StyleX migration offers another angle.
Aurora DSQL now enforces data integrity with foreign key support
Aurora DSQL's new foreign key support closes a gap that was blocking adoption for many teams. This isn't a small update, enforcing referential integrity directly in the database, with CASCADE and SET NULL actions, makes the platform feel more mature. It's the kind of practical improvement that turns a promising tool into a dependable one. For those exploring how modern infrastructure choices impact performance, Cloudflare's experience with EmDash offers a related look at moving beyond legacy systems.
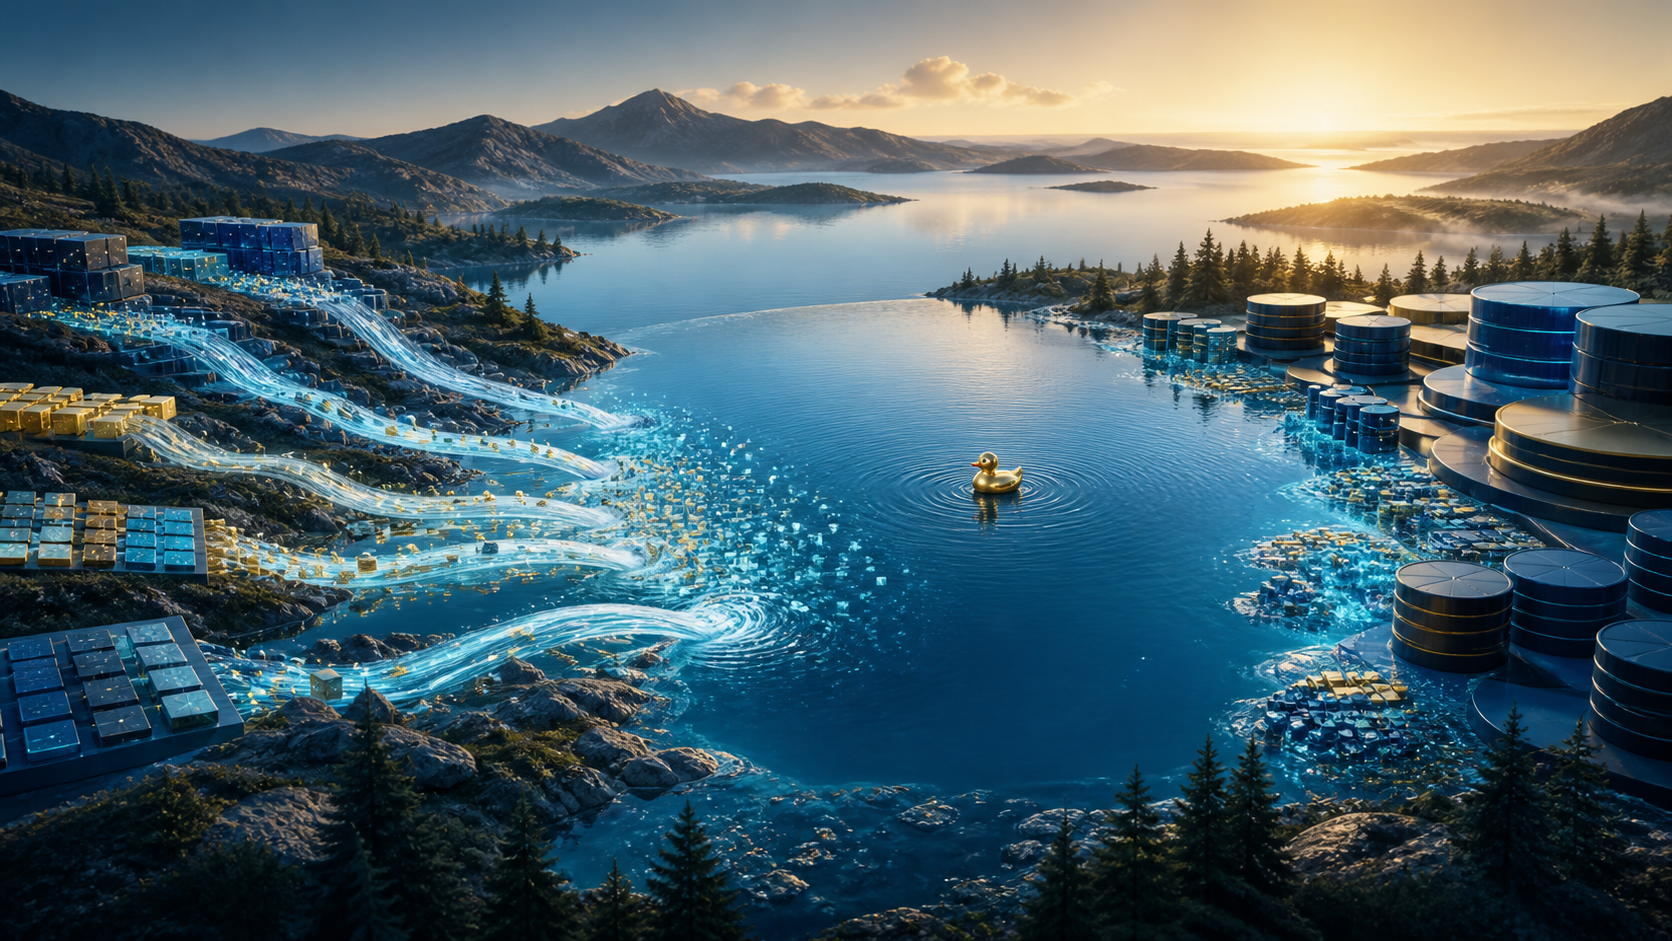
Unlock Data Insights: Building a Lakehouse with DuckDB and DuckLake
A single Parquet file on your laptop might not feel like a data lakehouse yet. But when you join that local data to cloud storage in the same query, the picture sharpens. DuckDB and DuckLake make this transition straightforward, not theoretical. It is a practical path from isolated files to a unified analytics layer. If you are tired of wrestling with complex infrastructure, this walkthrough feels like a breath of fresh air.
Build smarter agents by connecting LangGraph to Postgres locally or in the cloud.
Connecting a LangGraph AI agent to Postgres doesn't have to be a headache. This walkthrough shows you exactly how to run the backend locally with Docker or scale it to the cloud, keeping the focus on practical steps rather than abstract theory. It's a straightforward approach for anyone tired of wrestling with database integrations. We appreciate the clarity here, especially since so much AI tooling feels needlessly complex. For deeper context on how LLMs handle structure, our piece on paragraph navigation is worth a look.
From a Million Files to One Clean Table: Structured Extraction for Real Queries
Two people, one hour, six to ten fields. That is the entire setup for turning a single document type into a million structured rows, and the two signals that define a real column are the ones that keep a filter from breaking later. It is a focused, practical read. If you want to see how paragraph structure guides an LLM through token space, our related piece on that topic pairs well here.
Explore how recursive CTEs simplify graph traversal in SQL.
Most of us treat SQL as a tool for flat tables, but recursive CTEs unlock something far more interesting: the ability to traverse relationships directly in your database. This guide shows how to navigate hierarchies, detect cycles, and even calculate degrees of separation without leaving SQL. It's a practical, empowering look at a hidden capability. If you're ready to move beyond simple queries, this is your entry point.
DuckDB v2.0 Opens a Network Gateway for Distributed Data
DuckDB v2.0, codenamed "Cyanoptera," is making a bold architectural move. After over 10,000 commits, the preview introduces a client/server mode that opens the door to real network connections. That's not just a feature; it's a fundamental shift in how we think about embedded analytics. We also see progress in extension portability and asynchronous I/O, which should make data work feel more fluid. This is a forward-looking step.
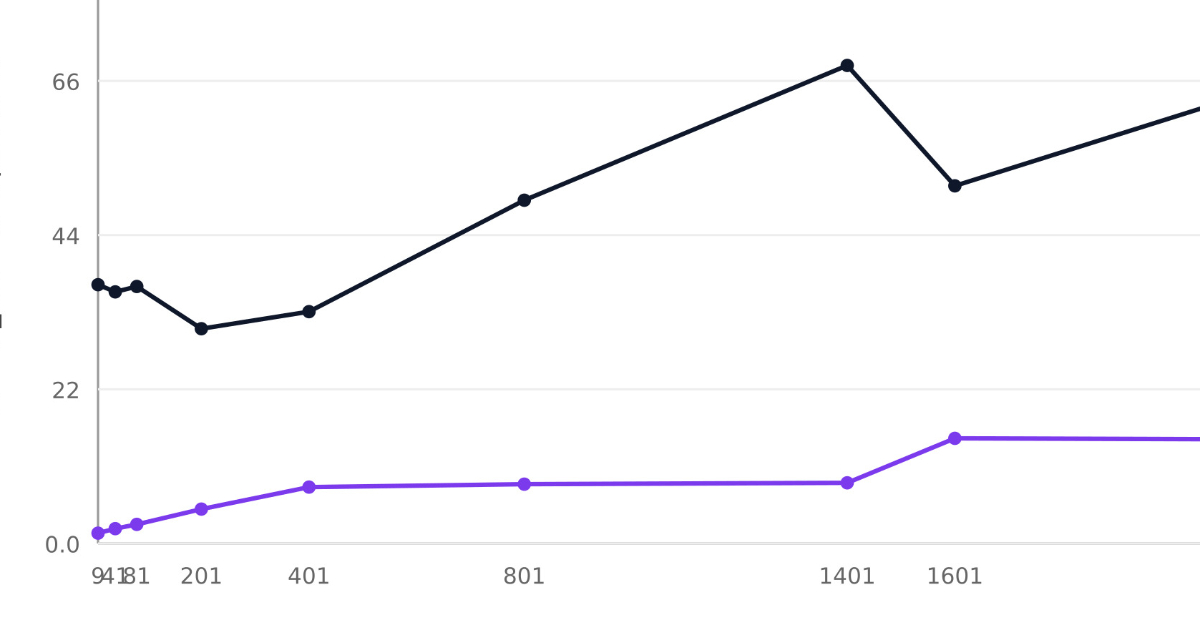
Single runtime outperforms multi-system stacks for live data workloads
Harper is pushing back on the multi-system stack, and the argument is hard to ignore. By keeping application code and data together in a single runtime, the database platform reports notably better performance on live, personalized workloads compared to a Vercel-based setup. Version 5.2 adds a record cache and greater throughput per node. That is a practical step toward less complexity. For readers tracking how modern architectures evolve, our related piece on Cloudflare's CMS migration offers another angle worth exploring.
Build offline data collection forms that feel simple and familiar
Building a simple data collection form in Excel is absolutely doable, and it sounds like the right fit for your group. You can use form controls to create a clean interface with labeled fields, a submit button, and a linked table on a separate tab. Macros can handle the data transfer securely, and password-protecting the file adds a layer of GDPR compliance. It's a practical upgrade from Access, offering familiarity without the complexity.
Run Your Data Analysis Where Your Data Lives
Most dataframe work pulls data out of the database, then pushes it back after Python finishes its part. memFrame flips that script. It compiles your Python/DataFrame API calls directly into SQL, letting DuckDB, PostgreSQL, or ClickHouse do the heavy lifting where the data lives. That is a smarter default. The incremental release strategy is also a good discipline: get inspection, cleaning, and arithmetic solid before tackling groupby and window functions. For deeper Python performance thinking, our guide on advanced techniques pairs well here.

Explore remote SQL execution with three concurrent DuckDB servers.
DuckDB is known for being fast, but what happens when you push it beyond a single machine? In this experiment, the team behind Quack ran SQL concurrently across three remote servers to see if the database could handle the pressure. The result is a practical look at distributed execution that feels both ambitious and grounded. It is not about hype; it is about what actually works. If you are exploring how AI-native tools handle real-world data challenges, this is a worthwhile stop.
DynamoDB Unifies Data and Vector Search Without a Separate Database
DynamoDB now lets developers store embeddings right alongside their application data and run approximate nearest-neighbor queries without spinning up a separate vector database. That's a meaningful simplification for teams building semantic search features. Filtered similarity searches and configurable indexes make it practical, not just theoretical. It's the kind of move that reduces operational overhead while keeping workflows familiar. If you're exploring how far native database capabilities can stretch, this is worth a look.
Discover how linked tables keep your expense data in perfect sync
You've built a solid system: a parent table for expense types, linked child tables that filter rows through a dropdown. It's tidy, but adding a new expense means manually copying rows and formulas into each child table. That's the friction. The good news? This is exactly where an AI-native approach earns its keep. Instead of chasing updates, imagine the child tables syncing automatically, pulling new rows and their formulas the moment the parent grows.
From 60 years of databases to 18 months of agents, memory bridges the gap.
Six decades of database engineering. Eighteen months of modern AI agents. That ratio explains everything about the state of agentic development right now, we're not mid-curve, we're at its base. Token-maxxing already taught us the hard lesson: context is scarce, and stuffing it isn't strategy. The real answer is persistent, queryable memory, semantic, access-controlled, human-curated, that makes each expensive answer cheap next time. That's the architecture emerging.
How Stripe Uses Graphs and State Machines to Automate Database Recovery
When Stripe's database misbehaves, they don't wait for a human to save the day. Their engineering team models the entire global infrastructure as a graph, then lets search algorithms find the problem while state machines execute the fix. That's a smart shift from reactive firefighting to automated recovery. It's practical, and it shows how mature AI-assisted operations have become. For more on putting intelligent automation to work, our guide on unlocking ChatGPT for work is worth a look.
CosmosEscape exposed a shared responsibility gap that demands closer attention.
Wiz Research uncovered CosmosEscape, a chain that slipped past Azure Cosmos DB's Gremlin sandbox and reached a platform-wide key with read and write access to every database on the service. Microsoft closed the entry point in two days, yet the key lingered until July 2026. That timeline raises real questions about shared responsibility and what removing it actually cost. Practitioners are right to debate whether the rearchitecture delivered enough value, or if faster key rotation should have been table stakes.

Explore how medallion architecture simplifies your data pipeline with Python and DuckDB
Most teams hit the same wall: raw data lands in one place, and chaos follows. The Medallion Architecture cuts through that with a clear Bronze, Silver, and Gold path, turning mess into structure. This guide pairs that framework with a working Python and DuckDB example, so you can see it run, not just read about it. For more on how LLMs navigate token space, check out our piece on paragraph structure.

Airtable's new chapter begins with a strategic $1.28 billion acquisition
Airtable's journey from an $11 billion valuation to a $1.28 billion acquisition is a striking one. Bending Spoons is known for acquiring products with strong foundations and refining them for efficiency. This move suggests a belief that Airtable's core remains solid, even if the market's enthusiasm has cooled. It is a pragmatic bet on a tool that still defines a category. For users, the focus will likely shift toward integration and polish. If you are following the broader infrastructure story, our piece on Nscale's $3.