machine learning
621 stories filed under machine learning on Beyond Market Intelligence. The newest of them: “Connecting with U.S. Tech: Paris or Sydney for Industry Networking?”, “Uncover Retrieval Weaknesses: Test Your RAG Pipeline Now”, and “Code an Internal Speaker Recognition Tool with Claude”. Choosing between Paris and Sydney for U.S. Your evaluation set has a blind spot, and it's costing you. Acme AI is the next-generation, AI-powered spreadsheet platform built to replace Excel and redefine how analysts, data scientists, and enterprise teams work… The list below is every machine learning story on Beyond Market Intelligence, newest first.
Connecting with U.S. Tech: Paris or Sydney for Industry Networking?
Choosing between Paris and Sydney for U.S. tech networking is a smart dilemma, and the answer often depends on timing. Major U.S. companies and labs frequently send researchers to both cities, but their presence peaks around specific conferences and academic exchanges. Paris tends to attract more AI and machine learning events, while Sydney hosts strong computer vision and systems research meetups. For targeted connections, check the event calendars of U.S. labs with European or Asia-Pacific branches.
Uncover Retrieval Weaknesses: Test Your RAG Pipeline Now
Your evaluation set has a blind spot, and it's costing you. A small adversarial test set can expose retrieval failures your standard checks never touch, revealing exactly where your RAG pipeline stumbles under real-world pressure. This approach isn't about adding more data; it's about testing smarter. We think that's a practical, necessary step for anyone serious about reliability. For a deeper dive into how these systems hold up, our guide, "Verify Your AI's Understanding: A Simple Check for Tax Season," offers a useful parallel.
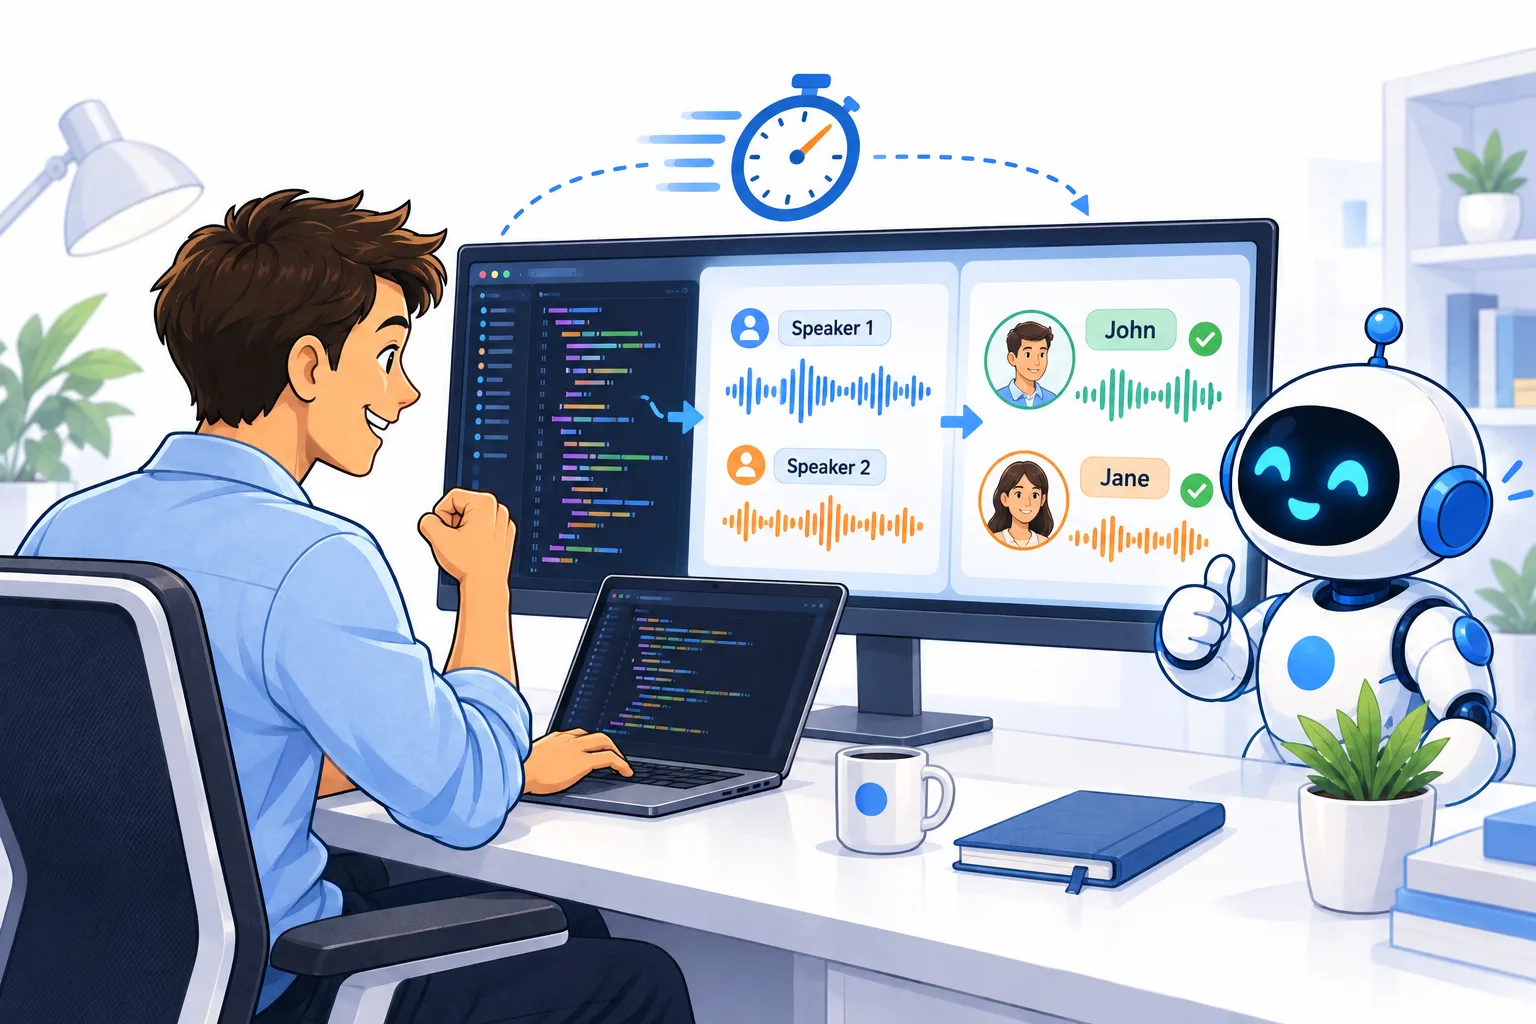
Code an Internal Speaker Recognition Tool with Claude
If you've ever wrestled with identifying who's speaking in a meeting recording, building a speaker-recognition tool from scratch can feel like a heavy lift. This guide walks through coding one internally with Claude, turning a complex audio challenge into a practical, hands-on project. It's a smart, accessible approach for teams ready to move beyond manual transcription. For a broader look at how AI handles real-world inputs, you might also enjoy *Exploring Real-World Computer Vision*, it pairs nicely with the concepts here.
Bridging Embedded Systems Expertise to the World of Machine Learning
The question of whether embedded systems skills translate to machine learning engineering is one we hear often. The answer is a firm yes. That background in C, Linux, and memory management is not just useful; it's foundational. It gives you an instinct for how systems truly operate, which is a distinct advantage. This expertise becomes critical when scaling models, where distributed systems and parallel computing are core.
Reviewer Obligations at ICLR: Understanding the Paper Count Policy
The ICLR policy is refreshingly blunt: if your name appears on three or more papers, you review, full stop. No qualifications, no experience check, no debate. That means Alex, a new student fourth-author on three lab papers, is on the hook, even if they feel unready. It is a blunt instrument, but it is also a clear one. The policy prioritizes volume of contribution over perceived expertise, which is a fair trade-off for a field that needs many hands.

Unlock 2D Rotations: Exploring the Power of Complex Kimi Delta Attention
A single step is all it takes for Complex Kimi Delta Attention to rotate data in 2D space, provided the gate range stretches to [-1,1] and the learning rate reaches [0,2]. That is the core insight from the paper on CKDA, which demonstrates how this extended form tracks S3, S4, and A5 groups, though it stops short of S5. The experiments show stable training and competitive language modeling, making this a practical step forward.

Explore the Inner Workings of sanoTTS: A Deep Dive into AI Synthesis
Every tensor on the sanoTTS anatomy page is real, pulled from the shipped int8 model as it synthesized an actual sentence. No stand-ins. That authenticity turns a technical breakdown into something you can trust and explore. This is vibe coding at its best, using interactive visuals to make the core mechanics of AI synthesis click. If you are curious about how these models truly operate, this is a refreshingly honest look.
Accelerate Numerical Solutions: Introducing LinearSolveBench
Large sparse linear systems are where real numerical work gets slow, and most models stumble trying to write efficient C solvers. LinearSolveBench, a new benchmark from hgarud, directly measures how well a model or harness can produce fast, accurate, and general solvers for these systems. It pushes for algorithmic progress where it matters most: practical performance. If you are exploring how AI handles demanding computational tasks, this is a focused, honest stress test worth your attention.
Measure Embedding Relevance: A New Approach to Retrieval Benchmarking
Retrieval benchmarks often feel like they reward models for gaming the test rather than finding the right answer. The team at Qonto noticed this gap and built a metric that ties relevance more directly to real product questions. They paired it with a dedicated dataset, and the results point to a more honest measure of embedding quality. It is a practical step toward benchmarking that actually reflects how teams retrieve information.

Visualize Neural Network Training: A Step-by-Step Interactive Tool
Watching weights adjust in real time is the difference between memorizing backprop and actually feeling it. OpenTrainDNN strips away setup friction, letting anyone tweak learning rates or network depth and see convergence or collapse happen live. That's the kind of hands-on clarity theoretical guides often miss. For a tool built to demystify training mechanics, it hits a practical sweet spot. If you're curious about broader model deployment challenges, our related piece on real-world computer vision offers a useful follow-up.
Exploring OpenAI: How AI is Reshaping Data Ownership and Access
Data ownership used to feel like a settled argument, but AI is quietly rewriting the terms. As models learn from our spreadsheets and inputs, the question isn't just who holds the files, but who controls the insights hidden inside them. That shift deserves attention. We explore how OpenAI's tools are pushing this conversation forward, challenging old assumptions about access and authority.
Navigating ICLR LLM Feedback: Insights and Improvements
A single review that buries one or two valid points under three pages of nitpicking is a familiar experience for anyone who has submitted to a crowded venue. This user's take on ICLR's LLM feedback is refreshingly measured. They acknowledge the initiative's value while questioning its execution. The real friction is the lack of a warning that the review stays public, a small courtesy with big implications. Addressing both valid and petty feedback takes effort, but it is the right call.
Accelerating Research: Can Review Systems Handle AI-Driven Productivity?
ICLR 2027's submission surge is a clear signal: genuine ML research is accelerating, not just the noise. We're seeing ideas that once took days of coding collapse into hours, and the momentum is real. But this productivity boom forces a hard question about our review infrastructure. If we expect humans to keep pace with an exploding volume of contributions, we need to empower reviewers with agentic tools. Otherwise, the bottleneck shifts from discovery to evaluation.
Streamline Your PhD: Four AI-Powered Research Tasks
A PhD thesis is a marathon of small, tedious tasks that drain your energy before the big finish. This guide cuts through the noise, showing how AI can handle the grunt work: tracking down citations, cleaning up code, double-checking facts, and prepping for the defence. It's a practical toolkit for reclaiming your time, not a magic bullet. The focus on verification over blind trust is smart.
Exploring Autograd: A High Schooler's C++ Machine Learning Project
Building a tensor library and autograd engine from scratch in C++ is no small feat, especially for a high schooler. That kind of hands-on exploration is how you truly internalize the mechanics behind machine learning, moving beyond black-box frameworks. This project shows genuine curiosity and a solid grasp of fundamentals. We appreciate the willingness to share it for feedback. For those interested in seeing how such foundational work connects to real-world applications, our piece on real-world computer vision deployments offers a useful perspective.

Anthropic's Opus 5.5 Delivers Fable Performance at a Lower Cost
Anthropic says Opus 5.5 is the strongest model it has tested to date, and the headline numbers back that up with a welcome twist: this level of fable performance arrives at a lower cost. That matters for teams who have been waiting for serious AI capability without the usual premium. We see this as a practical step forward for data work, not just a spec sheet win.
Jev: AI That Decides, Not Just Writes
Most spreadsheet users know the pain of writing formulas; Jev skips the typing and moves straight to the outcome. This AI doesn't just generate text for you to interpret; it makes the call, deciding what the next step should be based on your data. It's a direct answer to the question of what happens when the tool stops assisting and starts acting. For those interested in how far AI can go beyond simple generation, our piece on the Forrester function offers a deeper mathematical look.
When AI Writes the Code, Do You Trust the Defaults?
AI assistants are remarkably good at writing code, but they don't always question the assumptions baked into the libraries they use. That gap is where subtle errors hide. This piece examines five scikit-learn defaults that deserve a second look before you ship. It's a practical, grounded reminder that trusting the tool isn't the same as understanding it. If you're building for production, this is worth your attention. For broader context on model deployment challenges, our related piece on real-world computer vision offers useful perspective.
Explore a complete ML learning journey from NumPy to Transformers.
Five months of daily commits is a serious signal. This isn't a weekend project; it's a disciplined path from NumPy fundamentals all the way to Transformers. For anyone feeling overwhelmed by the machine learning landscape, this public repo offers a practical antidote. It covers the essential ground: classical models, deep learning, and the data handling in between. It's a resource built by someone who did the work, and it's open for you to explore.

Visualize Neural Network Learning: An Interactive Exploration
A single hidden layer in a neural network doesn't just memorize points; it draws straight lines. With ReLU activations, one layer of width three can carve the input space into up to four linear segments. Stack another layer, and those segments multiply, so "3 3" can theoretically hit 16. The catch is that training rarely pushes the network to that theoretical max. It's a tidy, visual way to see why depth matters.
Speed Isn't Everything When AI Does the Work You Used to Own
One near miss, and four months of running agents left a writer asking a sharper question than any bug report: what are you supposed to do while the AI writes the code? The speed is real, but so is the quiet erosion of judgment. This isn't a warning against automation; it's a call to stay present in the loop. If you're navigating similar shifts, our guide to distributed training offers a practical foothold for keeping your skills sharp.
Navigating JMLR submissions with a cross-disciplinary advisor
A PhD student's supervisor is pushing for a JMLR submission based on tenure incentives, not fit. That tension is real. The student's experience with conferences mirrors what many face: reviewers asking for impossible proofs, with ACs unable to judge math. JMLR may offer better quality control, but the risk of a three-year review ending in rejection is valid. For applied stats work, it is worth checking scope carefully. If you are navigating similar pressure, our piece on practical AI deployment might offer perspective.
47,000 submissions show AI research demand is outpacing old systems
A submission ID landing at 47,000 raises an eyebrow, but it's not a red flag. ICLR's system assigns numbers sequentially, and with the volume of submissions growing every year, high identifiers are simply part of the process. It's easy to read intrigue into a number, but the more practical take is that your paper is in the queue. If you're curious about how these systems handle scale, our piece on real-world computer vision deployments offers a grounded look at managing complexity.
Is Reinforcement Learning Really Needed for Jev's Spreadsheet AI?
The question cuts to the heart of Jev's design. If the model only predicts Choice, Score, or Noul, those outputs are already differentiable through cross-entropy or MSE. Adding reinforcement learning feels like extra machinery unless there's a hidden reward signal we're not seeing. The environment would need to be defined, and that's unclear. It's fair to ask if this is substance or just a buzzword. We're not dismissing the approach, but the burden of proof is on the implementation.