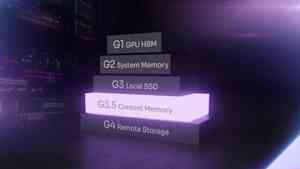
The rapid evolution of AI is consistently reshaping the technological landscape, and the latest shift highlighted by Solidigm's analysis is particularly noteworthy. We've moved past the era where simply adding more GPUs was the primary solution to AI performance bottlenecks. As inference workloads transition from simple queries to complex, persistent agentic systems, the limitations are now centered on managing the burgeoning context – the stateful information these systems need to retain across interactions. This isn't merely a technical curiosity; it signals a fundamental change in how we architect AI infrastructure. Why agentic enterprises need to become learning systems underscores the need for systems that can adapt and learn, and that adaptability is intrinsically linked to efficient context management. The emergence of a dedicated context tier, positioned between GPU memory and bulk storage, is a direct response to this escalating demand, and it's a development that enterprises can no longer afford to ignore.
This shift represents a maturing of the AI ecosystem. Initially, the focus was on raw compute power—training models was the priority. The storage architecture of yesteryear, designed for sequential, write-heavy training tasks, simply isn't suited for the fine-grained, latency-sensitive demands of inference. Recomputation is becoming a significant drag on GPU utilization, as systems resort to recalculating context that *should* be readily accessible. Solutions like Nvidia's CMX architecture and Solidigm's optimized SSDs are seeking to address this architectural gap. Furthermore, the move away from solely focusing on raw tokens per dollar towards "goodput" – useful tokens per dollar – reflects a more pragmatic and efficiency-driven approach. It's a welcome change that acknowledges the real-world constraints of resource utilization and cost optimization, as demonstrated by the innovative approaches detailed in No Claude Fable 5? No problem: Sakana achieves frontier performance with new Fugu multi-model, auto synthesis system, which highlights how efficient orchestration and multi-model systems can maximize performance.
The creation of a dedicated context tier isn't simply an incremental improvement; it's a structural change akin to the rise of object storage. Just as object storage fundamentally altered how we manage data at scale, this new tier promises to redefine the infrastructure requirements for enterprise AI. It necessitates a three-tiered approach to storage – GPU memory, the new context tier, and traditional network storage – and demands a focus on tail latency, density, and consistent performance. The emphasis on floating gate NAND, NVMe over Fabrics, and eventual CXL support further highlights the specialized requirements of this workload. This also has implications for budgets; shifting investment towards the context tier can reduce reliance on more expensive DRAM, offering a more cost-effective path to scaling AI capabilities. The shift highlights that AI infrastructure isn't just about raw power but about intelligent resource allocation and optimization.
Looking ahead, the standardization and best practices surrounding this new context tier will be crucial. Solidigm's engagement with standards bodies and research collaborations is vital in shaping the future of AI inference infrastructure. The question isn't whether AI needs more compute, but whether it can utilize existing compute more effectively. The context tier, by optimizing data access and reducing recomputation, holds the key to unlocking that efficiency. It's a nascent category, but one that's poised to become a permanent fixture in the AI landscape, and the companies that prioritize its development and integration will be best positioned to thrive in the coming years.